Given Claude Fable 5.2 can predict protein sequence, I was curious if it can predict structure.
I gave it a relatively simple prompt: "predict contacts, 2ndary struct, use dynamic prog. and linear alg. to predict structure"
It was able to predict fold of ubiquitin correctly 🤯
Claude Mythos Preview (18/60) hit rate, a LLM running those tools, its "not a specialized protein design model" like RFD4-Proteina, RFdiffusion or Latent-X etc. As a peer-reviewer i don't need that kinda comparison, so i removed it from that graph and now it make sense.
But then here's my question: Why was the experimental sample size so much larger for your method(rfd4-proteina)? Also What if you increase the sample size for all other methods?
Reading group today. RFD4-Proteina: 158 of 188 designed binders bound TrkA below 1 µM. Next best method: 18 of 60. Nate Corley and @DidiKieran will present https://t.co/YugqUrCSoN
On Zoom 2pm ET / 8pm CET: https://t.co/S7c2ei5mLR
We can now design all kinds of fancy de novo proteins. But can we produce them at scale, at a reasonable cost, and without extensive optimization? That’s what got this project started. Our preprint is now out! Much of the work was led by Selena @sesameandrea and Kaori. 1/8
Today we are excited to release Artios, a fully open source system for designing functional de novo enzymes.
Enzymes present a new frontier for de novo protein design models due to the challenge of coordinating precise chemistry, rather than binding a target.
Enzymes are life’s biological machines and by designing them we can truly start to engineer biology.
We believe these fundamental capabilities should be built in the open and shared with the community to progress science faster.
🧵 1/6
Public preview of BioEmu2! @MSFTResearch AI for Science’s new foundation model for biomolecular structure, dynamics and function. Open weights, MIT license.
https://t.co/wsqcLPh8Sk
Movie: BioEmu2-simulated binding of intrinsically disordered peptide PUMA to MCL-1 receptor. 🧵⬇️
Today we are launching RootPath BinderVerse, a cloud lab for AI-designed binders.
Sequence in, binding data out in as few as 3 days, gene synthesis time included! Antibodies and Fab fragments made with CHO cells (TAT from 6 days) and CAR-Ts made with primary T cells (TAT from 10 days) can also be created from your binder sequences and tested.
Trustable data at lightning speed -- Learn more at https://t.co/kPOYlK8KkM
ipSAEmin - i see it everywhere, each new paper, preprint or tool in binder design. I haven't been able to find a single study demonstrating that it correlates with affinity
✨Introducing Prompteina: all-atom protein design directly from natural language✨
- Control diverse protein properties through a single text prompt
- Higher predicted binding confidence than baselines
- First experimentally validated de novo binders reported for GM2A
🧵
@sokrypton Douglas Prasher’s GFP gene cloning was essential to the 2008 Chemistry Nobel (Shimomura, Chalfie, Tsien), but he left Woods Hole after funding dried up and tenure prospects collapsed, later driving a shuttle bus💔.
Introducing AlphaProtein Novo, a pipeline for de novo enzyme design! In collaboration with @francesarnold's group, we developed AP Novo and used it to get SoTA "novel-scaffold" activity on 2 benchmark reactions and create enzymes to synthesize the pharmaceutical motif piperidine and degrade the environmental toxin DEHP.
Work led by @ZvxyWu@ZiqiLi0513 with teammates @alexechu_@kelly_ruijie@schulluc@jacobjinkelly@rosaliags@davidla@solserpens@j_reisenbauer, @pengliu_group, Josh, Thomas, Amy, Tristan, Harshnira, and others. It was a joy and privilege to work with you all!
Preprints and code:
https://t.co/Q3aaoSAFcv
https://t.co/NTtjUmk354
https://t.co/RoA7wEfzYn
Biosecurity is too important for security theater.
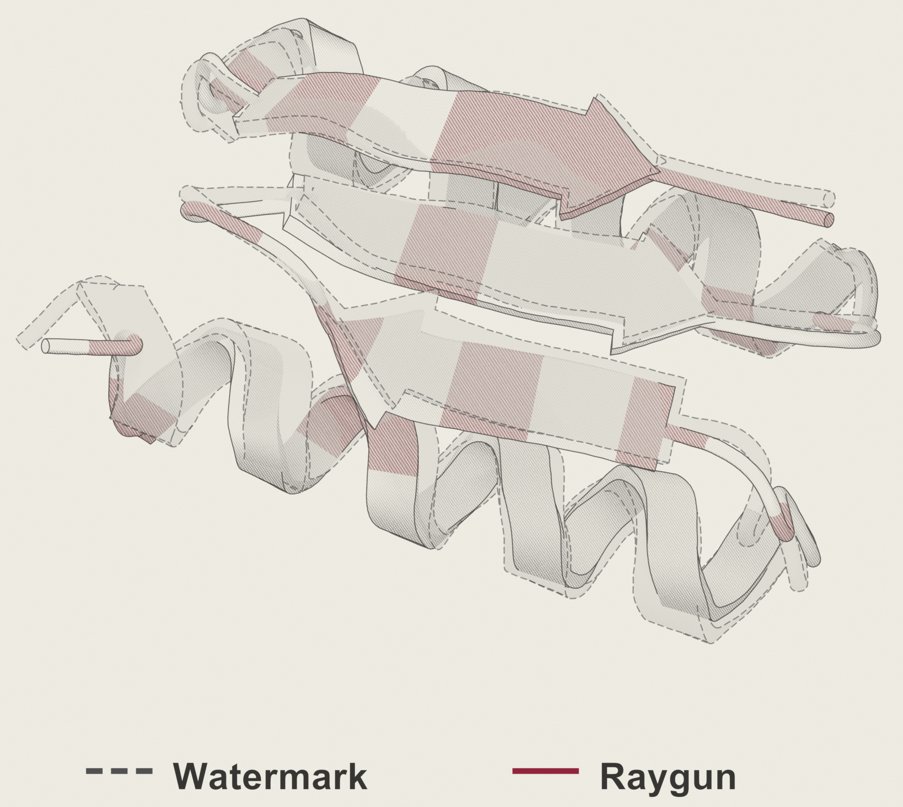
In a quick test with Raygun, we found that DeepMind's SynthIDBio watermark signal could be washed out while preserving the predicted structure.
We don’t think protein sequence watermarks buy much biosecurity.
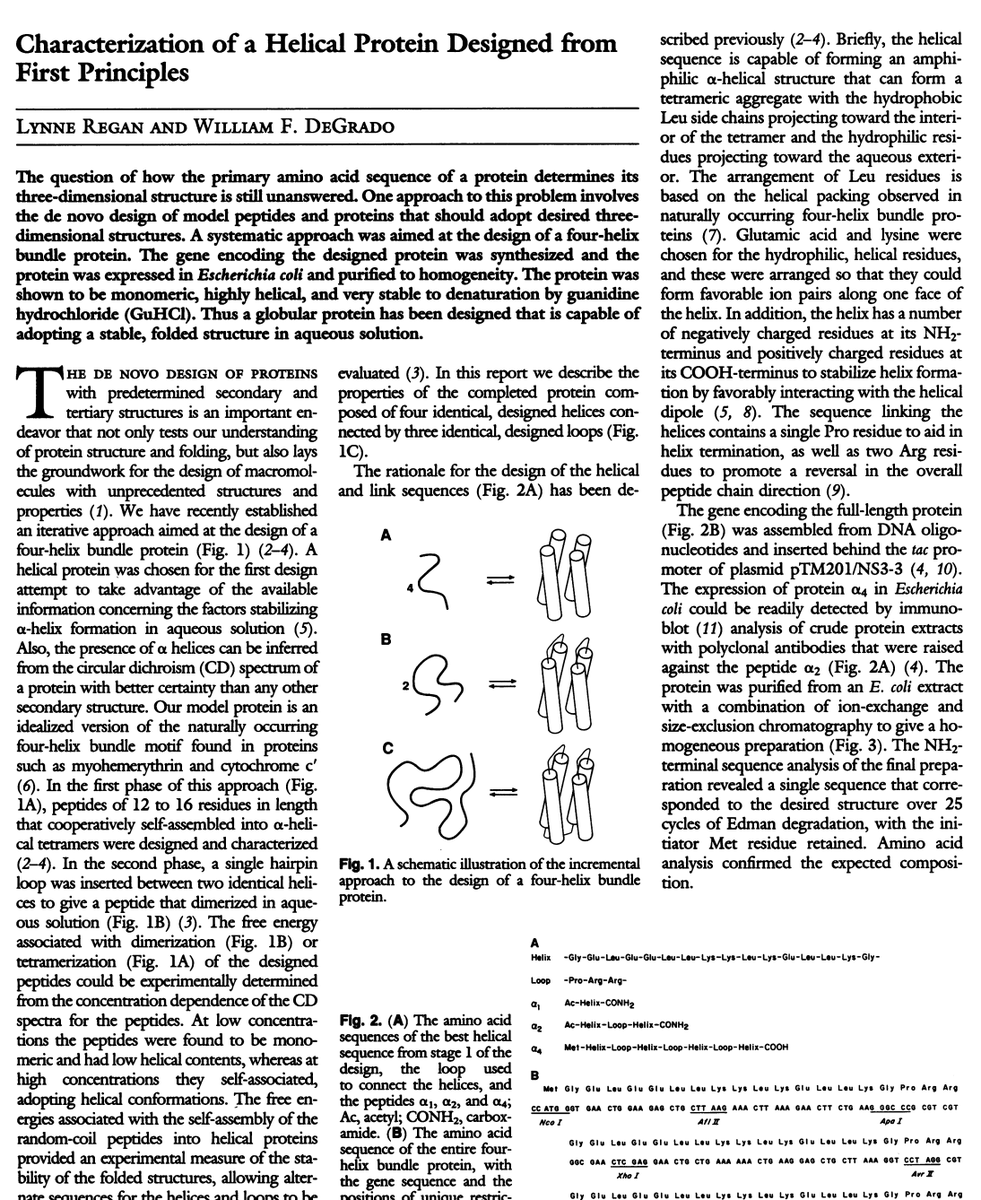
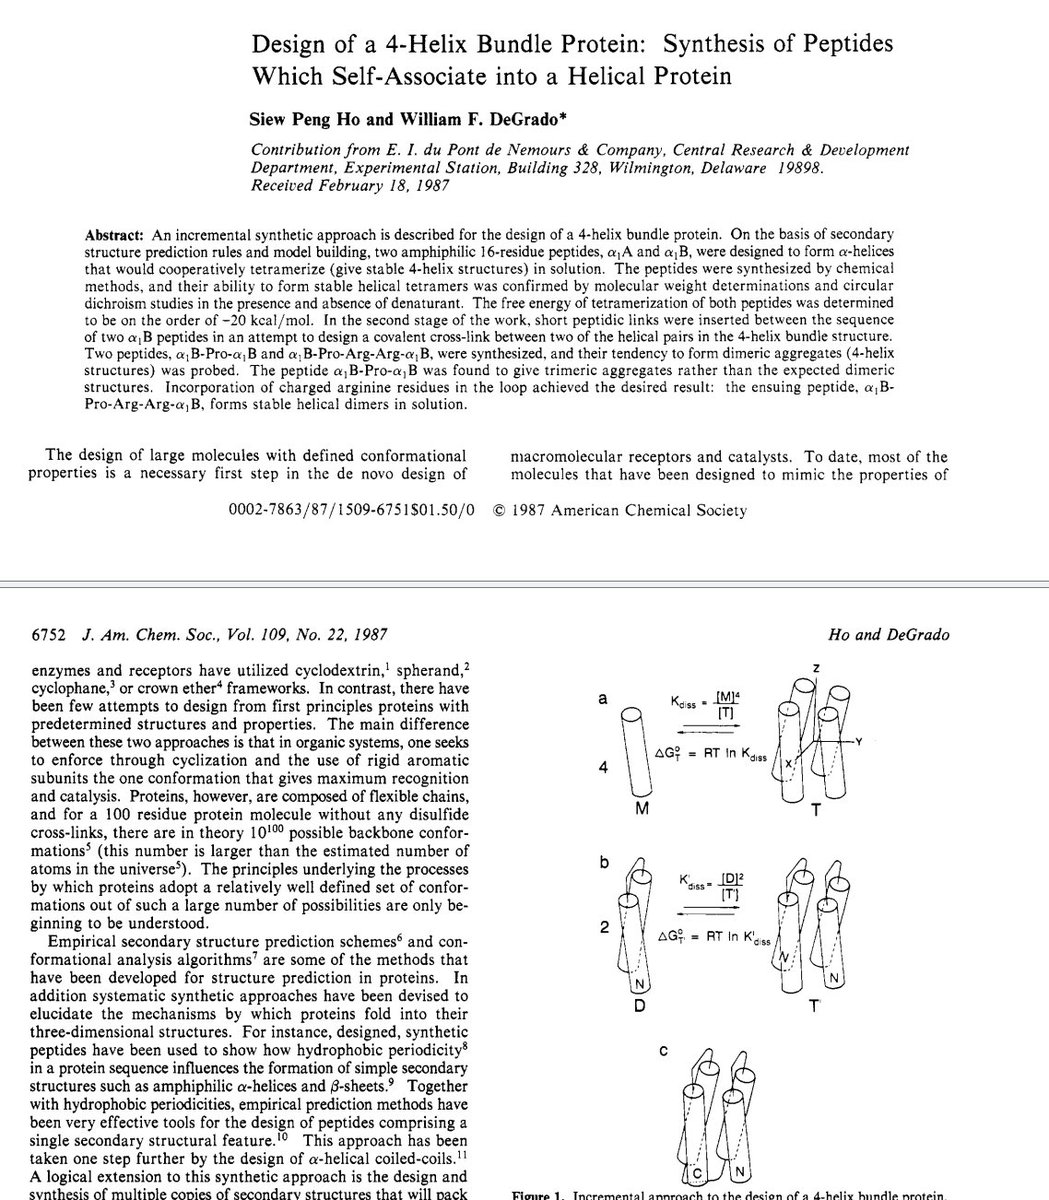
Before AI we designed them by hand. We placed hydrophobic residues like leucine on one face of a helix and polar ones like glutamate and lysine on the other, using physical models and secondary-structure rules such as; Physical CPK and Kendrew models for manual packing and Secondary-structure rules (Chou-Fasman). then synthesized the peptides chemically and checked if they folded and assembled. You can read that approach in 1987-88 DeGrado papers for the first stable four-helix bundles.
-Regan & DeGrado, Science 1988:https://t.co/QfRu4S9aYQ
-Ho & DeGrado, JACS 1987:https://t.co/SaIPAEGcah
-Gutte et al., Nature 1979:https://t.co/rObp8D7lBP
An interesting achievement but this statement is laughable. A strength of this field is how comprehensively the metadata create a paper trail that traces the DNA of a reading frame to EM/Xray-resolved polypeptides. We should be grateful this isn’t something we need to worry about