@SecDuffy Required family boarding for all airlines, have 1 sink with step up stool so kids can wash their hands, and changing tables in MEN’S and women’s restrooms. Chairs that spin are fun for the kids (like at SFO)
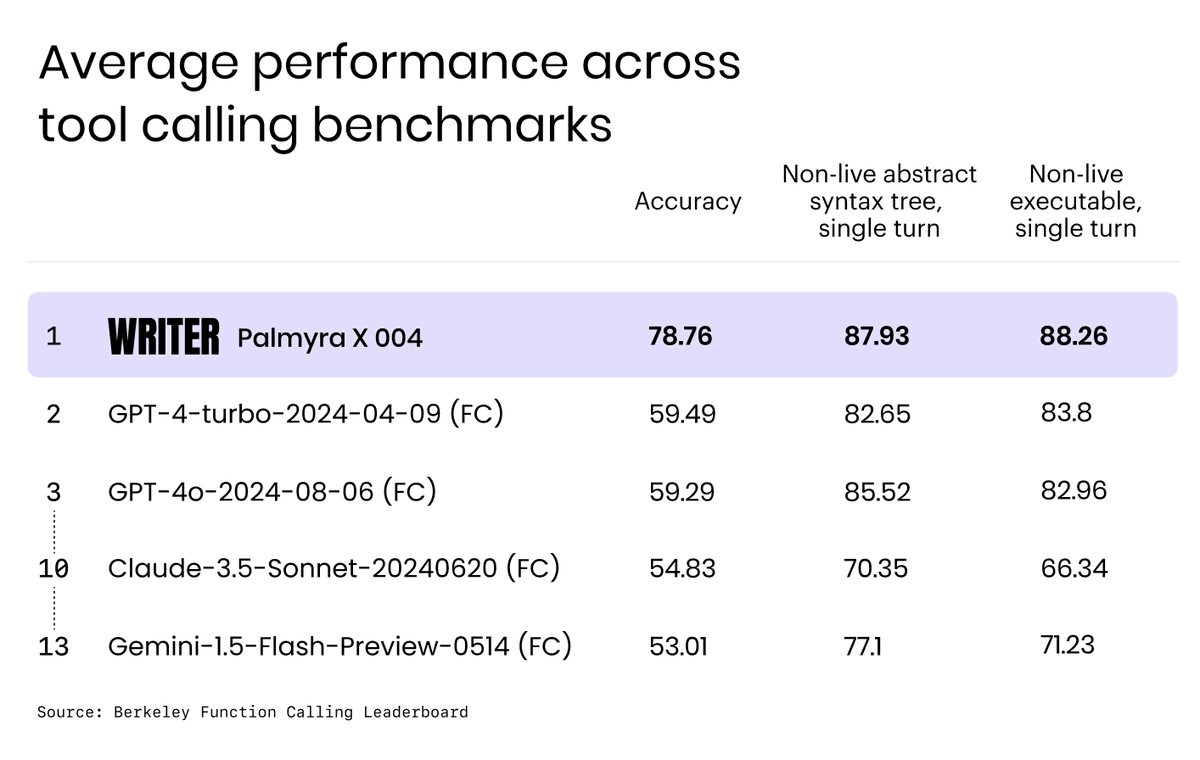
Lots of hype about @deepseek_ai and its R1 LLM released this week - but DeepSeek shouldn't be a surprise to anyone. In October, Writer released a top-benchmarked frontier model that cost $700,000 in GPUs to train, developed entirely with synthetic data.
In July 2023 we published research on how to develop these models with fewer GPUs. It simply doesn't take billions of dollars to achieve state-of-the-art model performance. Here’s the link to our research: https://t.co/RHXGIyjBM4
It really comes down to incentives. Our incentive is for our customers to run these models on their own infrastructure and in their own systems. We're a company, not a research lab. And for China and #DeepSeek, they were incentivized to find innovative workarounds given chip constraints. The biggest AI labs have zero incentive to prevent losing billions of dollars on training. They're playing a different game. If they had the same constraints and same goal, they would end up eventually at the same point.
@elonmusk@CRPakaluk ‘s research on the birth dearth argues tax breaks don’t incentivize women to have more kids, it only temporarily accelerates pregnancy for those already planning to have kids. Her book Hannah’s Children is a fascinating read on college educated women’s family growth
@TKL_Adam@Get_Writer (an American AI firm) made their AI model for even less than DeepSeek last year
Check out their CTO’s explanation https://t.co/VwtfYtJQFv
Lots of hype about @deepseek_ai and its R1 LLM released this week - but DeepSeek shouldn't be a surprise to anyone. In October, Writer released a top-benchmarked frontier model that cost $700,000 in GPUs to train, developed entirely with synthetic data.
In July 2023 we published research on how to develop these models with fewer GPUs. It simply doesn't take billions of dollars to achieve state-of-the-art model performance. Here’s the link to our research: https://t.co/RHXGIyjBM4
It really comes down to incentives. Our incentive is for our customers to run these models on their own infrastructure and in their own systems. We're a company, not a research lab. And for China and #DeepSeek, they were incentivized to find innovative workarounds given chip constraints. The biggest AI labs have zero incentive to prevent losing billions of dollars on training. They're playing a different game. If they had the same constraints and same goal, they would end up eventually at the same point.
@wordgrammer Not to mention American AI firm @Get_Writer developed their AI model for even less than DeepSeek did
Their CTO explains here https://t.co/VwtfYtJQFv
Lots of hype about @deepseek_ai and its R1 LLM released this week - but DeepSeek shouldn't be a surprise to anyone. In October, Writer released a top-benchmarked frontier model that cost $700,000 in GPUs to train, developed entirely with synthetic data.
In July 2023 we published research on how to develop these models with fewer GPUs. It simply doesn't take billions of dollars to achieve state-of-the-art model performance. Here’s the link to our research: https://t.co/RHXGIyjBM4
It really comes down to incentives. Our incentive is for our customers to run these models on their own infrastructure and in their own systems. We're a company, not a research lab. And for China and #DeepSeek, they were incentivized to find innovative workarounds given chip constraints. The biggest AI labs have zero incentive to prevent losing billions of dollars on training. They're playing a different game. If they had the same constraints and same goal, they would end up eventually at the same point.
@ryan_landay@SchutzPatrick@pitdesi Think about the legal hoops they’d have to jump through though to expand. Environmental reviews, etc. it would be quite the time and financial effort
Lots of hype about @deepseek_ai and its R1 LLM released this week - but DeepSeek shouldn't be a surprise to anyone. In October, Writer released a top-benchmarked frontier model that cost $700,000 in GPUs to train, developed entirely with synthetic data.
In July 2023 we published research on how to develop these models with fewer GPUs. It simply doesn't take billions of dollars to achieve state-of-the-art model performance. Here’s the link to our research: https://t.co/RHXGIyjBM4
It really comes down to incentives. Our incentive is for our customers to run these models on their own infrastructure and in their own systems. We're a company, not a research lab. And for China and #DeepSeek, they were incentivized to find innovative workarounds given chip constraints. The biggest AI labs have zero incentive to prevent losing billions of dollars on training. They're playing a different game. If they had the same constraints and same goal, they would end up eventually at the same point.
@natfriedman Sure, but America is also full of talented engineers. @Get_Writer built their AI model for $700k, their press just sucks.
https://t.co/VwtfYtJQFv
Lots of hype about @deepseek_ai and its R1 LLM released this week - but DeepSeek shouldn't be a surprise to anyone. In October, Writer released a top-benchmarked frontier model that cost $700,000 in GPUs to train, developed entirely with synthetic data.
In July 2023 we published research on how to develop these models with fewer GPUs. It simply doesn't take billions of dollars to achieve state-of-the-art model performance. Here’s the link to our research: https://t.co/RHXGIyjBM4
It really comes down to incentives. Our incentive is for our customers to run these models on their own infrastructure and in their own systems. We're a company, not a research lab. And for China and #DeepSeek, they were incentivized to find innovative workarounds given chip constraints. The biggest AI labs have zero incentive to prevent losing billions of dollars on training. They're playing a different game. If they had the same constraints and same goal, they would end up eventually at the same point.
@morganb Doesn’t have to be expensive. The team at @Get_Writer (an American AI firm) figured out how to do it for way less last year. Their CTO explains in technical terms here: https://t.co/VwtfYtJQFv
Lots of hype about @deepseek_ai and its R1 LLM released this week - but DeepSeek shouldn't be a surprise to anyone. In October, Writer released a top-benchmarked frontier model that cost $700,000 in GPUs to train, developed entirely with synthetic data.
In July 2023 we published research on how to develop these models with fewer GPUs. It simply doesn't take billions of dollars to achieve state-of-the-art model performance. Here’s the link to our research: https://t.co/RHXGIyjBM4
It really comes down to incentives. Our incentive is for our customers to run these models on their own infrastructure and in their own systems. We're a company, not a research lab. And for China and #DeepSeek, they were incentivized to find innovative workarounds given chip constraints. The biggest AI labs have zero incentive to prevent losing billions of dollars on training. They're playing a different game. If they had the same constraints and same goal, they would end up eventually at the same point.
On the CA fires, and ***REBUILDING***
I'm not a Blue Check but hopefully this post will be amplified by others with more reach.
The screenshots I'm sharing are from a former boss and friend of mine whose home was lost to a fire a few years ago.
He's giving great advice:
“We feel that the Dutch National Olympic Committee have explained their decision [to enter Steven van de Velde]. We feel that the statement that they've given us is correct.”
- Mark Adams, IOC spokesperson
The IOC showing time and again they do NOT stand with women and girls ⬇️
Van de Velde arrives in Paris, reports say chaperoned by armed police in anticipation of an angry reception. If only his victim was afforded such protections. Silly me, that’s just for convicted child rapists who believe they have a right to be Olympian role models…
Many are missing the point with the Van de velde case. Here are some highlights of my own thoughts....feel free to add your thoughts in the thread 🎤
- he raped a child. This should automatically remove priviliges, such as the Olympics (biggest stage in the world). He is not a hero.
- him being on the Olympic stage green lights a very dangerous conversation with other perpetrators seeing a convicted child rapist in this way; going for GOLD.
- he will be mixing with survivors of CSA and therefore triggering them, potentially reducing their ability to perform because of 'what the trauma of him being at this event' would mean to their pyschological state.
- the decision made to allow VDV to take part in this global event is reducing the protection toward children and the conversation of child abuse today, and ongoing.
- this is about children. NOT VdV. It could be any offender, it just so happens to be him.....and of course, he is the one we can see....
#campaigner