STOP DOWNLOADING LLMS YOUR MACHINE WAS NEVER GOING TO RUN
LLMFIT is a new open-source tool that scans your hardware first, then tells you exactly which models will actually run well on your setup.
It inspects:
→ RAM
→ CPU
→ GPU(s)
→ VRAM / unified memory
Then it scores every model across four dimensions:
→ quality, based on parameter count and quantization
→ speed, estimating tokens per second for your exact backend
→ fit, matching memory usage to your hardware
→ context window support for your use case
Each model then gets a clear label: Perfect, Good, Marginal, or Too Tight.
It also picks the best quantization automatically, stepping down until something fits instead of leaving you to guess GGUF sizes by hand.
Coverage is broad too! 100's of models from Meta, Mistral, Qwen, DeepSeek, and more.
It works with Ollama, llama.cpp, MLX, and LM Studio out of the box.
And that’s not even it!
There’s also a lightweight TUI, a web dashboard, and REST API endpoints if you want to plug it into orchestrators or deployment pipelines.
This should be step zero before every local model download :)
100% free and open-source. macOS, Linux, and Windows.
Repo in 🧵↓
I'm officially done reading AI-generated code.
It's been two weeks since I looked at any of it.
I think the IDE is officially on its way to the graveyard. The job is no longer about "writing code," so we need new tools that better reflect this new reality.
While reviewing the code, I realized my only complaints were stylistic, and I wasn't finding any obvious bugs anymore.
The more code I generated, the harder it became to keep track of every line. I found that my time is better spent designing ways to verify that the overall system works than looking at the code.
State-of-the-art coding agents are better at writing code than I'd ever be, and I'm going to stop pretending otherwise.
I still think these coding agents can't go too far without an experienced human guiding them, but we're past the point where we need to check every line of code.
विजयी विश्व तिरंगा प्यारा, झंडा ऊँचा रहे हमारा
@ISRO represents the best of India. Humble, hardworking women & men, coming together, overcoming challenges, and making our tricolour fly high.
India must celebrate and congratulate the Chandrayaan-2 team, which was led by Shri K Sivan, along with Shri S Somanath’s #Chandrayaan3 team.
Every hard landing has lessons which take us closer to a soft landing - on the moon, and in life.
Jai Hind! 🇮🇳
ZEDEDA has partnered with @ROKAutomation to help manufacturers accelerate their #digitaltransformation. This partnership will extend cloud capabilities to the edge! Check it out:
https://t.co/ufD1n8PeAL
We've signed a multi-year OEM agreement to supply @VMware with our award-winning #edgeorchestration solution as part of VMware Edge Compute Stack! https://t.co/CZQl6nUEje
The 3-2-1 Thursday newsletter by @JamesClear is full of wisdom and practical insights. This weekly email will become a highlight of your inbox: https://t.co/kczpp1JEal
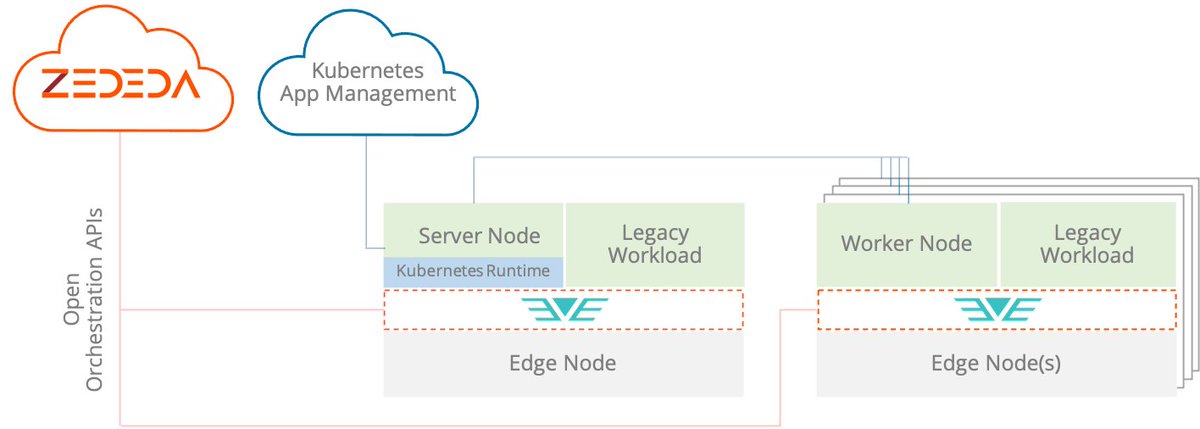
"Today, ZEDEDA has added #Kubernetes support that incorporates the ability to abstract all the complexities of remotely provisioning Kubernetes #clusters at the #distributededge while automating clusters on target edge nodes within minutes." https://t.co/yIELdFpWZd
Why is a secure, zero touch #Kubernetes orchestration solution unique for the edge? How does it simplify the deployment of Kubernetes clusters in the field?
Read below to understand the magnitude of this release for the #edgecomputing industry.
https://t.co/i6apj5Riju
In today's cabinet meeting chaired by CM @BSYBJP it has been decided that from May 1, Covid19 vaccination will be provided free of cost to citizens between 18-44 years at all Govt vaccination across the state.
I appeal to all eligible citizens to register starting from April 28.
Thanks to PM @narendramodi's sustained efforts to strengthen Indo-US bilateral ties and mutual co-operation, the USA agrees to supply raw materials for production of Covishield vaccine.
@PMOIndia@DrSJaishankar
https://t.co/6xFUBOTSdL