PhD student @S3DatCMU @SCSatCMU researching Human-Centered AI Engineering. My work empowers humans to understand, engineer, and use AI models and systems.
Sharing our work at #EMNLP2023: *Beyond Testers’ Biases: Guiding Model Testing with Knowledge Bases using LLMs*
TL;DR: We help LLM practitioners systematically *elicit requirements* to explore model behaviors and conduct testing, with LLM-generated KB.
https://t.co/MucbZLz0Y0
1/n
Try it on https://t.co/Xmjb9TddPw and to play against one of our best models!
We gave open-source decision models two games. It did not go well. 🫠
🎮 Red Alert 2: the base model sold its own base. Then lost.
💥 Tank War: v1 spun in circles. v2 found the fire button… and shot itself.
So we let them keep learning: play → train → upgrade the harness → repeat. A few rounds later: model can evolve without human intervention
Then we put different models in one arena and let them fight it out. So far, no human has beaten the trained models. 😅
The lesson: a decision model isn't finished when it's released. Real environments keep throwing new situations at it, and a frozen model can't adapt. It needs continuous learning!
It's all open source: how we train these models to play, end to end. Next, we're turning it into training infra for any decision model.
⭐ Star it, fork it, or bring your own model to the arena:
GitHub: https://t.co/oAPAOkBRn0
RA2: https://t.co/xMv6VNaE11
Tank War: https://t.co/xttz2fjeWe
I also appreciate all the suggestions and feedback from: @b_vasilescu , Greg Ganger, @p0nk , @lateinteraction , @matei_zaharia , and @heathercmiller
And thanks to all the Contributors to the demo and the github repo!: @Jayzou3773, @brocoliman38951,
@ShangyinT , @Xuan04263449 , chenyang yang, tianyu chen , @AlexZhang152005, @Nickzz12138,@JasonWuzh, @Leow_sss730, @ChenMoneyQ , xingyuan ding, @JunchengLi , @LakshyAAAgrawal , @ao_qu18465
📢 Calling for ML practitioners, researchers, & students!
We invite you to join our 60-min user study on our new LLM-powered tool for ML evaluation. Enjoy a $35 Amazon gift card as a thank you!
Sign up: https://t.co/stROISZ3AA or email [email protected] for details.
ML models make mistakes, but how do we understand and analyze their average behaviors?
Check out our #ASE2024 paper w/ Yining Hong, @GraceALewis, @tongshuangwu, Christian Kästner @p0nk on semantic data slicing.
Presenting today at 10:30AM in Compango!
https://t.co/JUpvAbQslp
🤝 New work on LLM for code optimization with @allen_a_nie, @brohanster, and amazing teams at Stanford, Intel, NVIDIA, and Visa Research. We show how LLMs can generate system code that outperforms human experts in parallel matrix multiplication. 🧠🔧
🔗 https://t.co/n3S1FREtIn
What challenges do developers face while using AI programming assistants like GitHub Copilot? 🤖🤔
Check out my #ICSE2024 paper (w/ @cyyang3_u and @bradamyers)! I'm presenting this work today at 4:15PM in the Fernando Pessoa room. See you there 🤗
https://t.co/GtoIlURgeN
Try Weaver for your own task: It is available at https://t.co/OWoXyF5gTU
This work was done with my great advisors @p0nk@tongshuangwu and collaborators @GraceALewis.
I’m also at EMNLP’23 now — feel free to reach out and chat!
6/n
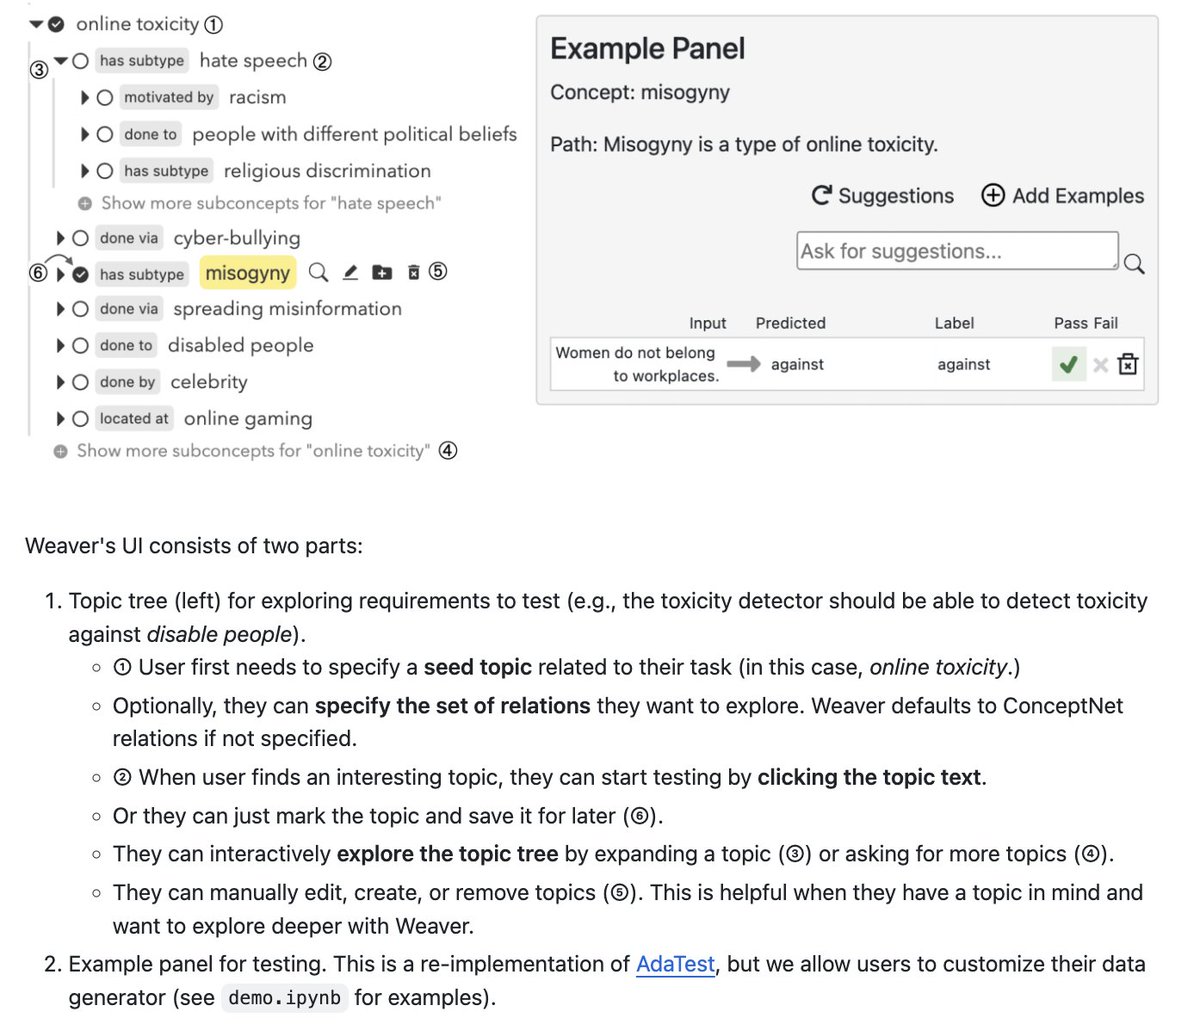
Weaver works with any domain tasks: A user first specifies a seed concept relevant to their task, and Weaver will build a knowledge base by querying an LLM and then recommend a *relevant yet diverse* subset to the user. Users then can explore the KB interactively.
4/n
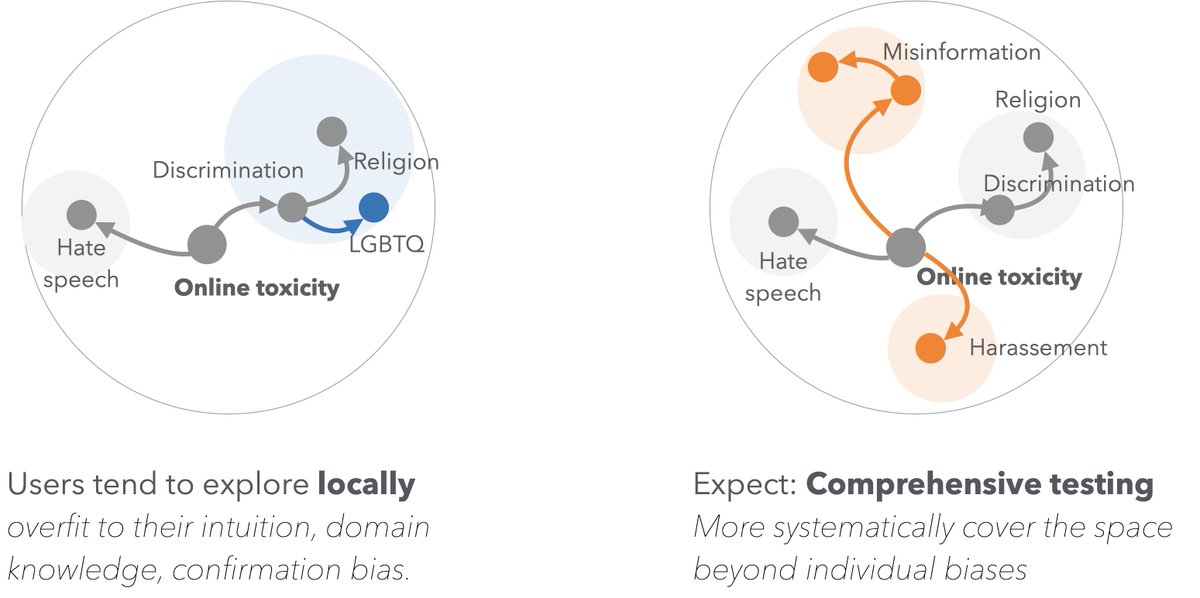
Our user study found that Weaver helps users explore more systematically, test more diverse concepts, and identify bugs beyond their biases.
We also conducted two case studies with LLM practitioners, finding Weaver helps them test & iterate prompt(s) for their applications.
5/n
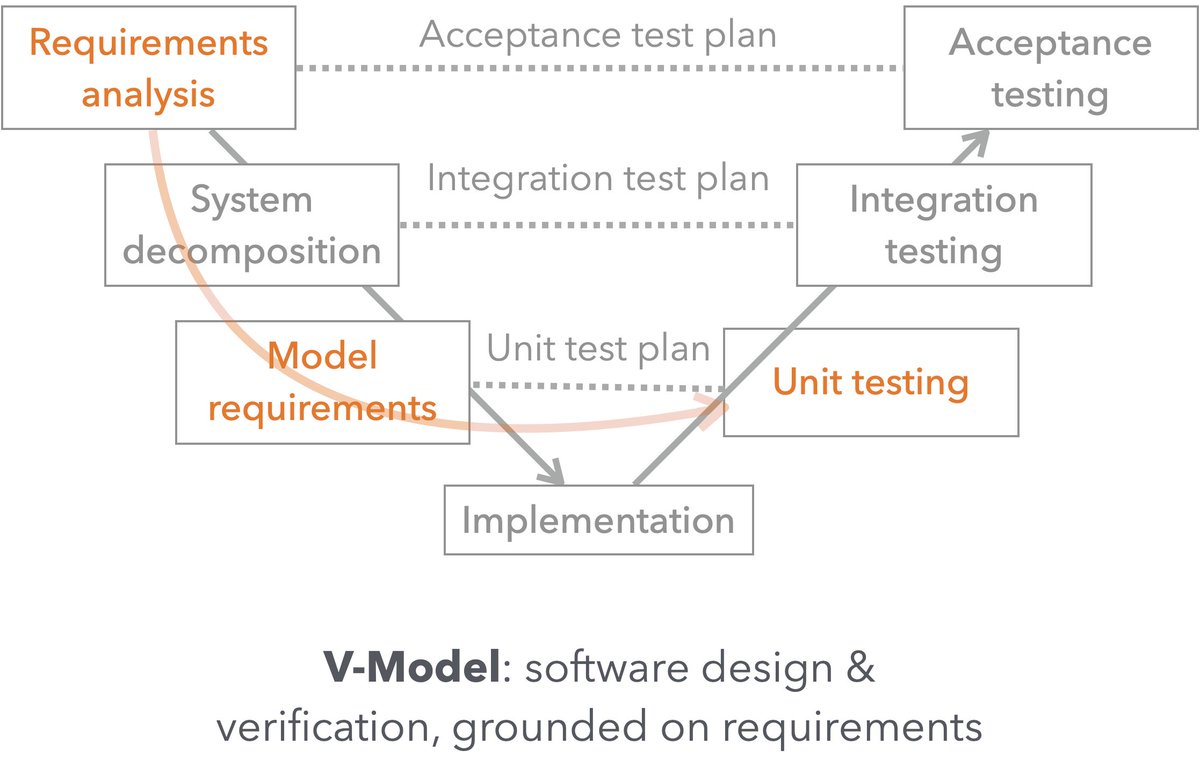
In this work, we take inspiration from *requirements elicitation*, a long-established process in software engineering. We build Weaver, a system that explicates and scaffolds requirements elicitation for model testing.
3/n
As LLMs are increasingly deployed in new applications, developers often need to do *behavioral model testing*, where they curate & analyze examples to understand prompt(+LLM) behavior for their uses.
However, developers tend to do this ad-hoc, overfitting to their own prior.
2/n
Sharing our work at #EMNLP2023: *Beyond Testers’ Biases: Guiding Model Testing with Knowledge Bases using LLMs*
TL;DR: We help LLM practitioners systematically *elicit requirements* to explore model behaviors and conduct testing, with LLM-generated KB.
https://t.co/MucbZLz0Y0
1/n
Tagging @ujimagic who did the actual work🤪 Check out our position paper on how *model capabilities* (that @marcotcr et al. used in CheckList) can potentially have a broader impact on AI Engineering in general - And @p0nk has the best course on this topic! https://t.co/MKR9ciQv4P