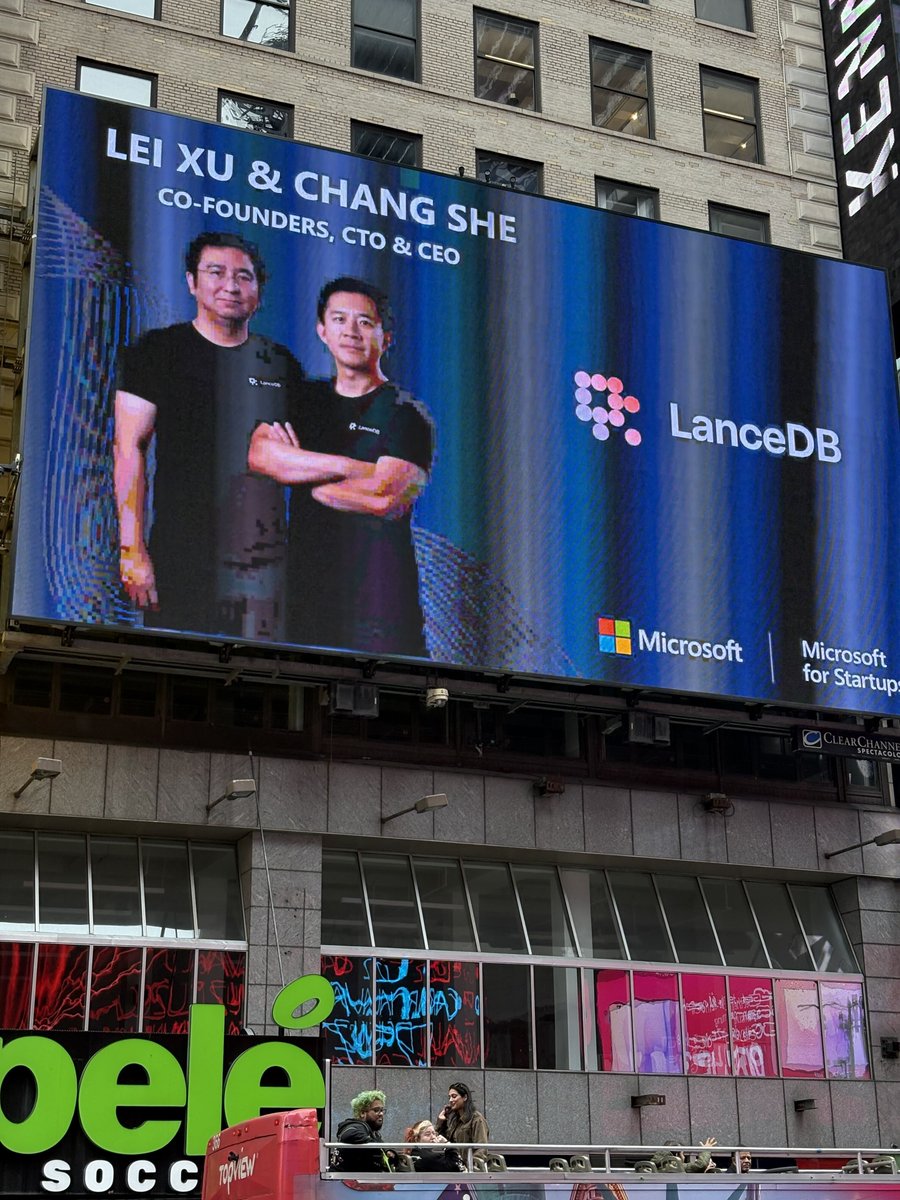
LanceDB is in Times Square. 🗽
@msft4startups is featuring us as part of its invite-only Pegasus Program.
A big milestone as we keep building the new foundation for AI data.
https://t.co/it4jWgC0aL
#MicrosoftForStartups#BuiltWithMfS
LeRobot now natively supports @lancedb datasets, with fast training and global shuffling directly from HF Storage Buckets - no need to download the dataset first 🚀
From vector & full-text search to curation & mining, discover what you can unlock with LanceDB + LeRobot 👇
We teamed up with 🤗 @huggingface on a new guide to using LanceDB as the data backend for LeRobot.
Train directly from object storage, use vector + full-text search for curation and mining, and avoid stitching together separate systems as robotics datasets scale.
https://t.co/weqoyFtX4a
LeRobot now natively supports @lancedb datasets, with fast training and global shuffling directly from HF Storage Buckets - no need to download the dataset first 🚀
From vector & full-text search to curation & mining, discover what you can unlock with LanceDB + LeRobot 👇
We’re starting a new series called Feature of the Week 🎉
This week’s feature by @Yah01_: Index prewarm now reads in parallel bytes windows. Loading a billion-vector index into memory used to take 95 minutes, now it takes 3.
The best kind of work almost always comes from collaborations!
This time @loldedxd helped me figure out the internal workings on funes. While I knew how to make funes work, he made sure I understand how things run on my system.
It is a fun 30 mins read.
https://t.co/RWY48MyhD9
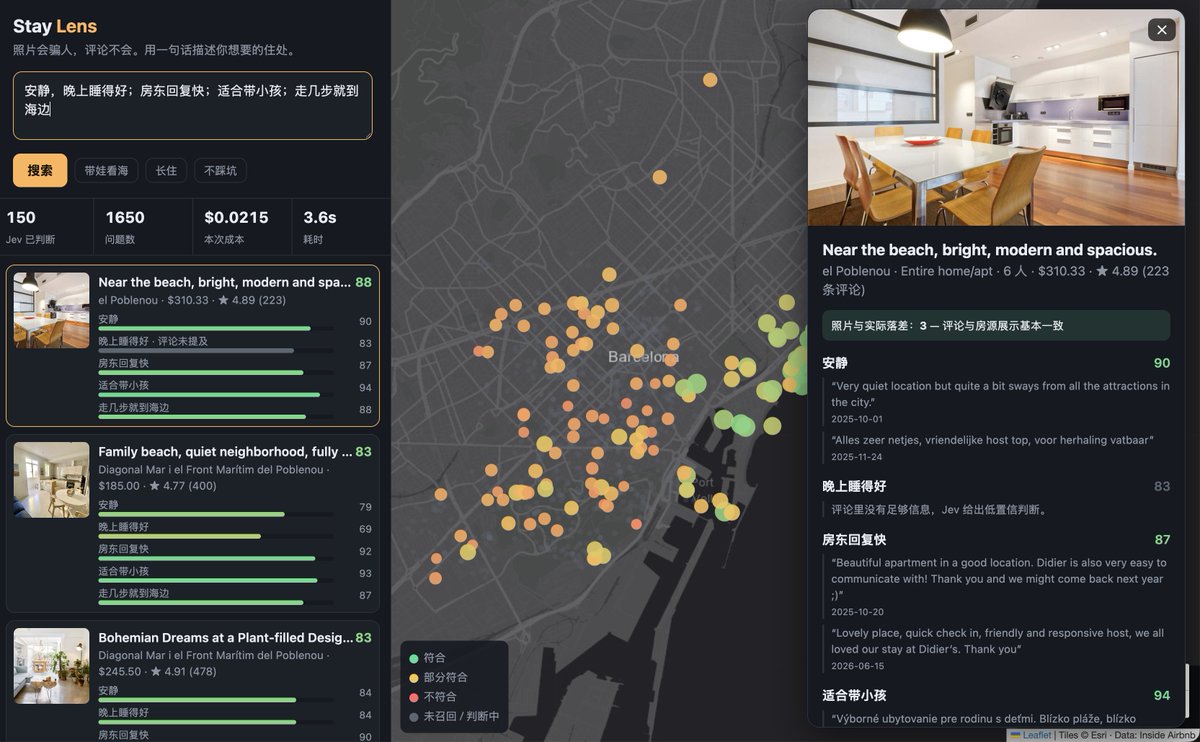
Built a cool semantic lens based on @typesafeai's Jev and @lancedb.
Now, we can do semancti filter nearly realtime, no need to predefine features anymore. Just search and explore!
Here is the demo: https://t.co/FMbggHscXr
Have fun!
Weston Pace (Software Engineer @ LanceDB, Apache Arrow and Substrait PMC) keynotes CDMS 2026 on how composable data systems hold up when the users are agents and, increasingly, so are the contributors.
Sept 4, Boston, co-located with VLDB 2026
Data loading for ML is simple in theory: keep the GPU fed.
In practice? I/O, transforms, parallelism, shuffling, caching, and bad defaults can all get in the way.
Weston Pace wrote a deep dive on building efficient data loaders with @PyTorch + LanceDB.
https://t.co/eJbcmECKpS
Every generative model is a kind of dream, rendered from what it has seen.
Introducing Reverie, LanceDB’s summit on the data systems those dreams are made on.
Nov 5 in SF, with speakers from @nvidia, @runwayml, @LumaLabsAI, @AppliedInt, Cruise by @GM, @Adobe, @ExaAILabs + more.
https://t.co/FtD9MhxMas