The loudest voices stoking fears about AI dangers have made tremendous headway in the past two weeks. AI technology has not taken some unexpected, dangerous turn, but the hype around it — propelled by what appears to be a well orchestrated PR campaign — has drummed up considerable fear. I worry that it represents a setback for our field.
I have written frequently that fears of AI are overhyped. AI’s capabilities can be uncannily human-like and unpredictable, and it’s rational to worry when people who are directly involved express concerns. But I see the problems as a sign of the engineering work that ahead, rather than insurmountable barriers or the sky falling. AI technology continues to advance — which is a good thing! — but technical advances, poorly understood by the public, give those who seek to generate hype repeated opportunities to do so.
First, I don’t see any step up in the risk of human extinction from AI compared to a few months ago. The theories about this remain the same fantastical, science fiction scenarios as a few months ago. The biggest change in AI risk is its cybersecurity capabilities — a topic which we should take seriously — but this, too, will not lead to the end of the world.
The most notable recent event leading to increased fear was when an OpenAI team deployed an agent swarm that hacked into Hugging Face. Much of the popular press contained significant hype. For example, some publications reported that a swarm of 1,200 agents carried out the attack. While this was technically accurate, as I write this, I have about 1,300 processes running on my laptop. Yes, the ability to get large swarms of agents to work in parallel on a task is a significant technical advance, And, in computing, many processes run at the same time. So this shouldn’t be seen as some magical capability.
Additionally, OpenAI’s buggy sandboxing and monitoring processes were key to enabling this incident. Fixing these bugs and putting in place improved monitoring would be appropriate fixes, not pausing AI. There are many well known ways to attack software systems. The main advantage of AI agents is that they are relentless. They will tirelessly try many tactics — and have the patience to chain vulnerabilities together — that previously would have taken an infeasible amount of human effort. But in the long term, I believe the advantage will lie with defenders (because they have more information with which to identify bugs, which they can fix), but the cyber-threat landscape has changed significantly. There are still bottlenecks to identifying and exploiting a vulnerability. AI agents still have to try a lot of things to see what works, and taking these actions takes time and might be detected by defenders. This is why, even though it is now easy to obtain versions of leading open weight models that have had their guardrails removed or weakened, so they will not refuse to try to execute cyber attacks, the world has not ended.
I am also concerned about the anthropomorphization of AI in a lot of reporting, where LLMs and agents are unnecessarily treated as if they were people. If I wield a hammer, miss a nail, and accidentally dent the wall, it’s not the fault of the hammer. The problem lies in how I used the hammer. Similarly, if I prompt an agent and it hacks into someone else’s system, the responsibility lies with me, not the agent.
Of course, we want to build systems that are as safe and predictable as possible. (For example, an unsafe hammer would be one whose head randomly flies off under normal use.) Today’s agentic systems are not predictable, but I see no reason why, by applying sound engineering practices, we won’t be able to make them extremely safe to use. One new element in the forecasts of AI-enabled doom is AI companies disclaiming responsibility for their own products. “I didn’t do it; my out-of-control agent did!” There’s a balance to be struck between the responsibility of the tool maker and the tool user, but when something goes wrong, let’s hold the people building and/or using the hammer responsible, rather than the hammer. (By the way, if you’re worried about AI bioweapon risk, David Bellamy has a great post on why this, too, is overhyped. Briefly, the bottleneck in building a bioweapon is not intelligence, but lab work and manufacturing.)
Pausing AI progress will create much more harm than benefit. First, our adversaries will certainly not slow down. Second, engineering requires discovering problems empirically so we can fix them. If we pause AI by a decade, we will also delay finding and implementing safety engineering fixes by about the same duration.
Of course, the incentive to stoke fears — for regulatory capture, to garner attention, or to make one’s technology seem more powerful — remains the same as before. Disclaiming responsibility is a new one. Taking a hard technical look at the actual risks however, I see little factual basis for the degree of fear that’s been stoked up. We still have hard research and engineering work ahead to improve AI safety, but the beneficial applications continue to vastly outweigh the risks, and we should keep building.
[Original text (with links): https://t.co/jni2tWazAH ]
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.
Fast, lift, sprint, stretch, and meditate.
Build, sell, write, create, invest, and own.
Read, reflect, love, seek truth, and ignore society.
Make these habits. Say no to everything else.
Avoid debt, jail, addiction, disgrace, shortcuts, and media.
Relax. Victory is assured.
LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
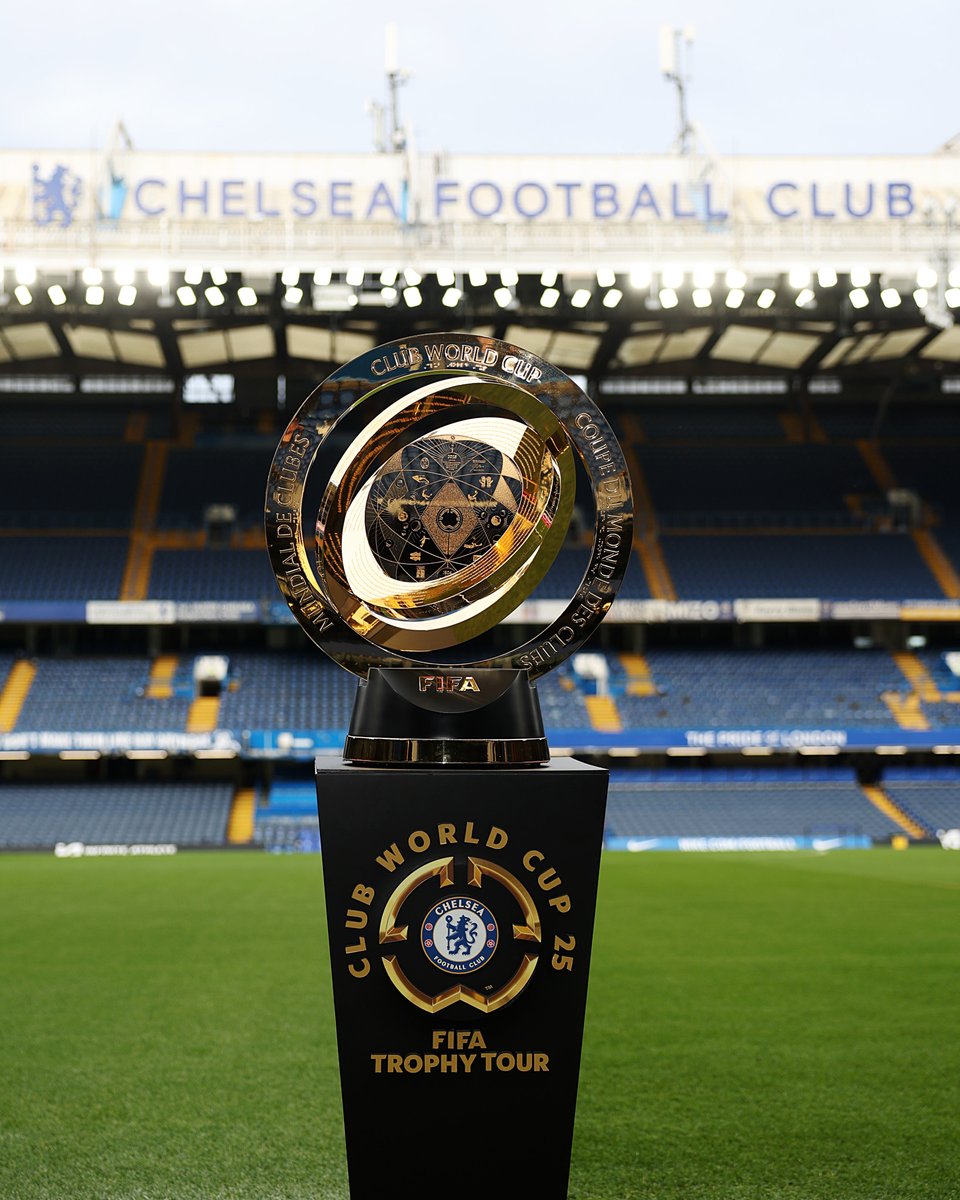
Come and visit London’s Home of Trophies. 🏆
Book your Stadium Tour at Stamford Bridge now. ⭐️⭐Come and visit London’s Home of Trophies. 🏆
Book your Stadium Tour at Stamford Bridge now. ⭐️⭐Come and visit London’s Home of Trophies. 🏆
Book your Stadium Tour at Stamford Bridge now. ⭐️⭐Come and visit London’s Home of Trophies. 🏆
Book your Stadium Tour at Stamford Bridge now. ⭐️⭐Come and visit London’s Home of Trophies. 🏆
Book your Stadium Tour at Stamford Bridge now. ⭐️⭐Come and visit London’s Home of Trophies. 🏆
Book your Stadium Tour at Stamford Bridge now. ⭐️⭐️