New research from Adaption presents adaptive agentic checklist generation.
An agent builds a quality checklist from past AutoScientist runs. The checklist scores and removes bad training data.
Model performance improves every run.
Generated videos are getting so good.
One of the @adaption_ai team put this together as an explainer of invent a dataset. 🔥
The biggest hurdle in frontier AI is curating high-quality, diverse data.
Invent solves for this zero data regime.
AutoScientist accelerates and derisks frontier model training.
See the results: the AutoScientist Leaderboard ranks the best customized models per domain.
44 domains. Legal, health, finance.
Your Frontier. Not Theirs.
Singapore here I come. 17h flight ahead.
A very busy week ahead representing @adaption_ai .
But I will make sure to accommodate plenty of room for chilli crab. 🦀
It was great to spend time today at @Berkeley_EECS interacting with students in @nilou_slh s continual learning class. One of the key ideas we discussed is the diffusion of learning beyond the model as a central artifact of an intelligent system.
Adaptive Interfaces feed user corrections back into a model, so AI keeps improving after deployment.
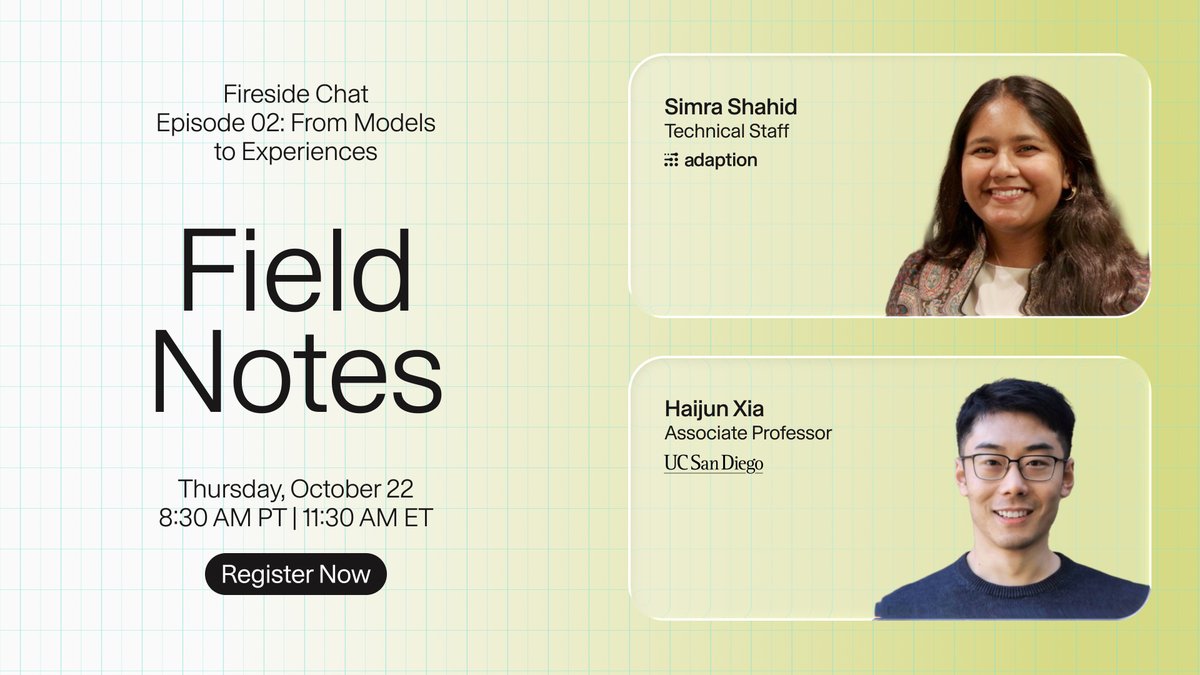
Join @its_sshahid, Technical Staff at Adaption, and @HaijunXia, Associate Professor at @UCSanDiego on October 22nd.
This report provides very interesting results, for example: when asked to generate 20,000 training examples instead of 2,000, Claude produced less varied data. Adaption’s dataset generator, Invent, produced more variety.
Ten times more examples doesn’t guarantee ten times more to learn from!
Nice work, Sara and team!
Pretty cool work from @adaption_ai that showcases their InventAPI to generate Diverse + Qualitative datasets from prompts
A good reminder of metrics to evaluate that, notably in quality and diversity
Currently mainly for QA + multi-turn non-agentic interactions, but I’m sure this will evolve in a really cool direction
We recently launched Invent-a-dataset that allows creating post-training datasets using just a natural language description 📖 🖊️
Today we share an extensive technical report evaluating Invent API against using frontier proprietary and open-weight LLMs for data generation ✨🧵
Introducing Invent A Dataset
From a single dataset description to training-ready dataset
https://t.co/0ILXBuEN3b
Huge thanks to my wonderful collaborators: @singhshiviii@lekeonilude@sarahookr@sudip_r0y
Key takeaways: 🧵
Scarcity of data has always been a massive bottleneck when it comes to building enterprise-sovereign AI systems.
Invent-a-dataset changes the game and represents a massive unlock in allowing anyone to create an AI-ready dataset.
The biggest hurdle in frontier AI is curating high-quality, diverse data.
What happens if you need to post-train a model for a new capability, but have zero data?
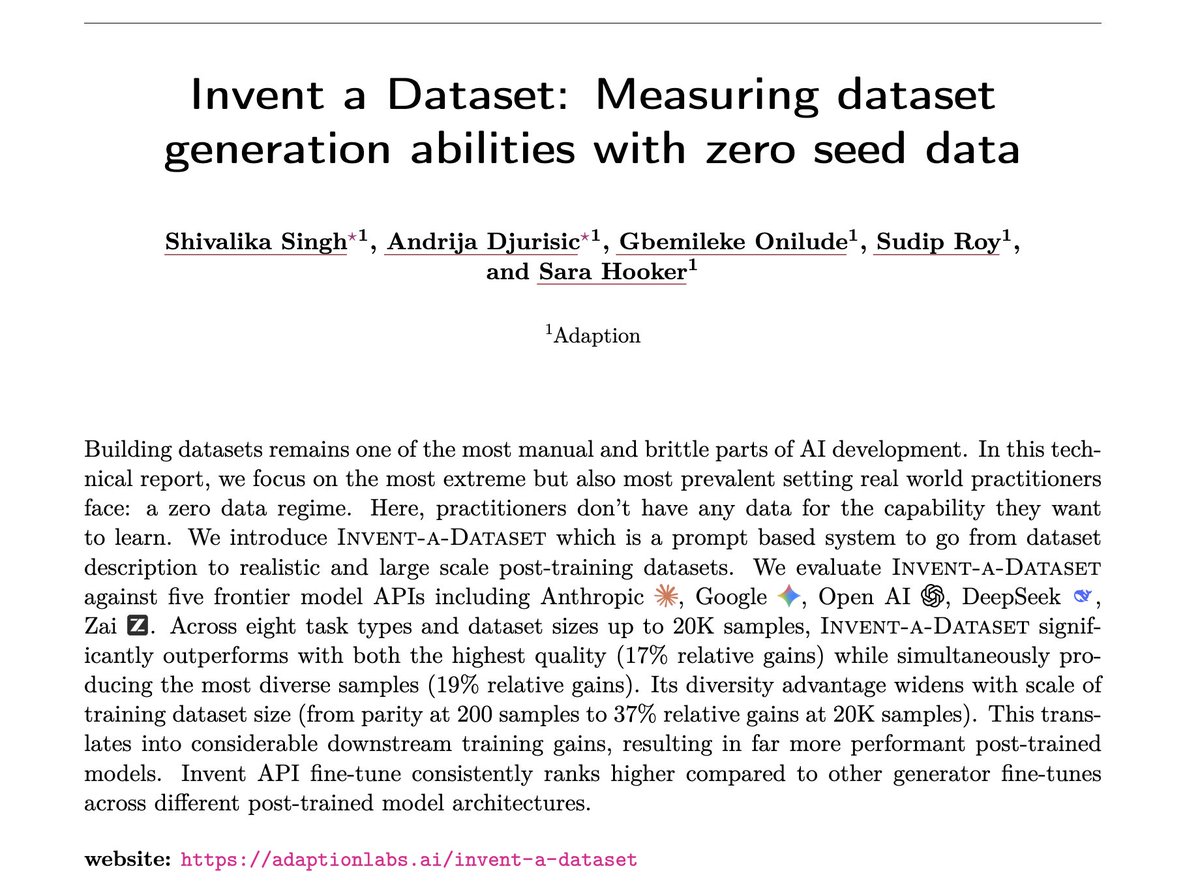
Today, we release the technical report for Invent a Dataset.
Creating a dataset that is high-quality and diverse is an extremely difficult task. Check it out the tech report that for Invent-a-Dataset with amazing results from the team! Huge shoutout to @singhshiviii, @andrijazzz, and @lekeonilude 🎉🙌
> We introduce Invent-a-Dataset which is a prompt based system to go from dataset description to realistic and large scale post-training datasets.
Soon we will be describing the datasets we want to post train by synthesising data from said description, adaptive specialisation always wins for specific domains!
@sarahookr and @singhshiviii and others had their hands all over this so definitely check it out.
I was so many times thinking "if I only had the right data, I could train/build XYZ"... Well, this makes generating datasets much easier.
Congrats @andrijazzz@singhshiviii@sarahookr@sudip_r0y on the release!
Please take a look at our Invent-a-Dataset technical report, an one-of-a-kind approach to data generation you can use today on our platform! Big congrats to @singhshiviii@andrijazzz, and @lekeonilude on the release.