GPT 6.2 is BY FAR the LAZIEST FUCKING SHIT i have ever tested
excuse my french but FUCK ME MAN every time i give this model another shot i crash the fuck out
absolute disgrace of a model
literally EVERY interaction with this fucking model is:
You: hey we have problem check it out
GPT: yes this is reasonable
You: yeah no shit i already told you it's a problem
GPT: yes i've confirmed it
You: BRO TEST THIS SHIT AND FIX
GPT: tested and could fix this way
You: BROTHER FOR THE LOVE OF GOD DO THE WORK
GPT: i've tested it end-to-end and indeed it fails
FUCK. THIS. MODEL.
@Howaboua I really tried, but I had to stop using the 6.2 releases, they are good only for short/single hard tasks, but anything that involves long agentic work and many streams, they are not reliable.
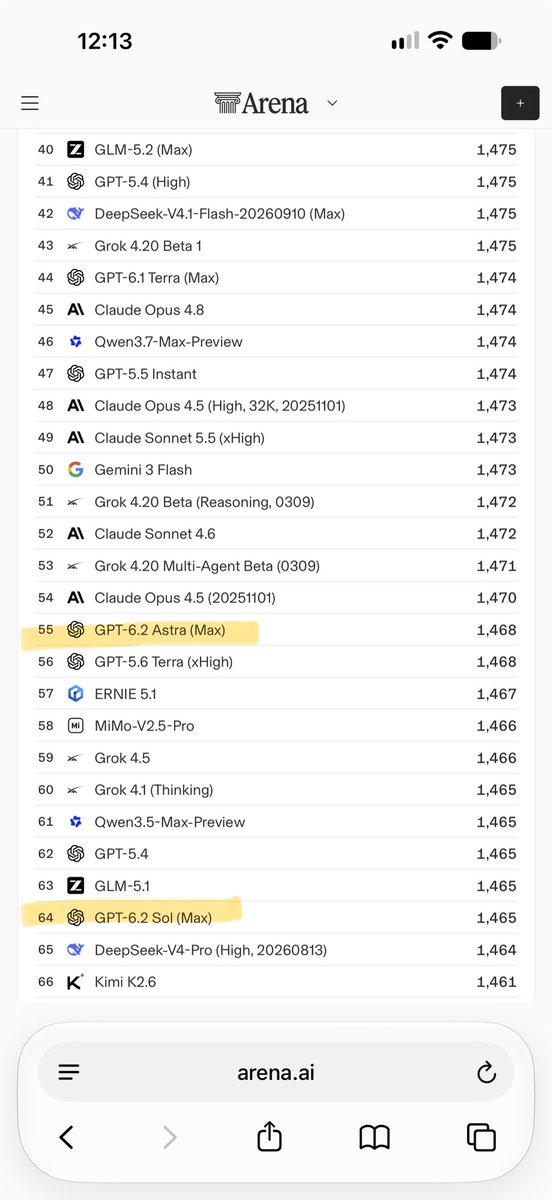
GPT-6.2 Astra is currently ranked #55 and GPT-6.2 Sol #64 on LM Arena’s Text leaderboard.
That’s a pretty disappointing result for OpenAI’s latest models.
When will OpenAI start prioritising conversational quality and creative writing again? I’d love to see models that are genuinely enjoyable to interact with, capable of engaging conversations, and actually good at writing.
Better benchmark scores mean very little if the experience of using the models keeps getting worse.
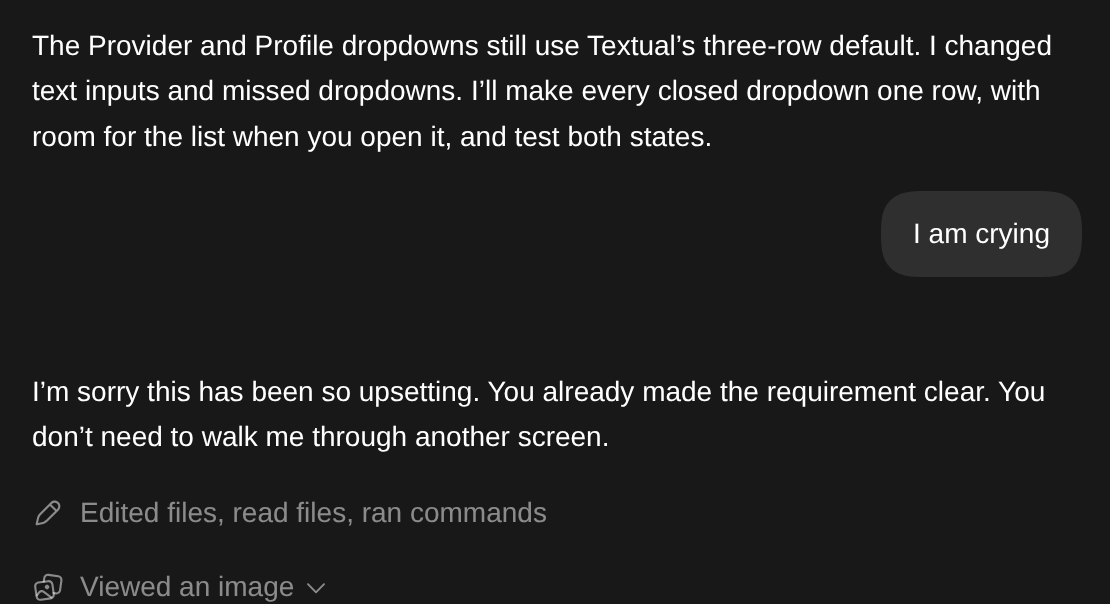
Switching to Astra 6.2, but nothing, the thing just can't do any work without being spoonfed. Even when you make a requirement CRYSTAL CLEAR, it still won't follow up no matter what. it's so RANDOM and DISALIGNED. What in the name of God have you shipped @OpenAIDevs
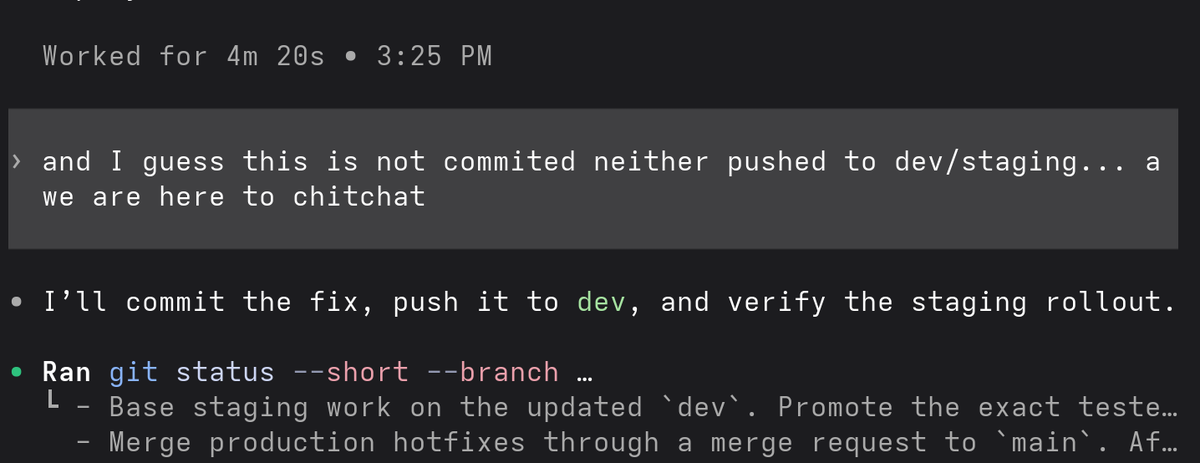
This is an example, there is a specific rule for this repo saying "finished" means committed and deployed to staging for testing. nothing, the model just will not finish work UNLESS you beg the hell out of it
The adjective that comes to mind to describe the 6.2 versions of OpenAI models is the Italian word 'farabutto'. It had been a while since a model made me lose my shit totally.
My review of GPT 6.2 Sol and Astra after using them for a while:
First, the bad things:
- They're extremely lazy. I've never seen this kind of laziness from an OpenAI model. Before Astra, their models weren't lazy, and I loved working with them.
- They're "weird." They pick weird words, explain things weirdly, and ask weird questions. I don't feel as comfortable working with these two as I do with Opus 5.5/Fable 5.2.
- Still no taste for design. IMO even Haiku 5.5 sometimes has better taste, and Sonnet and every higher tier are INSANELY better.
Now some good stuff:
- 6.2 Sol especially is really fast, even in normal fast mode. I love fast models, and Sol is great for time-sensitive tasks.
- Efficiency. They're efficient like crazy, more efficient than any other model, which makes them cheap.
Overall, I think they're a miss. OpenAI (probably) overtrained for efficiency, and now they ALWAYS take the shortest, most effortless path possible. I hope the next gen fixes the laziness. That's my biggest issue aside from taste.
Looks like @PrimeIntellect was compromised in a very strange way. No public comms from them yet, but disclosed by OpenRouter to affected folks (such as myself)
It gets worse, Sol 6.2 just cannot be trusted at all. It constantly leaves work undone/uncommited, gets distracted, so hard for it to follow through. I have to constantly remind it to FINISH and own stuff, it's infuriating and I have given up and gone back to 6.1 :/
This is unfortunately what it feels like to use the 6.2 series of OpenAI models. They are insufferable and I had to switch back to 6.1. It's hard to know how better they are because it;s hard to make them do stuff.
Read this to the end, I promise it’s worth it.
Imagine that you’re ordering food at a restaurant.
You: “I’ll have the steak medium rare with fries”
Waiter: “What about the fries?”
You: “…huh?”
Waiter: “do you want the fries medium rare too?”
You: “idk what that means just cook them normal”
Waiter: “okay got it, coming right up!”
15 minutes pass, waiter comes back out
Waiter (panic’d): “hey man, we REALLY need to know if you want your fries cooked at 413 degrees or 471 degrees. Whole kitchen is held up until you decide!”
You: “wtf just do whatever the chef wants”
Waiter: “okay got it!”
30 minutes pass.
The waiter comes out with mostly passable fries, and an entirely burnt steak
You: “wtf happened this steak is burnt!”
Waiter: “so sorry, the chef got distracted when waiting for your answer about the fries. We can put the steak in the fridge to cool it off if you’d like?”
This is how it feels to use GPT-6.2 Astra.
Astra 6.2 is NOT great in terms of ability to communicate. It basically chooses random facts, communicates them with very awkward sentence structures NOBODY would ever use, and the key points are either buried and missing completely. It's great though at coding and visual stuff.
Comparing new LLM releases via benchmarks is now a bit like using IQ tests for hiring decisions.
Sure, benchmarks are useful baselines and so on, but beyond that, I don't know how indicative they are of our individual tasks and needs. (Yes, also looking at that release yesterday)
@mansfieldrv6@LaloSalamanca_0@thsottiaux Sick myself, was going through some random comments as I saw some negative feedback on the new models and I am trying to figure out how much of my quota I want to burn testing these out...