Every time I hit a wall with one model, I used to paste my whole thread into another one and explain the project from scratch. That part wasted more time than the actual work.
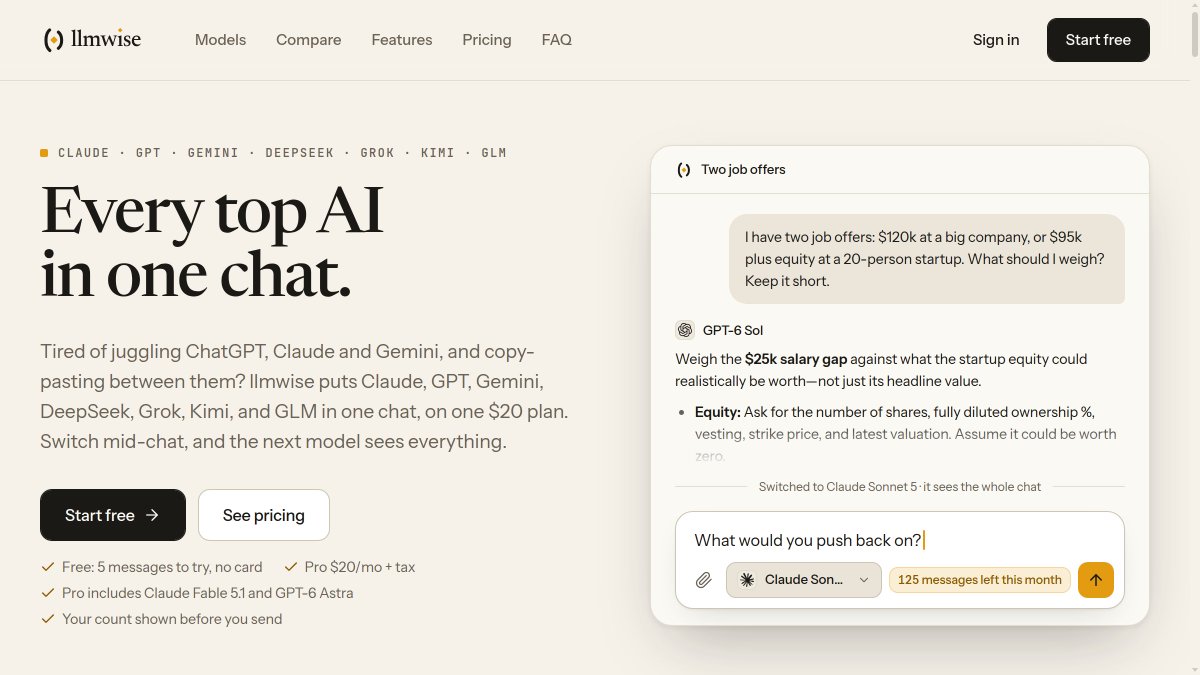
https://t.co/rxOBlxpgw8 puts 16 models from 7 companies in one chat, on one plan. Switch models mid-chat and the next model sees the whole conversation. No re-explaining your project.
I pick a model per message, and the message count shows before I send. My usual move: start on a fast model for the boring first pass, then switch to a stronger one for the hard part, same thread.
Pro is $20 a month plus tax. The monthly allowance is mixable, up to 125 messages on Claude Sonnet 5-class models, plus 60 fast messages a day.
Helps anyone juggling more than one AI subscription.
@jpshrodinger@thsottiaux i had a tool sit unused for months until it got listed somewhere people already were. that listing did more for it than any update i shipped.
Performance work fails before you touch code. The request is usually that the app is slow, with no baseline, no target, and no way to prove a fix helped. These prompts fix that.
1. "Here is my page load trace and my current numbers. List the top three things slowing this down, in order, and tell me which one to fix first and why."
2. "Write a baseline report for this endpoint: p50, p95, p99 latency, throughput, and error rate. Give me the exact command to collect each number."
3. "Review this query plan. Tell me where the time goes, what index or rewrite would change it, and what you still need from me to be sure."
4. "Turn this slow function into a benchmark I can run before and after. Include warmup, iteration count, and how to report the difference honestly."
5. "This change was faster on my laptop and not in production. List the differences between the two environments that could explain it, and how to test each one."
6. "Write a short summary of this fix for my team: what was slow, what changed, the before and after numbers, and what we still do not know."
Speed work is mostly measurement work. Make the model ask for your numbers before it hands you answers.
@AndrewPrifer i've paid for a few of these tiers and still end up on the cheapest one most days. once the feature lists overlap i just pick one and stop reading.
GPT-6.1 Sol is live on llmwise 🚀
OpenAI's new model from DevDay, in one chat with Claude, Gemini, Grok, Seedream and more.
Free Pro for a month: sign up at https://t.co/rxOBlxpgw8, comment here, then DM us or email [email protected]
Send us feedback and we'll make it one months free.
How to claim:
1. Sign up at https://t.co/rxOBlxpgw8 (just your email, no card)
2. Comment on this post
3. DM us or email [email protected] with the email you signed up with
We switch Pro on within a day. It ends by itself after the month, and nothing is charged.
Quick connect post: I build AI agents for small teams.
Most of my week is Kubernetes, AWS and Terraform, plus arXiv papers on chain-of-thought faithfulness. When I look at who is doing the interesting work, it is often one person alone in a repo at midnight.
If that is you, you are not as alone as it feels.
Reply with what you're building. I follow back builders.
@quietforgelab@HristovBuilds i do this too, switch models mid project then forget which one broke what. sticking with one until it actually fails taught me more.
Interesting paper on editing AI-generated video worlds.
Most video world models let you walk around a generated world. You can explore, but you have limited control over changing what is already there. EditWorld adds that control. It streams editing instructions and reference images while the model generates, so you can modify world content as it plays out.
Two pieces make that work. Gated Causal Attention handles editing conditions and reference images that change over time. Sparse Context keeps a bounded history so long runs stay manageable. They also train with joint autoregressive and bidirectional training plus annealed self-resampling, and built a data synthesis and annotation pipeline to get supervision for world editing. Then WBench-Editing to measure streaming world editing.
The novel bit: edits and reference images arrive mid-stream, during generation, not as a one-time prompt.
Hardest numbers: overall score 73.8 on WBench-Editing, editing score 80.0.
If you generate interactive video worlds and want to change things inside them while they run, this is built for that.