We now have state-of-the-art pre-trained base models in the 3T-parameter weight class, built entirely in-house at MAI.
Post-training results coming soon -- stay tuned!
Lots of details in our technical blog post.
https://t.co/xcZ5uV4TAp
last-night we released rnj-1.5, our long-context extension of rnj-1. the model can now reason and solve coding problems out to 160k tokens of context, up from 32k.
We @neosigmaai@RitvikKapila are building the future of self-improving AI systems! By closing the feedback loop between production data and system improvements, we help teams capture failures, convert them into structured evaluation signals, and use them to drive continuous improvements in agent behavior.
We show how our system works on Tau3 bench across retail, telecom, and airline domains. Agent performance on the validation set (with a fixed underlying model, GPT5.4) improves from 0.56 → 0.78 (~40% jump in accuracy).
Surprisingly! Current TTA models fail to distinguish between "generate a sound for a train 10 meters away" vs "a train 500 meters away"
Presenting our ICLR 2026 work - Aurelius, a synthetic data generation pipeline to enhance relation-aware TTA generation. 🚀
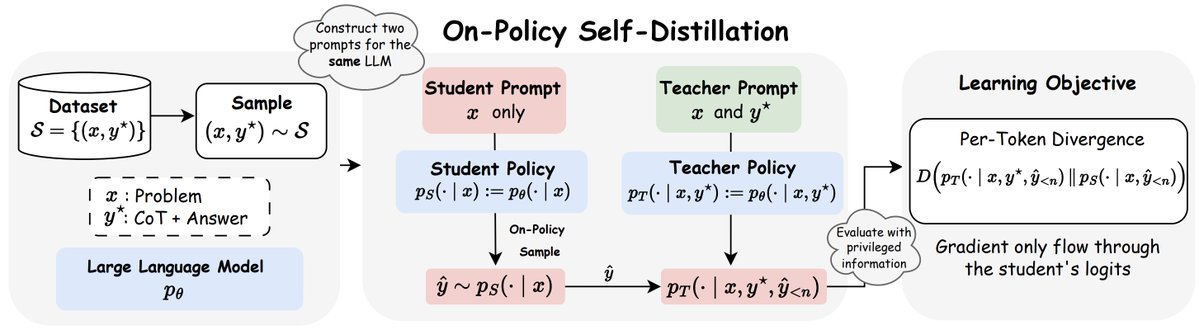
Introducing 💡On-Policy Self-Distillation💡, a simple method that enables LLM to teach itself with dense per-token feedback on its own on-policy generations—achieving 4-8x more token efficiency vs. GRPO and outperforming both GRPO and SFT/Off-Policy Distillation.
Key insight: like a student reviewing solutions, rationalizing them, and correcting prior mistakes, an LLM can be conditioned on privileged info (e.g., correct solution or a reasoning trace) and supervise its weaker self—the version without such access—by matching the privileged-info-induced distribution from itself.
🌐Blog: https://t.co/u2G20GjI6d
🧵👇
"An hour of planning can save you 10 hours of doing."
✨📝 Planned Diffusion 📝 ✨ makes a plan before parallel dLLM generation.
Planned Diffusion runs 1.2-1.8× faster than autoregressive and an order of magnitude faster than diffusion, while staying within 0.9–5% AR quality.
[1/5]
We thank the community for their feedback on Rnj-1. We’d like to announce a few updates to Rnj-1-instruct based on what we heard:
- Resolving premature truncation of generations and improved instruction following.
- Instructions for 128k context length extrapolation.
- Updated evals, baselines, and model generations for reproducibility.
Details follow 🧵
NEW: @essential_ai just released Rnj-1, their first 8B model.
You can easily fine-tune it with GRPO using TRL to add reasoning capabilities to a compact mode
Free Colab link below
Proud to carry the spirit of Ramanujan with rnj-1: honoring the great minds who showed how curiosity reshapes the world. The lineage of deep thinking is part of our mission. Essential proud.
The OSS coding model that @ashVaswani and team at @essential_ai have been working on over the last year is now out and available to use on @togethercompute APIs and playground.
It's particularly exciting that @essential_ai is doing fundamental work in pre-training and post training and publishing open weights!
https://t.co/mTKOV49jOz
https://t.co/di9a968ZLN
📢 New Model Drop: Rnj-1 Instruct is now live on Yupp!
The first flagship model from @essential_ai, this open-source model is built to excel at math problem-solving and scientific reasoning.
We checked it out with some prompts: