Anthropic has released Claude Fable 5.2, taking the #1 spot on the Artificial Analysis Intelligence Index v5 at 65, led by gains in science, knowledge, and coding
At max effort it scores 65, 5 points ahead of Gemini 4 Carbon (high, 60) and 6 ahead of Claude Opus 5.5 (max, 59). Gains are driven by scientific reasoning, knowledge and FrontierCode 2.0, and roughly matching Opus 5.5 on AA-Briefcase and Terminal-Bench 4.0.
Priced at $8/$40 per 1M input/output tokens, a 20% reduction from Fable 5.1, Claude Fable 5.2 averages a Cost per Task of $26.5 with max effort, a ~2.6x increase compared to Opus 5.5 (max, $10.0) and ~2x compared to Fable 5.1 (max, $12.99)
Key takeaways:
➤ Claude Fable 5.2 leads 5 of the 9 evaluations in the Intelligence Index: At max effort, Fable 5.2 scores 65, ahead of Gemini 4 Carbon (high, 60), Claude Opus 5.5 (max, 59) and GPT-6 Astra (max, 57), and ~15 points above Claude Fable 5.1 (max, 49). It sets the highest scores on HLE-Diamond (80%, previous best 69% from Gemini 4 Carbon), AA-Omniscience v1.1 (67, previous best 54 from Gemini 4 Carbon), Terminal-Bench-Science (73%, previous best 65% from Gemini 4 Carbon), CritPt v2 hard subset (77%, previous best 72% from GPT-6 Astra) and FrontierCode 2.0 (49%, previous best 46% from Claude Opus 5.5)
➤ Less progress in agentic knowledge work and terminal coding: Claude Fable 5.2 improves on Fable 5.1 across capabilities, but sometimes only to Opus 5.5 levels. It reaches 1785 Elo on AA-Briefcase, within the confidence interval of Opus 5.5 (1800) and just behind Claude Sonnet 5.5 (1813). On GDP.pdf it reaches 24% all-pass against 26% for Opus 5.5. On Terminal-Bench 4.0 it scores 60%, level with Opus 5.5 and behind Kimi K3.1 Pro (67%), Gemini 4 Carbon (65%) and Sonnet 5.5 (64%). AutomationBench-AA is an exception, at 76% against 70% for Opus 5.5, narrowly behind Gemini 4 Carbon, 78%
➤ Lower efforts still take leading positions: With high and xhigh effort, Claude Fable 5.2 scores 62, ahead of every other model at any effort, using 98k output tokens per task against 173k for Opus 5.5 (max). At max effort Fable 5.2 costs ~2.6x more than Opus 5.5, but at lower effort settings it can outperform Opus 5.5 at lower cost per task
Other model details:
➤ Context window: 1 million tokens with image and text input
➤ Pricing: $8/$40 per 1M input/output tokens; cache writes $10 with 5-minute TTL, $16 with 1-hour TTL, and cache reads $0.20
➤ Effort settings: five (low, medium, high, xhigh, max). Intelligence Index evaluations were run at all five with Anthropic's default fallback enabled
Congratulations to @AnthropicAI on this impressive release!
@DavidSKrueger Re optics: I do think it could've been timed right before the IPO when the market wasn't reeling from fears of regulations. Having a quarterly audited report alongside earnings call is perhaps better for optics
@SydneyVonArx Do we have a sense of what the acceleration is attributed to? In other words, what is the net acceleration holding Data & Compute constant? Assuming those are input parameters they can control for.
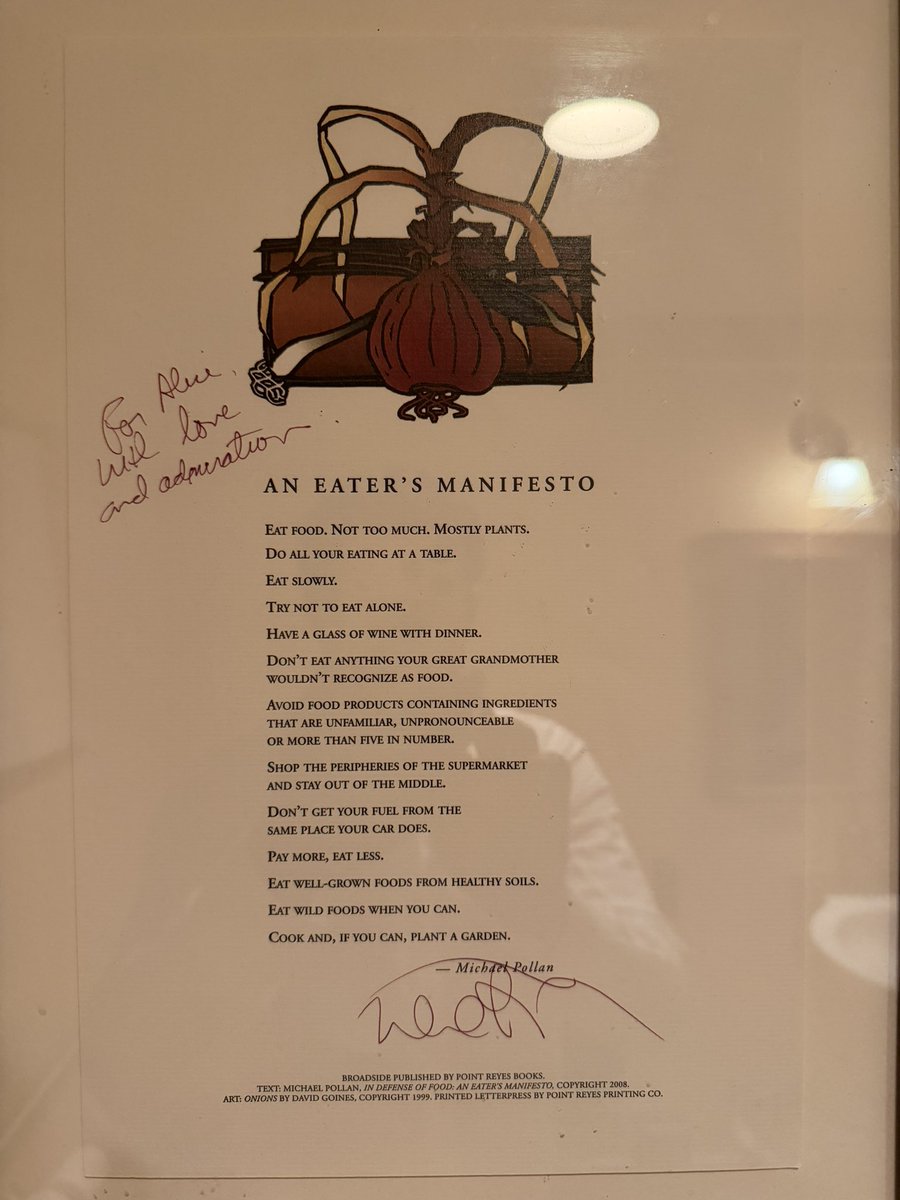
@RamaswmySridhar Found the full manifesto hanging in @chezpanisse.
"Dont eat anything your great grandmother wouldn't recognize as food"
This one hit hard as an immigrant
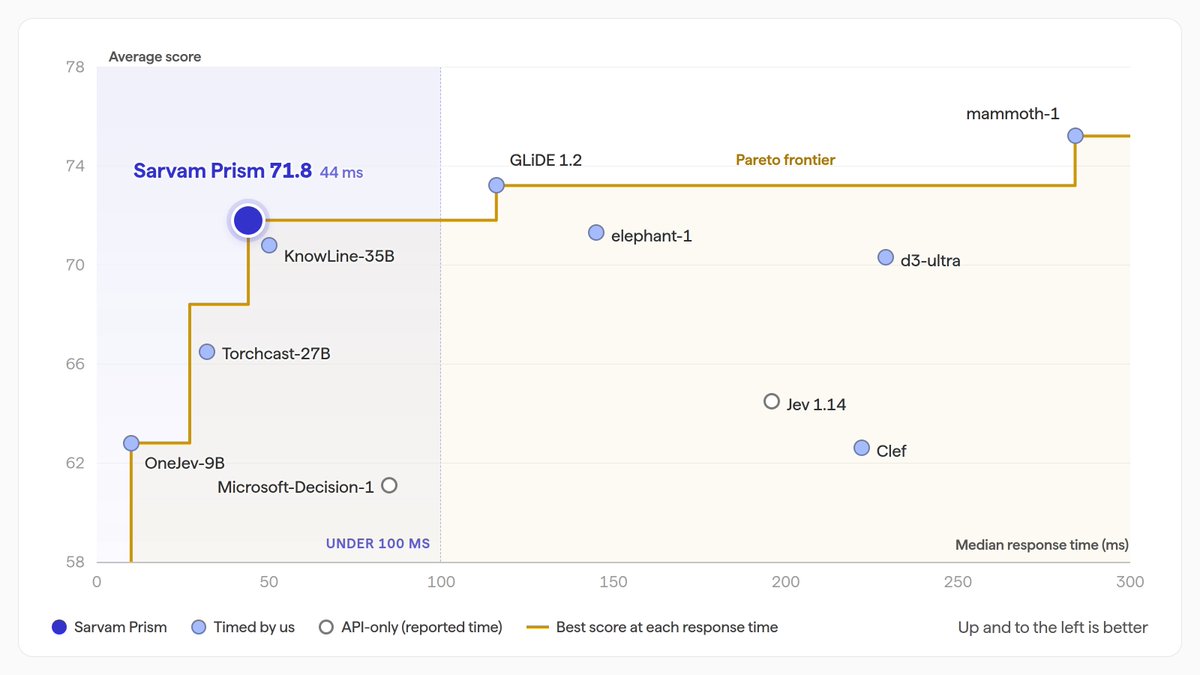
Today we’re releasing Sarvam Prism, a System One model built on Sarvam 105B for fast, accurate decisions across enterprise workflows.
It scores 71.8 with a median response time of 44 milliseconds, the highest average score among decision models that respond in under 100 milliseconds.
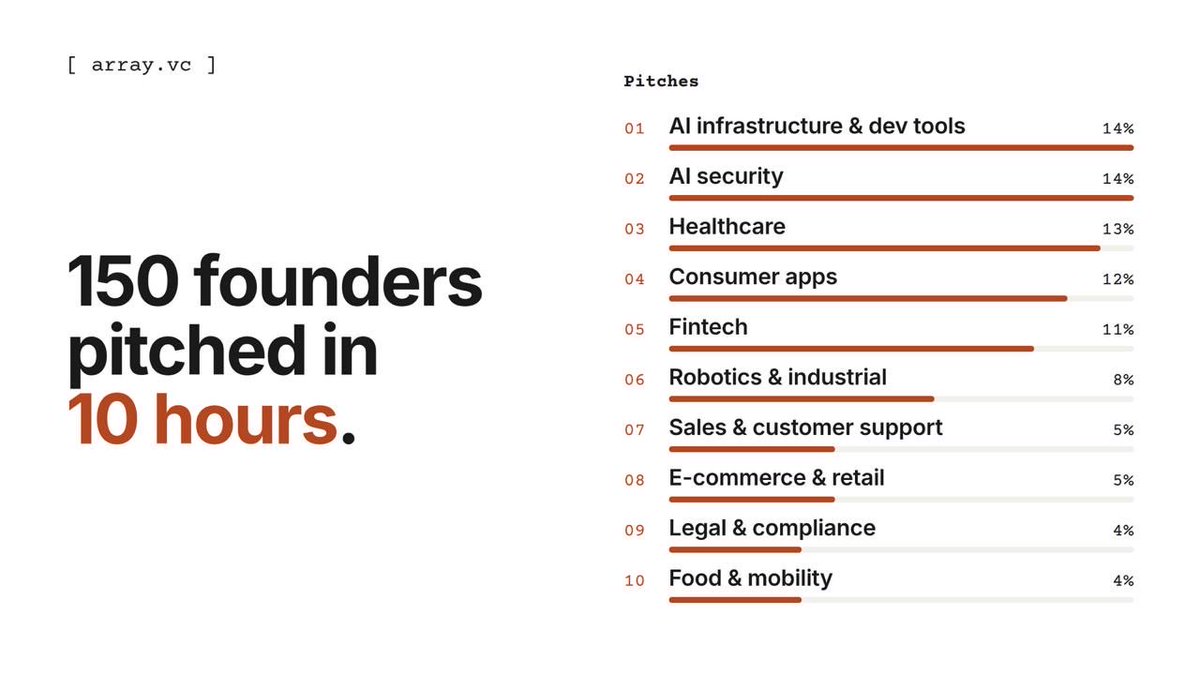
Day 1 we saw 200+ pitches here is what we are seeing so far!
Would love to see more in energy, defense, and anything else surprising! Keep it coming!! Thank you so so much!!
India saw about 496 million people lifted out of poverty between 2011 and 2023 in one of the world’s fastest declines in this metric, the World Bank said, although the gains remain uneven. https://t.co/4RD7JC4lG2