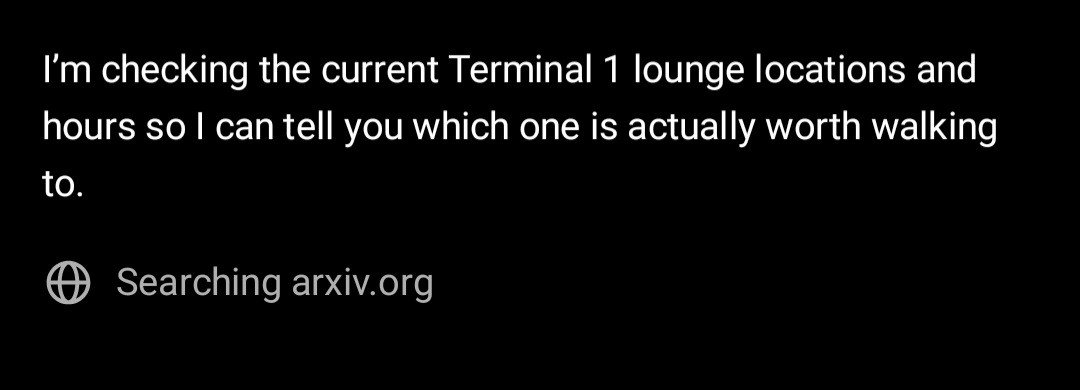
Auto research agents trying to use research conferences as a test bed.
Put in place a $1 submission fee. And see corporate policies not know how to deal with it. 😂
The incentive structure has broken, so it has to change if we want to keep these forums meaningful.
Such a pleasure talking with @ShivAroor and @ndtv.
We should have more accountable conversations about risk. If someone said a tsunami was coming tomorrow, we would ask for evidence.
10% extinction being thrown around without justification feels highly irresponsible to me.
Last week we introduced Invent a Dataset. Describe what you need. Hit go.
Today, we’re making it even easier with the Invent API.
A few lines of code. AI ready training datasets in minutes.
Most people fixate on either model or harness.
We see the entire stack as optimizable and something to adapt.
I tried to explain this to someone the other day. If you’re a chef, you want the best ingredients and the best oven. Not one or the other.
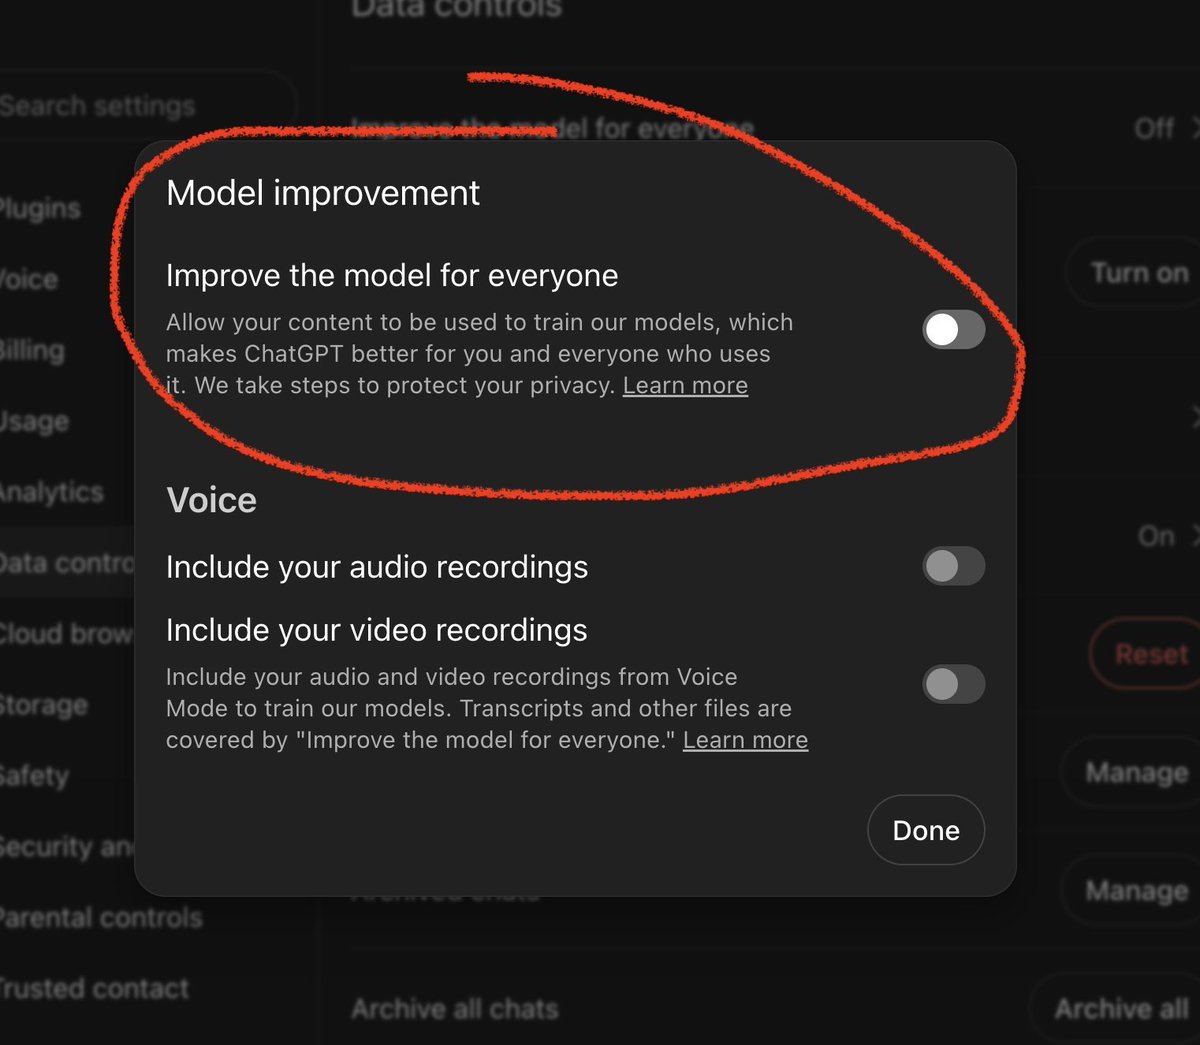
Zero data retention is not the same as zero data visibility. True ownership requires you to retain the ability to create your own intelligence on your own data without letting your competitors reach the same outcome through an intelligence intermediary.
New research from @sudip_r0y and @dhruvrnaik.
Harness optimization moved criterion pass rate from 67.10% to 85.92% on @harvey Legal Agent Benchmark. Post-training pushed it to 88.03%.
Owning your intelligence means improving the model and the harness around it.
Agent performance is often attributed primarily to the underlying model.
Our research suggests the harness recovers what a model can already do, but it can't create capability the model doesn't have.
@dhruvrnaik and I saw this with Qwen3.6-27B on the @harvey Legal Agent Benchmark. Harness optimization alone moved pass rate from 67% to 85%. Adding post-training pushed it to 88%.
Bringing AutoScientist to 15+ million @huggingface researchers and builders. 🤗
AutoScientist automates model training. Specify your objective, let AutoScientist do the rest.
Export to Hugging Face with one click.
Introducing Invent a Dataset.
Describe the dataset you need. Get a structured, training-ready dataset back. No existing data needed.
Dataset creation used to start with collection. Now it starts with specification.
Better training data. Faster training cycles. Any language, any domain.
@AISingapore used Adaption to enhance dataset quality and expand training dataset size via localization across five low-resource Southeast Asian languages.
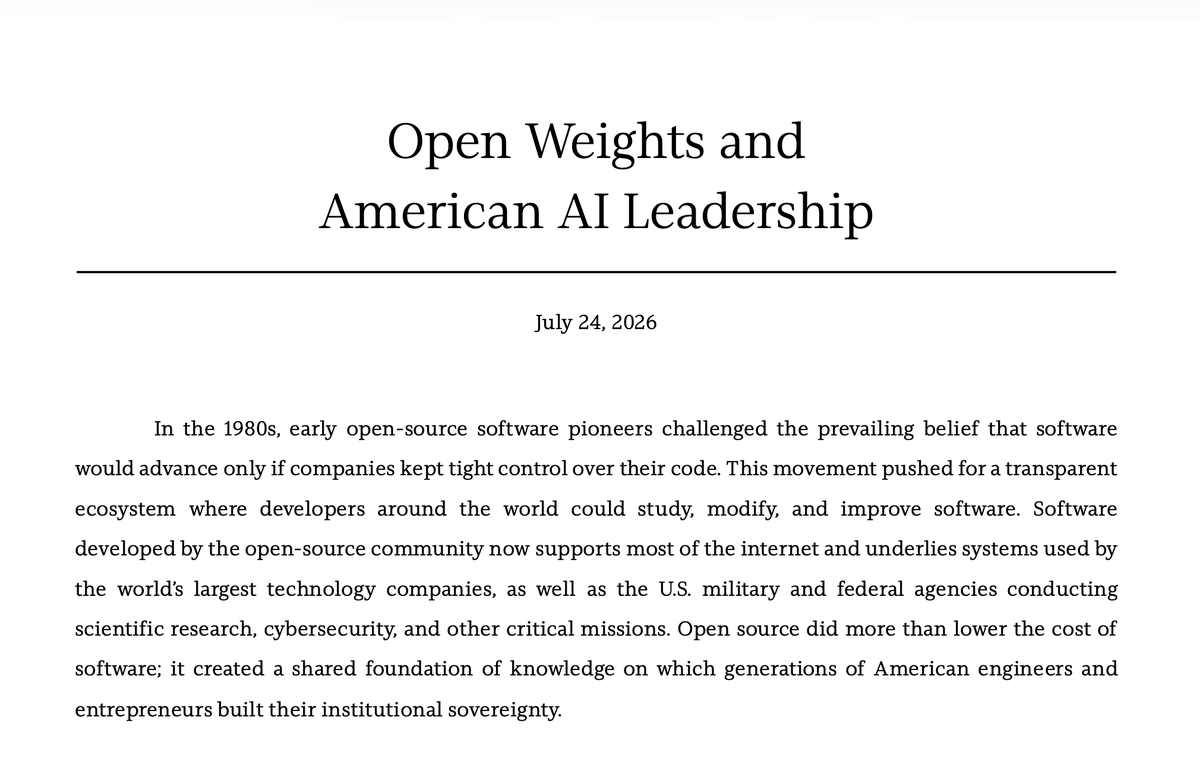
Adaption has signed the Open Weights and American AI Leadership letter.
Most of the world does not need a bigger general model. It needs models built for local languages, local data, and local infrastructure. That starts with weights you can download.