Back on X after a 5-year nap 👋 Last post I was automating robot deploys at Movai. Since then: Kubernetes on GCP, internal platforms, an LLM Slack bot for devs, and now a freelance app for restaurant ops. Based in Lisbon. Sharing what I learn as I build.
@lincolixavier Qual dos dois aparece mais nos casos que vc viu: banco aberto por falta de regra de acesso, ou o loop de tokens? O segundo quase ninguém percebe até chegar a fatura.
@AkitaOnRails Faz pensar na quantização: se a LLM já comprime perto do limite de Shannon, como cortar os pesos pra 4 bits perde tão pouco? A redundância tá nos pesos e não na informação que o modelo guarda?
@razvanmuntian Curious how you handled European vs Brazilian Portuguese: separate question sets or the same ones adapted? Brazilian living in Portugal here, and plenty of words differ just enough to be a quiz of their own.
@imxhoaib That's the real catch. Burning 100% on features nobody touches is just a fancier way of wasting it. Picking what to build is now the actual job.
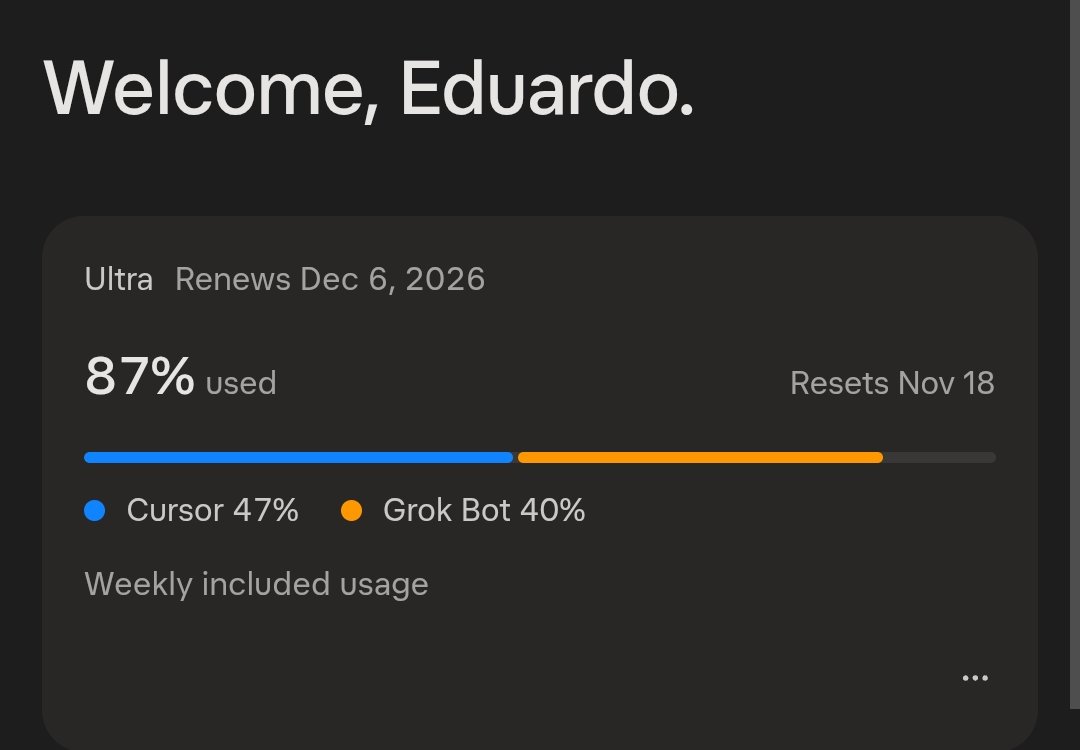
My new productivity metric isn't hours worked.
It's how close I get to 100% of my AI plan before it resets.
This week: 87%, with Cursor and Grok Bot doing the building while I set priorities.
Every unused % is a feature that didn't get built.
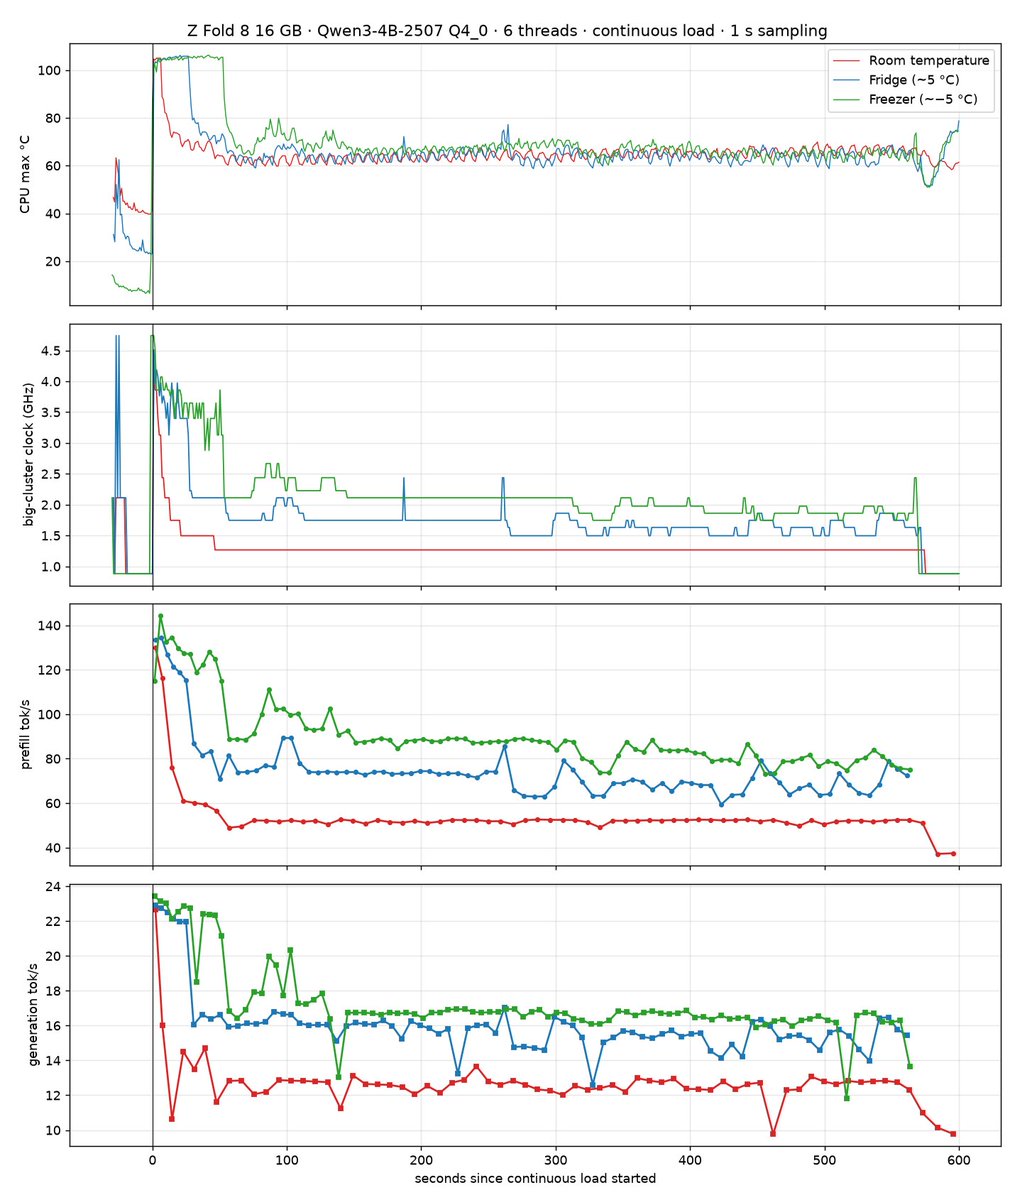
@VisiveAI Depends a lot on prompt length. Prefill runs ~5–6x faster than generation here (~130 vs ~23 tok/s at start), so for a short chat prompt generation is most of the wait. With long context or RAG it flips fast, especially once throttling drags prefill down to ~52 tok/s.
@RaphaelAubryy That's useful, thanks for checking. So for now the Google profile is still doing the real work for restaurants. If the restaurant category ever shows more fields, I'd love to know what they ask for.
@plavecmario3 Logged both every second, phone on the charger the whole time. All three runs settled at ~63–65 °C CPU, and Android traded clock for it: ~1.25 / ~1.7 / ~2.0 GHz (room/fridge/freezer). Cold buys clock, not a lower temp. Odd 0.9 GHz drop near min 10 I'm still checking.
@eddiejaoude Curious whether the 4 were devs who spotted the Google logo, or did the jacket just start conversations with anyone? Porto in the rain is a solid filter, only the committed are out walking.
@USASmarTekAI Thanks! And that's why I think every phone maker should publish the temperature their performance tests ran at. Without it, a benchmark is a best case, not something you can reproduce. Heat is always the hidden variable.
I put two Galaxy Z Fold 8s in the fridge to run local AI. 🧊📱
Setup: 16 GB vs 12 GB RAM, llama.cpp in Termux, CPU only, Qwen3 4B, 8B and 14B.
What I learned 🧵
Short version: it throttles first, RAM is what ends the run.
My take: phones aren't ready for serious local AI yet. Keeping them cool doesn't fit in a pocket.
Great playground for devs today. Daily driver, not yet.
Would you run an LLM on your phone? 👇 #LocalAI
🐢 Long context is slow. 16k tokens on the 8B took ~28 min before the first token.
The good surprise: when facts fell out of context, the model answered "not found" instead of making things up.