@simas_ch Yes, I do this as well, and this can be very fast indeed.
- configure postgres to start up fast
- create a single template database that has all db migrations applied
- every integration test copies template db
Some previous comments on HN:
https://t.co/YWctQRUP2v
PGVECTOR IS NOW FASTER THAN PINECONE. And 75% cheaper thanks to a new open-source extension – introducing pgvectorscale.
🐘 What is pgvectorscale?
Pgvectorscale is an open-source PostgreSQL extension that builds on pgvector, enabling greater performance and scalability (keep reading for the actual numbers).
By using pgvector and pgvectorscale, developers can build more scalable AI applications, benefiting from higher-performance embedding search and cost-efficient storage.
📈 How does it perform?
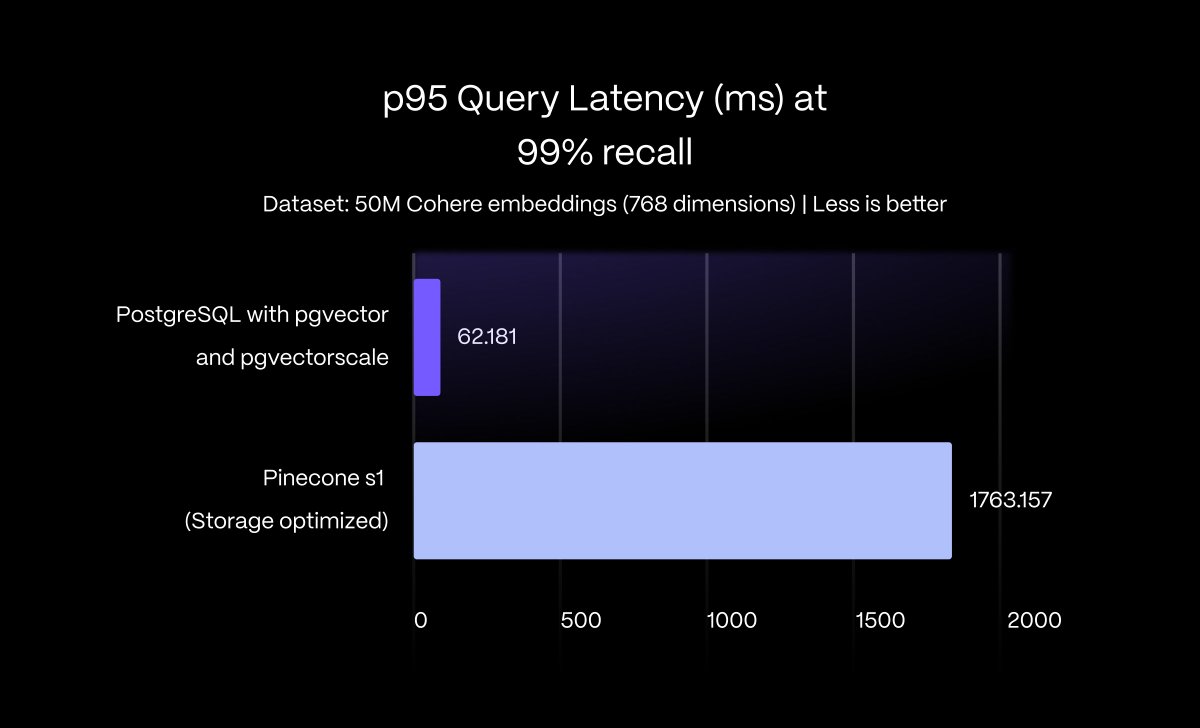
On our benchmark of 50 million Cohere embeddings (768 dimensions each), PostgreSQL with pgvector and pgvectorscale achieves 28x lower p95 latency and 16x higher query throughput compared to Pinecone for approximate nearest neighbor queries at 99 % recall, all at 75 % less cost when self-hosted on AWS EC2.
We also tested it against Pinecone’s p2 high performance index, see the blog post at the end of this post for full results (spoiler: It’s just as impressive).
🤔 Why did we build pgvectorscale?
Our team at @timescaledb built pgvectorscale to make PostgreSQL a better database for AI and to challenge the notion that PostgreSQL and pgvector are not performant for vector workloads.
⚙️How does it achieve such good performance?
Pgvectorscale brings specialized data-structures and algorithms for large-scale vector search and storage to PostgreSQL as an extension, including: (1) StreamingDiskANN – a high-performance, cost-efficient vector search index for pgvector data inspired by research at Microsoft, and (2) Statistical Binary Quantization (SBQ), developed by Timescale’s own researchers to improve upon standard binary quantization techniques.
These innovations help PostgreSQL deliver comparable and often superior performance than specialized vector databases like Pinecone. 👏 Big shoutout to @cevianNY and @sql_johnpruitt, two senior staff engineers at Timescale, who worked on these technical breakthroughs.
🧑💻 Sounds exciting! How can I get started?
Pgvectorscale is open-source under the PostgreSQL license, and free to use on any PostgreSQL database. You can find installation instructions on the pgvectorscale GitHub repository (see end of post). It’s also available on any database service in Timescale’s PostgreSQL cloud platform.
📚Learn more
[1] Pgvectorscale explainer blog: https://t.co/kG7Y48hxjy
[2] Pgvectorscale github repo: https://t.co/xcpA65dWOQ
Share this post with your followers to let them know about pgvectorscale and comment your reactions and questions.
I just completed "If You Give A Seed A Fertilizer" - Day 5 - Advent of Code 2023 https://t.co/b1FVVVBLd8 #AdventOfCode using #postgresql#sql
https://t.co/UfBRBnsflD
Advent of Code has started! Again I'll try to keep doing all challenges in #sql (I'm using #postgresql)
I just completed "Trebuchet?!" - Day 1 - Advent of Code 2023 https://t.co/NyVxDAT5AR #AdventOfCode
Today's solution using a single sql statement:
https://t.co/f9XxIsVTt0
📣 Hey there 👋
The Belgium #PostgreSQL User Group will meet next week (on Tuesday 28 November) in Antwerpen to discuss about Postgres Architectures and I will also talk about "What can't @pgBackRest do for you" !
Link to the event : https://t.co/bBnDXxoYcT
Come join us ! 🐘
1/ 🤖 You don’t need a specialized vector database. You just need PostgreSQL.
Introducing Timescale Vector: PostgreSQL++ for AI Applications
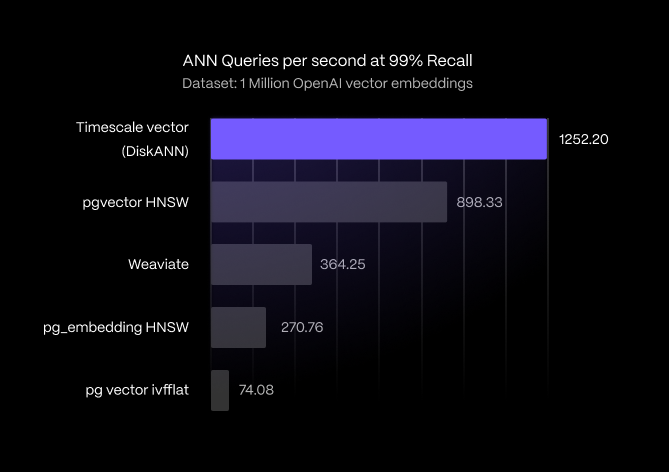
- 📈 3x ANN search performance vs Weaviate, 40%-1,500% boost for pgvector.
- ⚙️ No need to learn and manage a separate vector database.
👋 Calling all #PostgreSQL users – the 2023 State of PostgreSQL survey is now open! 🎉
Share your feedback, favorite extensions, community experiences, and more 👇
https://t.co/CdsCP9mWdu
The survey is open until Aug 31 @ 11:59 p.m. PT ✨
Our next #PostgreSQL meetup will be in only two more days!
Where: @picnic HQ, Van Marwijk Kooystraat 15, Amsterdam: https://t.co/0euiCZAraj
When: 17:30 - 20:30 (Talks start at 18:30)
We have 2 main talks and multiple lightning talks lined up.