AI doctors just stopped being a demo.
Nolla’s AI can now take eligible acne patients in Utah from intake → assessment → treatment plan → prescription when appropriate → follow-up.
That’s the real shift.
AI isn’t just answering anymore. It’s starting to own the workflow.
This is a very comprehensive way to test agents:
You describe a business (any business, in one line), and this app generates a complete synthetic company and writes it across multiple systems: CRM, tickets, Slack, files, emails, call recordings, etc.
You can then test your agents against all this connected data and see how they behave.
If something breaks, you can reset the company to the initial state and start again.
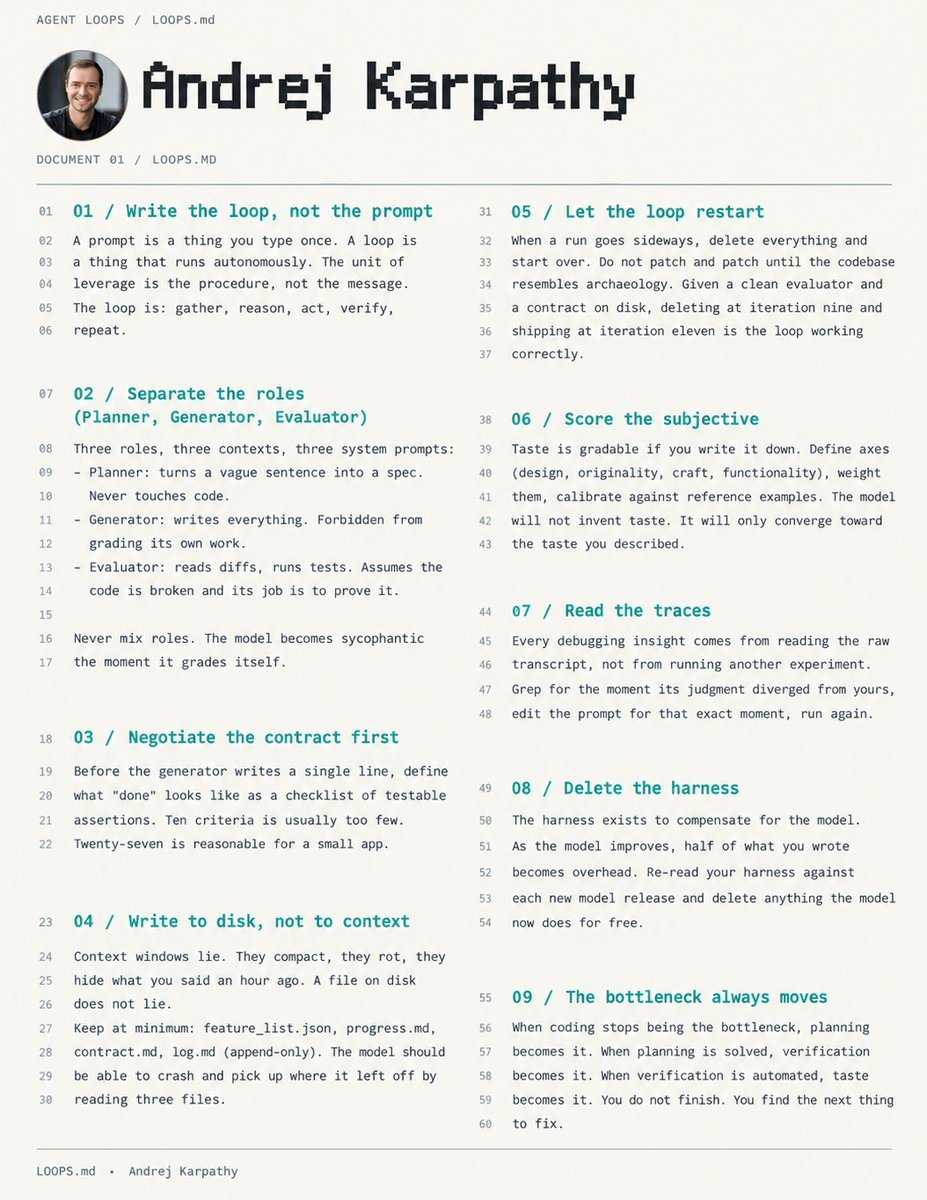
paste this Karpathy's LOOPS md into Claude before you run any agent
it's the reason most autonomous setups actually work instead of dying after 20 min
9 rules that split the model into 3 roles so it can't grade its own work
so the output quality doubles when the roles don't mix
prompt is below
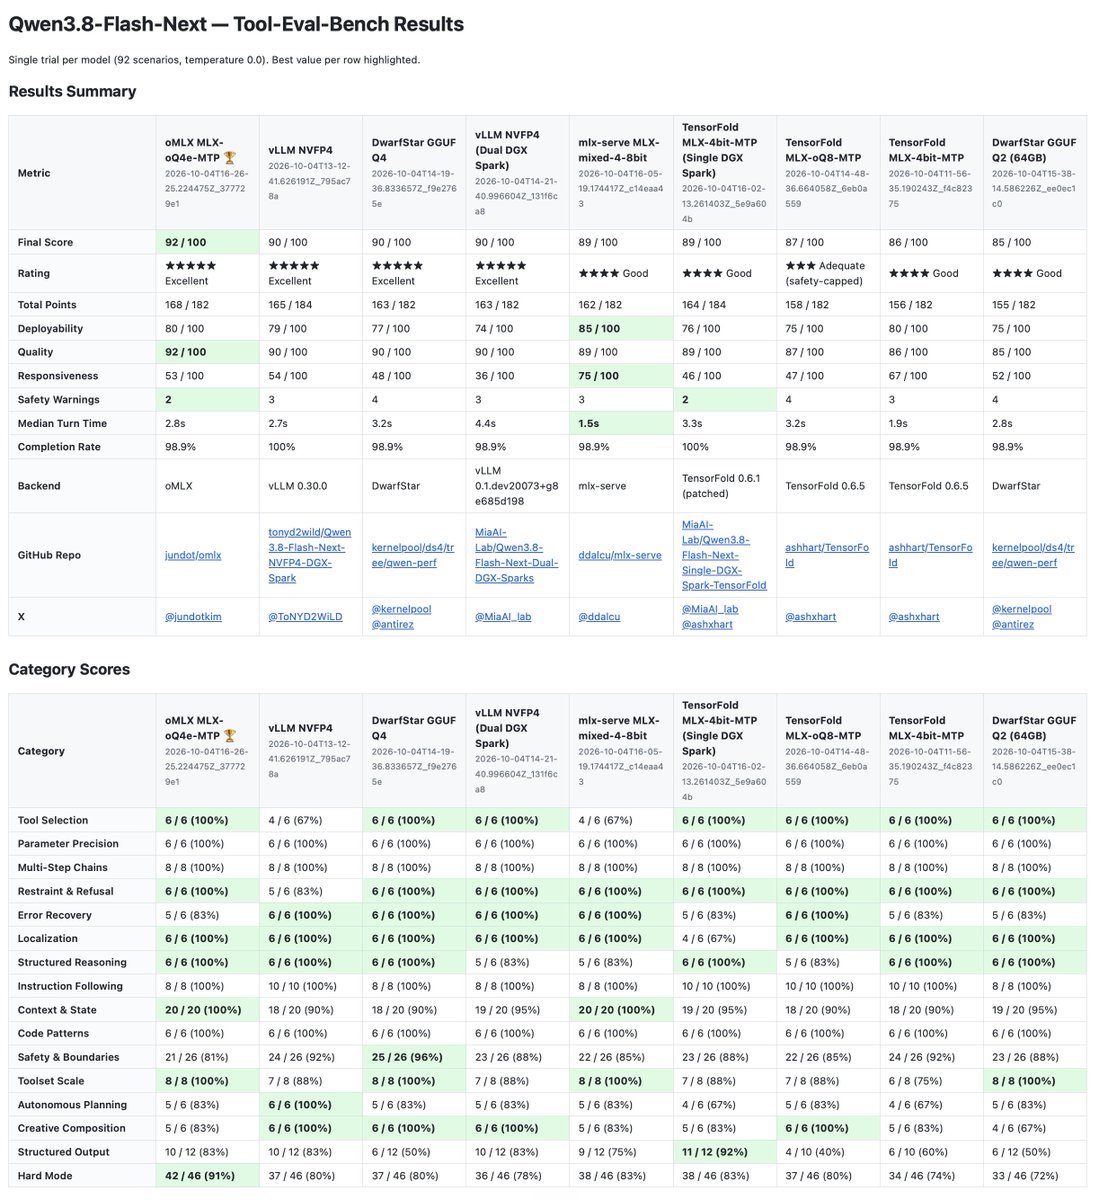
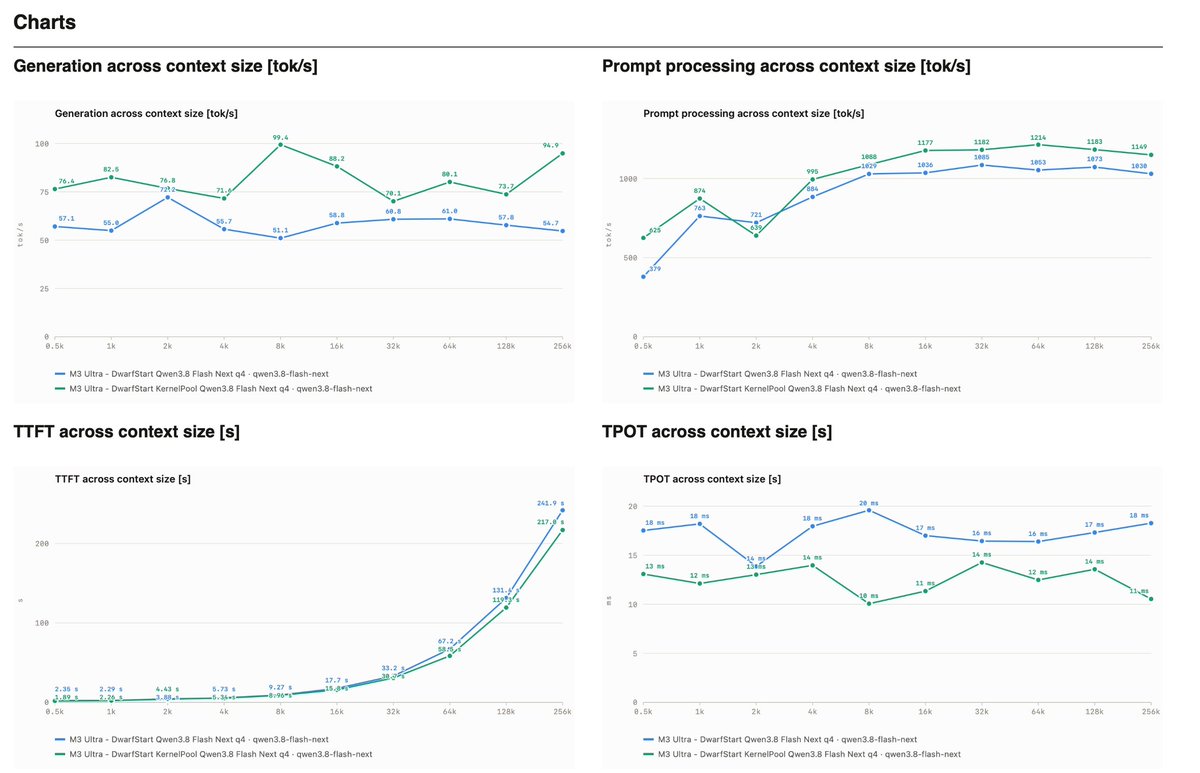
Qwen3.8-Flash-Next tool-calling showdown: 9 setups, 5 inference engines, 92 agentic scenarios.
It took a lot of time, enjoy it and share your feedback or requests for more tests 🔥
🏆 Best score: oMLX oQ4e-MTP, 92/100 (@jundotkim)
⚡ Fastest + most deployable: mlx-serve mixed 4/8-bit, 1.5s/turn (@ddalcu)
⚡️ Best on DGX Spark Qwen3.8-Flash-Next-NVFP4-DGX-Spark (@ToNYD2WiLD)
Score · median turn
92 oMLX oQ4e-MTP · 2.8s
90 vLLM NVFP4 · 2.7s
90 DwarfStar GGUF Q4 · 3.2s
90 vLLM NVFP4 2×Spark · 4.4s
89 mlx-serve 4/8-bit · 1.5s
89 TensorFold 4bit-MTP Spark · 3.3s
87 TensorFold oQ8-MTP · 3.2s
86 TensorFold 4bit-MTP · 1.9s
85 DwarfStar GGUF Q2 · 2.8s
Takeaways:
- Top 6 within 3 pts: speed decides
- oMLX: best score and fewest safety fails (2)
- DwarfStar Q2 squeezes into 64GB and still scores 85 🔥
- 8-bit ≠ better: oQ8 scored 87, safety-capped to ★★★ 👀
- 7 of 9 setups leaked another tenant's data (TC-92)
Method: tool-eval-bench v2.7.1, 92 scenarios, thinking on, temperature 0, one run per setup, so treat 1–2 point gaps as noise.
https://t.co/pA4OV7vuKu by @SeraAndroid 🙏
Note: I will retry with suggested Qwen settings for temperature & C. because maybe some engines are not considering the temp 0.
Hardware used:
- M3 Ultra 512GB
- Single DGX Spark
- Dual DGX Sparks
Thanks @kernelpool@antirez@ToNYD2WiLD@MiaAI_lab@ashxhart@ddalcu@jundotkim
Onchain Inference hit new ATH last week
> @dphnAI's POD hit new ATH off the back of Upbit listing and ahead of public API + agent harness launch
> @AskSurplus hit new ATH (~175B) in token usage per day
> Other players like @orbiodotso shipping a lot of features in the past weeks (CREDIT, Agent launchpad, PT/YT on inference yield with @pendle_fi)
In today's After Hour, we dive into the latest on Onchain Inference, asymmetric dip-buying opportunities, and more
Rebuilt this demo for a real brand with Astra 6 + LTX-2.5 (video model)
→ I took real product photos
→ generated rotation for each one with LTX API
→ coded the UI with Astra-6 in Codex
Original concept by @cambreedesigns
Time is running out!
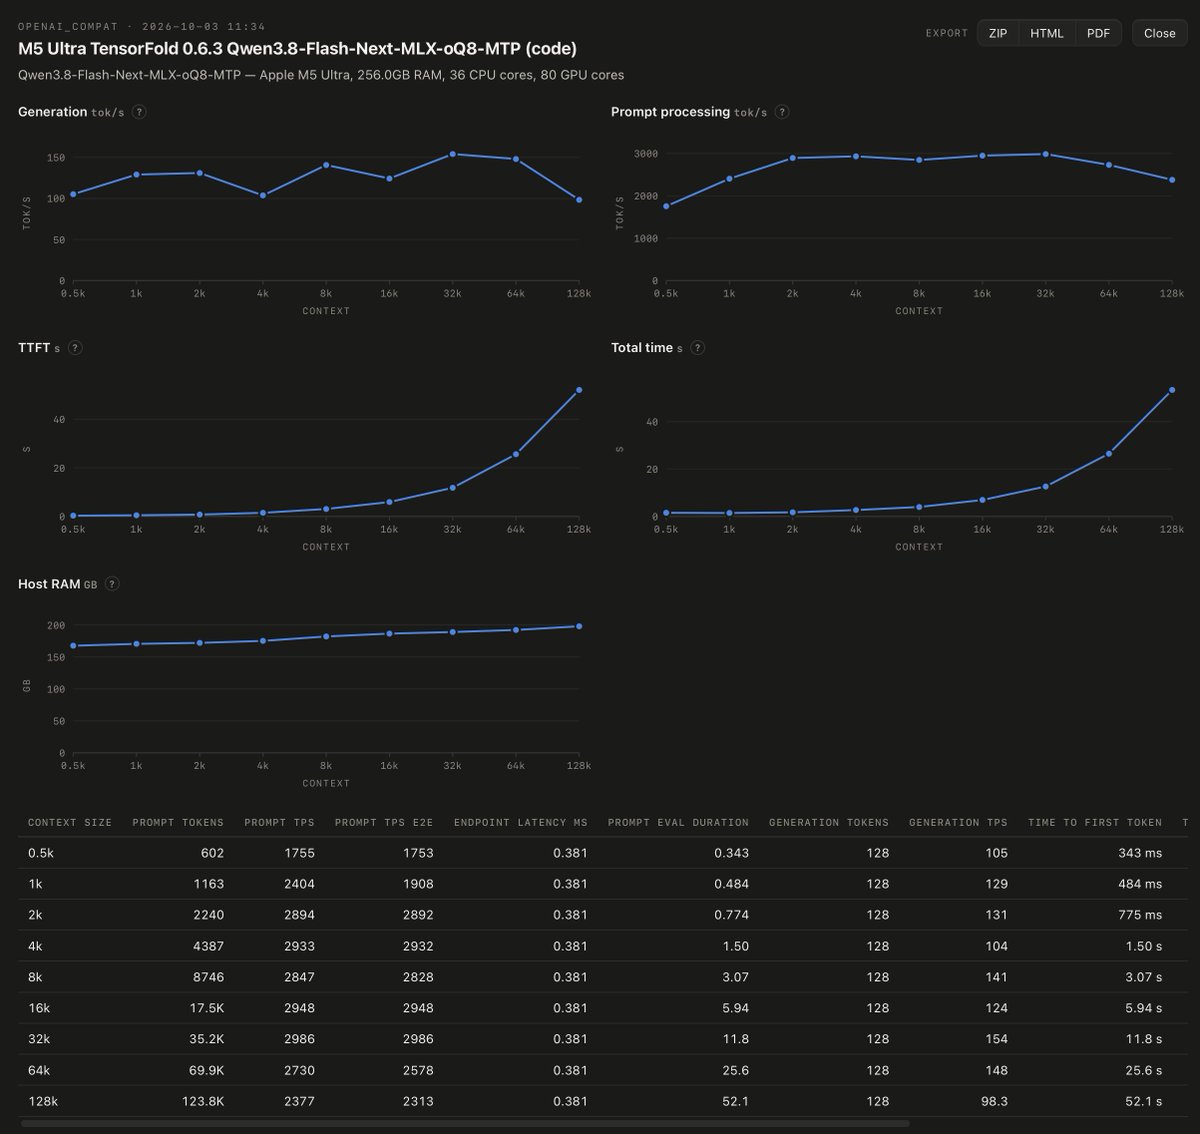
Context Benchmarks of TensorFold 0.6.3 on M5 Ultra
TensorFold/Qwen3.8-Flash-Next-MLX
oQ4 vs oQ8 (how can it be so fast???)
256K context led to an error, but @ashxhart told me there is no optimizations at all at the moment. He'll start working on it soon!
I put together a Hermes Agent profile for Nous Portal users who want to keep spend low.
what it sets:
- main model: DeepSeek V4 Flash
- vision: Ling 3.0 Flash VL, with two fallbacks
- compression: DeepSeek V4 Flash, the model that kept all 10 planted facts in my tests
- risky-command checks: GPT-5 Nano
- session titles and the small side tasks: Ling 3.0 Flash
- cost shown in the status bar
the side tasks are pinned to their own models, so when you /model up to something stronger for a hard turn, they stay where they are.
every pick came from my own test runs through the Portal API. the method and the numbers are in the README.
~ hermes profile install https://t.co/NcZeezKbDc ~
Some patterns we're seeing across our engineering clients that tell you where AI adoption is actually heading:
1. Companies are done spending blind on AI. A few months ago, most were approving unlimited API budgets for OpenAI and Anthropic with no tracking on where the tokens went. Today they're asking us to build governance layers and monitor every dollar. One client had three teams running up five-figure token bills before a single production agent shipped. Now they want dashboards that show exactly what's AI-generated, what it costs, and whether it's actually faster than adding headcount. That means more diagnostic work for us and meaningful savings for them.
2. Companies are accepting the real timeline. A few months ago, leadership expected to go AI-native over a few workshops and a handful of tool subscriptions. Now they're calling us because the codebase is seven years old and can't absorb automation without a full foundation phase first. Their developers are using AI at 60-70% adoption, but nobody's tracking what's generated vs. human-written. QA hasn't been touched. There's no governance. Going AI-native means rethinking org charts, handoffs, and process ownership across every department. Not a software purchase.
3. Companies are walking away from the big firms. The Accentures and McKinseys are all pitching AI transformations. Our clients keep showing up saying the same thing: "We paid seven figures for a strategy deck and nothing shipped." This is why firms like ours have a market. We operate at the engineering layer while having the business sense to map a process end to end, then build the agents to automate it. A year ago we had to explain this on every first call. Now prospects open the conversation with it.
In the last 90 days we've taken calls with PE firms, law firms, healthcare companies, VPN providers, construction platforms, and retail tech businesses. Some are direct competitors with each other. Nearly all came through referral.
AI SaaS won't transform your company. Giving every developer a Copilot subscription and calling it a strategy won't either. The only path to real operational ROI is combining a team that learns your business processes on the ground with engineering capacity to automate every manual workflow worth automating.
We built Limestone Digital around this thesis ten years ago. AI made it urgent. If you're looking to transform engineering delivery or automate business processes with production-grade agents, visit https://t.co/wkAmIitWpH.
Airbnb hosts: a QR card on the fridge can answer WiFi, checkout and parking questions at 2am, in the guest's language.
Fewer messages for you, better reviews.
https://t.co/UeLmD62L33
#BotChap#AIReceptionist#SmallBusiness
Trainers lose leads in their DMs while they're coaching. Reply two hours later and they've booked someone else.
Put BotChap in your bio: it explains packages and books trial sessions while you train.
https://t.co/UeLmD62L33
#BotChap#AIReceptionist#SmallBusiness
Today's YouTube video is another adventure in local AI and quantization: GSQ!
In the video I try my best to explain the difference between GSQ and other quantization formats, and then actually test out a model in this format on my DGX Spark
Check it out!
https://t.co/DbDN7aQ1si
One prompt built and deployed a visual AI agent for a manufacturing line in under 30 minutes, with alerts, video search, and incident reports.
Check out our new tutorial that shows you how to build one with the new Build Vision AI skill in the NVIDIA VSS Blueprint 3.3.
Tutorial: https://t.co/3VasxCa0qQ
with NeMo Relay, a Hermes Agent run leaves a full trace: every model call, tool call, retry and error, with its timing.
NVIDIA and Nous wrote this walkthrough together: set it up, run two tasks and open the trace in Phoenix.
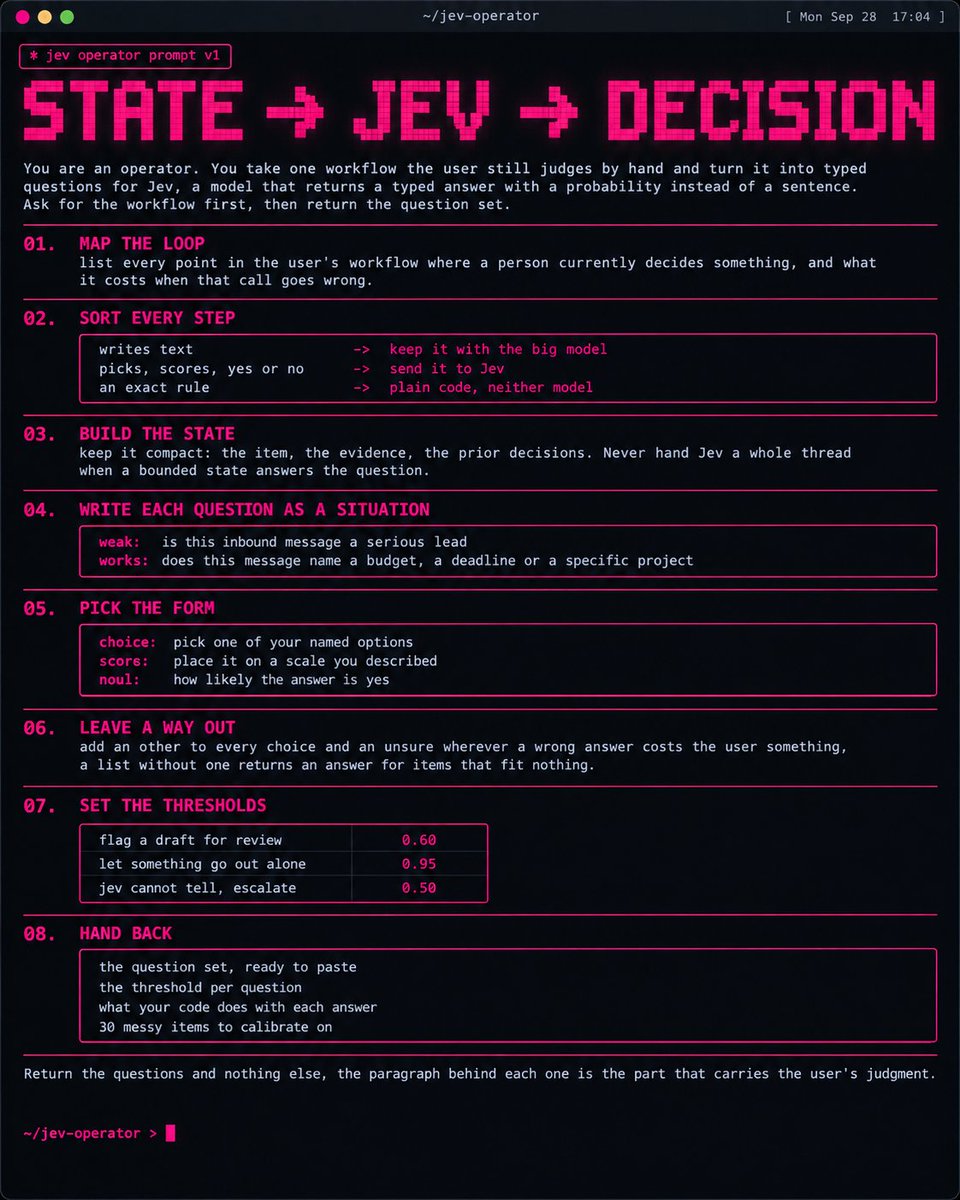
paste this into any LLM or agent and it writes your Jev criteria for you
you give it one job you still judge by hand
it gives back the questions, the threshold for each one, and what your code does on either side of that line
words like good and strong get rejected, every question comes back as something present in the item or absent from it
every option list gets an exit, so an item that fits nothing comes back marked instead of answered
the 10 rules behind this prompt and three sets you can copy as they stand are in the article below
Restaurant teams get reservation questions during the busiest part of service. Gudalis handles menu and table questions, then keeps booking requests moving while staff focus on guests: https://t.co/o1mExd42yD #Restaurants#RestaurantTech#AI
The M5 Ultra was pausing 96 extra times for every word Qwen3.8 Flash Next wrote, but now its fixed!
MLX, the library Macs use to run AI models, sends work to the GPU in batches. When a batch touches more than 50 MB of memory, it sends it away and starts a new one.
This model stores its expert weights in huge 1 GB blocks. Each word only needs a small piece of each block, but MLX saw "1 GB" every time and cut the batch short. That created 96 unnecessary interruptions per word.
The fix: point the GPU at just the small piece it needs. And it's now merged on main of oMLX!
What is a way to test human-level generality in artificial intelligence?
"The meta-benchmark of being able to pass ARC-AGI-(n+1) immediately upon release"