@ADLXBT@jetbrains@NVIDIARTXSpark 150k right now, but we have a couple of optimizations in mind that will let us use the full 256k context window of the Qwen models. Stay tuned!
@philppplik@jetbrains@NVIDIARTXSpark Right now, we are using ~22 GB with 150k context. You can reduce context to 100k and get ~1 GB back... but we have something in mind that will (hopefully) work for 16GB cards, and then you will have plenty of room for the app :)
Your GPU. Your code. No token bill.
Junie Local runs on NVIDIA RTX Spark from day one. Windows support is stable, too.
Reads code. Edits files. Runs tests. All locally.
Try it free → https://t.co/whHL3D11he
Today we introduce JetBrains Air - the product system for software development orgs in the age of agents.
Built for developers, team leads & engineering directors.
Open and flexible: steer and control almost any LLM & harness.
Read more:
https://t.co/pXzAn10bnP
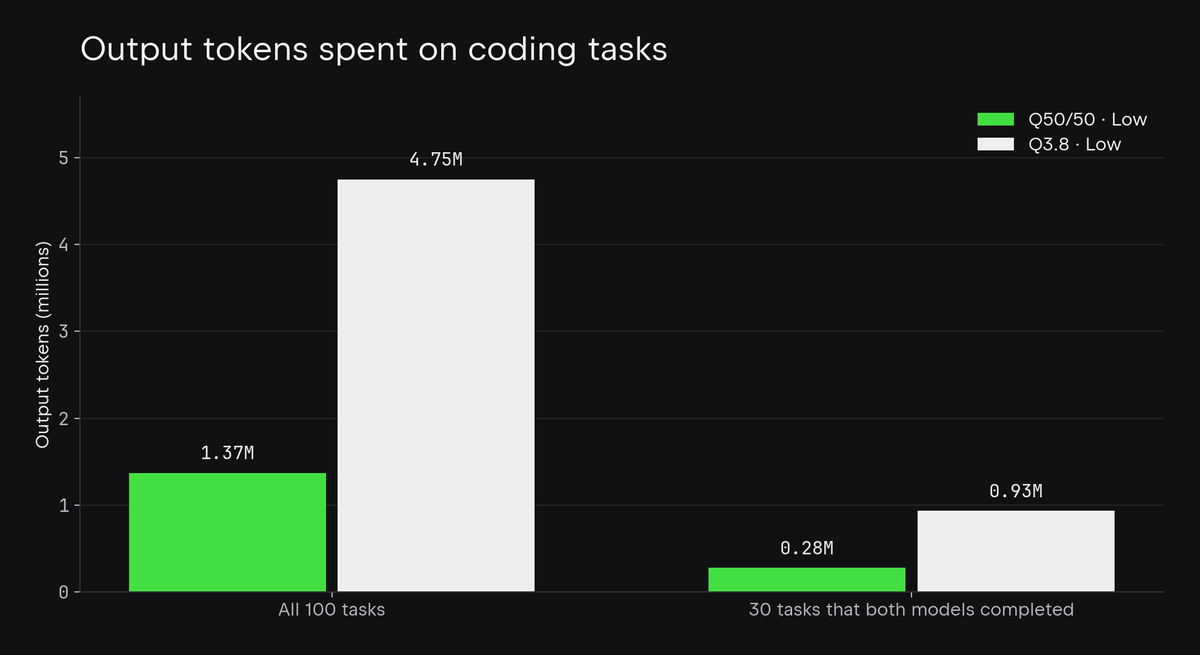
We mixed Qwen 3.8 and 3.6. Literally.
A 50/50 weight merge. One 27B model. 71% fewer output tokens than 3.8 in our internal coding eval.
Junie Local has an update. Windows devs, you're invited too 🤝
@andrewtek@jetbrains If you mean Junie Local, then it is obviously behind :) But it is almost on par with GPT-5 medium, which was released a year ago. The fact that you could run locally something that was a year ago in the cloud is... awesome!
@thearchitect452@jetbrains And don't forget there are Intel cards :) Granted, they are not the best in terms of performance, but there are 24GB models that we are going to experiment with.
@thearchitect452@jetbrains Well... Right now, AMD AI chips are unstable and slow. I mostly blame the drivers, not the hardware. So maybe we will in the future.
@andrewtek@jetbrains No, reasoning is memory-speed-bound, so doubling the capacity won't help with that. The M5 Pro will probably work, but it could be up to 2 times slower than the M5 Max.
JetBrains takes its first step toward Local AI.
MacBook M5 users can set up Junie Local in one click and get a solid agentic experience.
Unlimited & Fully local.
Folks also had some fun presenting it on a plane :)
Check it out & stay tuned for more:
https://t.co/0ZHXTm92Cx
@jmanuelsoberano@jetbrains We are working on that right now, so I would say ~ a month from now. But you would need a powerful GPU with at least 24 GB of VRAM.
Junie can now run entirely on your machine, and it’s completely free to use.
One command: /local. We picked and optimized the whole stack around the model: agent harness, model parameters, and inference engine. No tokens, no quota, no code ever leaving your machine.
@kajigor@var_lynx Ну не совсем. Надо чтобы вайтишник хотел обучаться. А то хватает людей аля "я умею открывать консоль разработчика в хроме, дайте мнохо денех". Ну а те, которые бы круто смогли бы обучиться частенько думают "ну я же ничего не знаю, я же точно не подойду"...