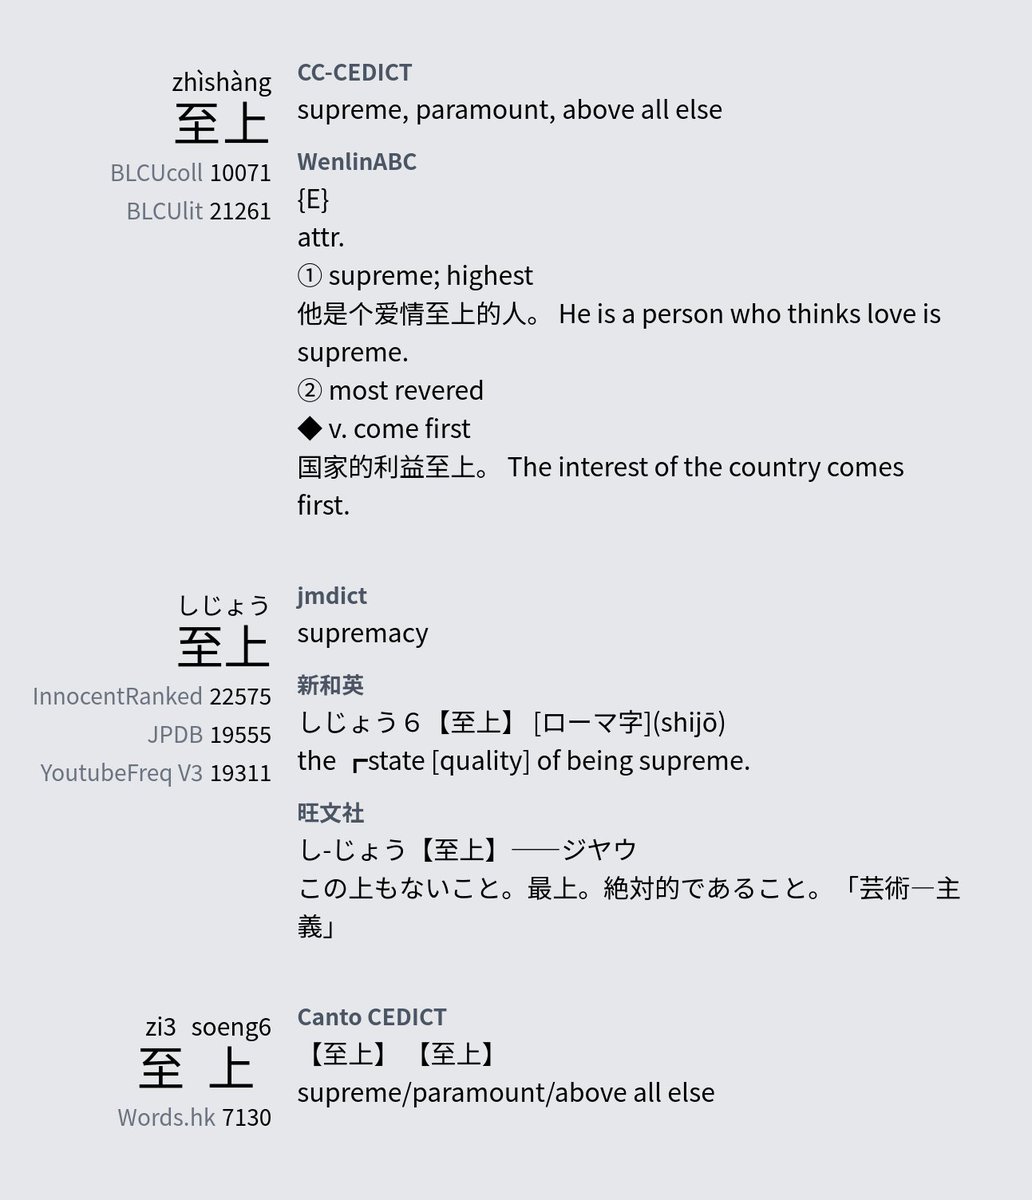
traversing the word graph, with links corresponding to characters that are shared between words (blue is when the reading is also the same, red is when it isn't)
all of this used to be implemented in "userspace" in about 1kloc of rust in a previous version—turns out you can do it with less than 150 lines of sql, which also happens to be several times faster
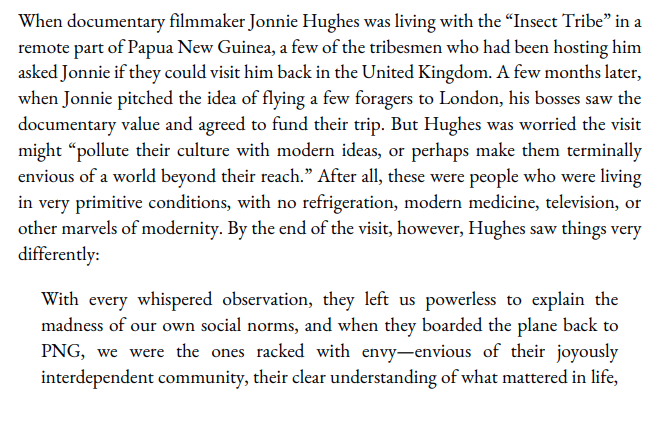
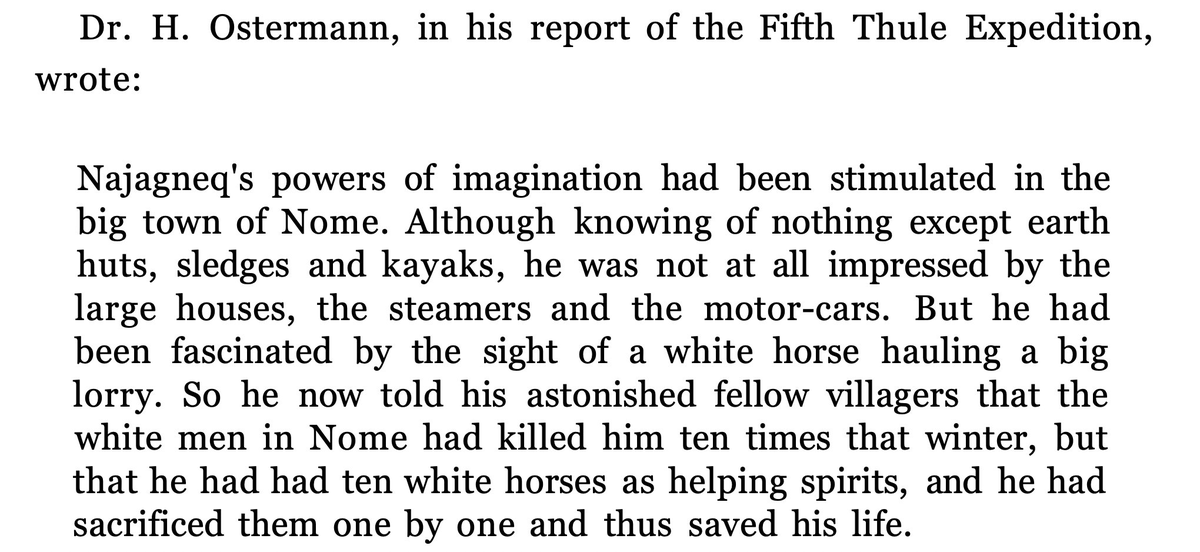
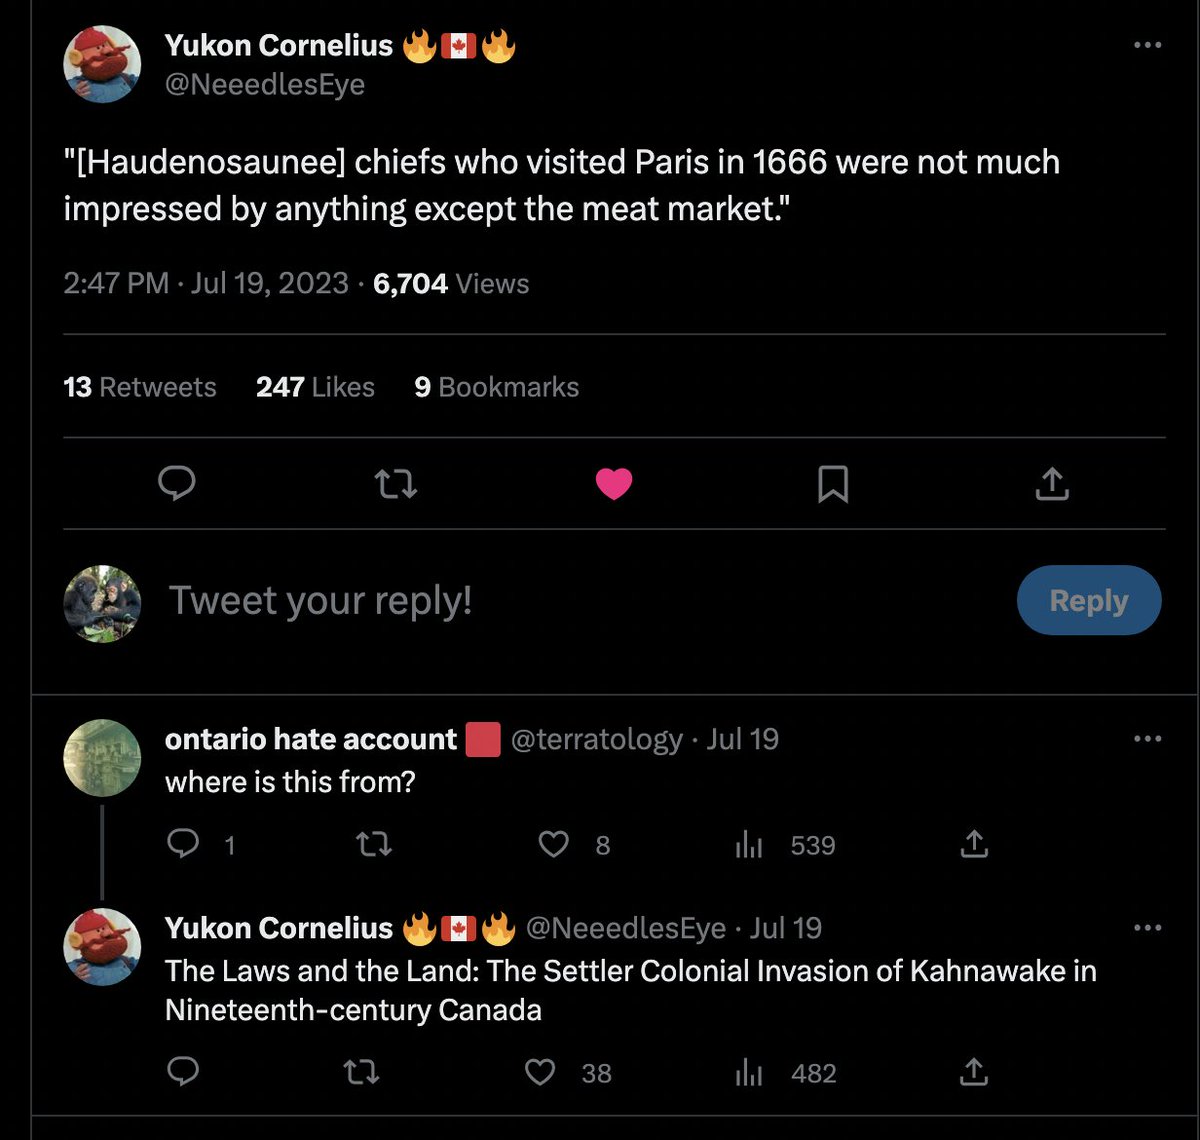
I love—and keep encountering—stories of people from radically different cultures encountering modern/western cities for the first time and being unimpressed except for one specific thing.
Do you know of any other stories like this?
i read a short story by kawabata yesterday evening (titled 心中, if you want to look it up) that completely, como se dice, bodied me despite being less than two pages long
a long but otherwise straightforward query gives me the verbs most frequently used in a book (or across a library)
this will be more interesting once i've hooked up the spaced repetition to this again and filtered out everything that isn't already marked as known
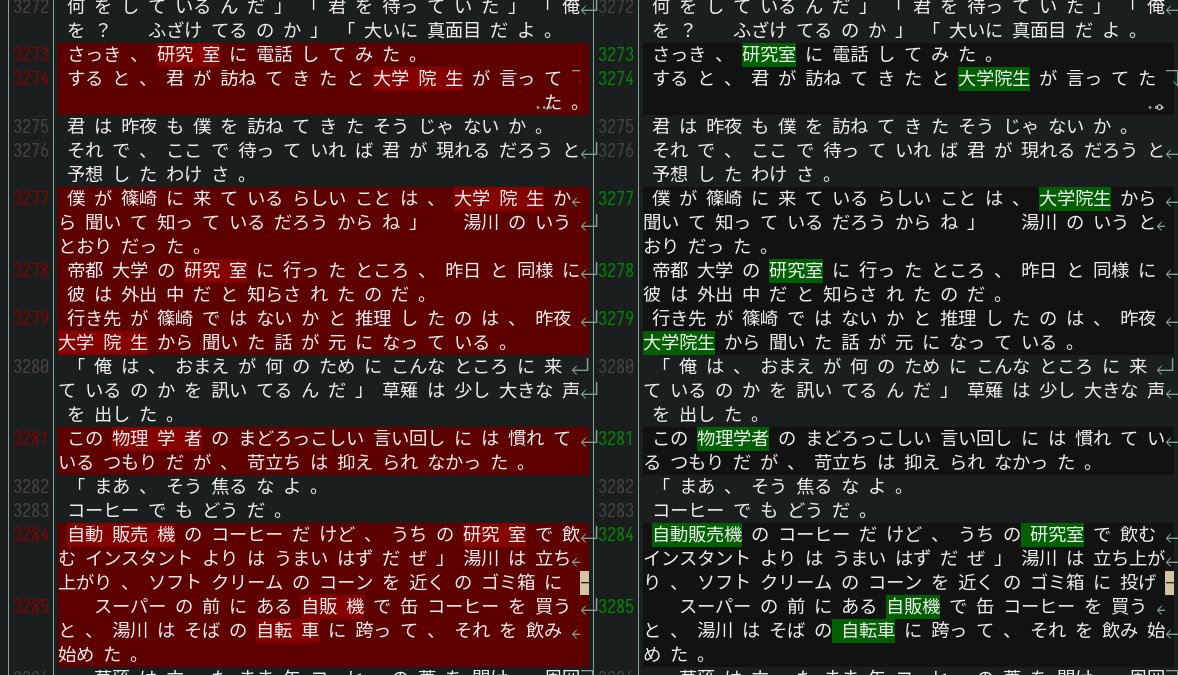
rather pleased with how the furigana annotator has turned out
it's not in the screenshot, but this also tracks what rule/heuristic was used to match the dictionary ("underlying") reading to the word (e.g. かた -> がたvia rendaku, オー -> おう is "LongVowelMark", and so on)