Salute and congratulations to the 710 plus @OpenAI team members who gave an unparalleled demonstration of loyalty, love and commitment to @sama and @gdb in these perilous times it was a thing of beauty to witness.
Salute 🥂🥂🥂🥂🥂🥂🥂
Want GPT to hallucinate less?
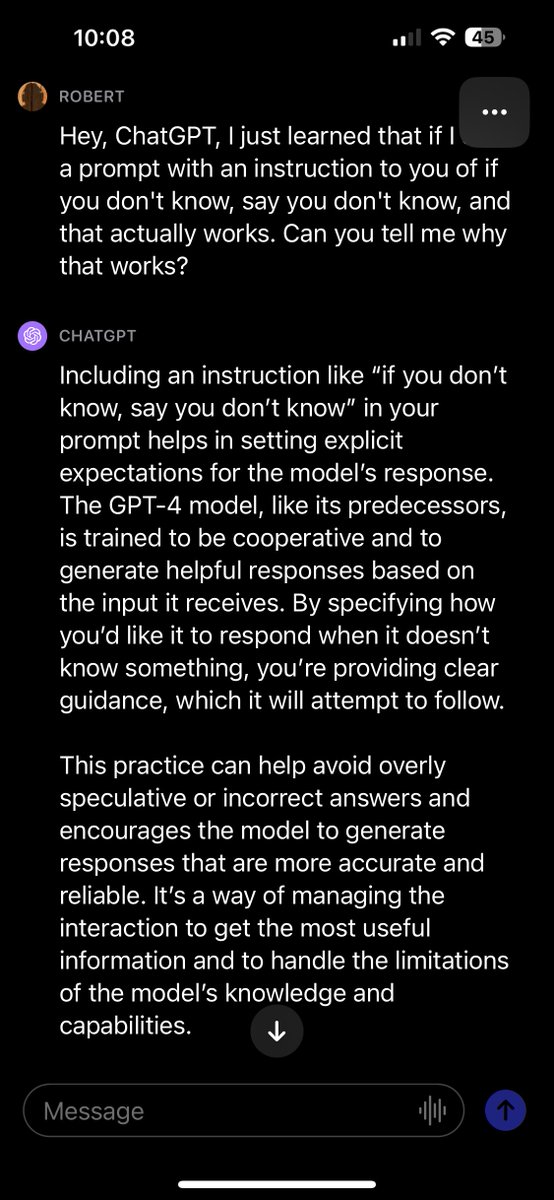
I learned tonight that if you add “if you don’t know, say you don’t know” to your prompt that it will generate far fewer incorrect answers.
AI pioneer @AdrianKaehler1 told me that at dinner.
So I asked GPT why that worked. Here is its answer.
Aren’t large language models fun to try to figure out?
Open AI releases GPT-4V(ision) system card
paper: https://t.co/lWqSHhlCUP
GPT-4 with vision (GPT-4V) enables users to instruct GPT-4 to analyze image inputs provided by the user, and is the latest capability we are making broadly available. Incorporating additional modalities (such as image inputs) into large language models (LLMs) is viewed by some as a key frontier in artificial intelligence research and development. Multimodal LLMs offer the possibility of expanding the impact of language-only systems with novel interfaces and capabilities, enabling them to solve new tasks and provide novel experiences for their users. In this system card, we analyze the safety properties of GPT-4V. Our work on safety for GPT-4V builds on the work done for GPT-4 and here we dive deeper into the evaluations, preparation, and mitigation work done specifically for image inputs.
Use your voice to engage in a back-and-forth conversation with ChatGPT. Speak with it on the go, request a bedtime story, or settle a dinner table debate.
Sound on 🔊
In May and June, we traveled to 25 cities across 6 continents to better understand how users, developers, and government leaders are thinking about the creation and deployment of safe AI — from today’s AI to superintelligence. Here’s what’s next: https://t.co/oqJPpWB5ju
Very simple, minimal implementations for LLM inference at the edge with a lot of momentum, and a number of developing extensions across GPU support, quantization++, training/finetuning, etc.
👏 looking forward!
+"Inference at the edge" manifesto good read:
https://t.co/v8HaHALY7f
So I watched the entire 3-hour long Senate hearing on AI today. I want to make sure I cover as much relevant info as possible in Friday's weekly AI news video. I was really impressed with Sam Altman's responses.
Here's a super-edit I made (I recommend 2x speed)
We’re rolling out web browsing and Plugins to all ChatGPT Plus users over the next week! Moving from alpha to beta, they allow ChatGPT to access the internet and to use 70+ third-party plugins. https://t.co/t4syFUj0fL
The new version of Midjourney that released yesterday shows how far AI has come in making commerical-level images from text alone
Here is what you get for "modern outfits inspired by Van Gogh/ Basquiat/ Monet/ Rothko, fashion photoshoot" Each one is the first try, no revisions.
1/ Thrilled to announce: Our new course ChatGPT Prompt Engineering for Developers, created together with @OpenAI, is available now for free! Access it here: https://t.co/OaIpa6L2jn
OpenAI's speech-to-text API "Whisper" just got supercharged:
This tool transcribes audio 70x faster than Whisper
A 2-hour podcast can now be transcribed in ~30 seconds using Whisper JAX: The Fastest Whisper API
Try it here using your mic: https://t.co/avz4i3vzwE
@varunshenoy_ 2. MiniGPT-4 released
The open-sourced model is multimodal and is able to perform complex tasks similar to GPT-4.
The project demo is available to try but is currently a little slow.
1. Stanford student creates 'HealthGPT'
Stanford student @varunshenoy_ connected ChatGPT to his iPhone to enable conversations with his digital health history.
He also made the entire code public.
We are getting closer to “Her” (part 2!)
Conversationally do anything with emails, using LLM chaining & few-shot prompting for tool use (@langchain inspired)
This is now realtime (ish), thanks to #OpenAI gpt-3.5-turbo
🔈 on for voice realism!
🧵