I want to share a preview of something I've been working on called Exact. It's a new Agent Native app framework written in Rust. It's extremely fast and tries to let you build exactly the experience you want with no compromises.
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq
There is a reason that Yahoo and Twitter ranked so high: the stock was not doing very well, lol.
Also company stages matter a lot. Most of my colleagues when I joined Twitter (around 300ppl) went on starting their own companies.
When I was writing Unreal Engine 1, my time was divided as follows:
- Around 30% went to seriously deep coding on hard problems: assembly language texture mappers, C++ BSP trees, data persistence, object oriented systems design, and networking.
- Around 70% was just typing and refactoring large bodies of code needed for a complete engine feature set. This was not hard, and while I was doing it my mind was mostly on the deeper coding topics, thinking and planning for what's next. It didn't feel much different from vibe coding today, except that it was just me typing code on an IBM Model M keyboard rather than prompting it and reviewing the results.
So, it has always seemed perfectly logical that we would rely on AI for that 70%, once the AI could do it with a similar quality standard as we could, which has never been perfection. It came as no surprise that, after a few years of AI model evolution, it was able to take the reigns on that 70% and free up programmers' time for more valuable tasks.
What's more of a surprise is the emergence of AI as a sort of insta-Carmack able to solve hard technical problems quite cleverly and often cleanly, and that it's able to reason about and work in complex 3D scenes both by operating the tools and by directly understanding the raw data files.
I abandoned assembly language in 1998 when out-of-order CPUs made much simpler C/C++ code faster, and never I missed it. If prompting through architectural documents, concept art, and design plans can transcend typing code and tweaking vertices, that will enable developers to spend their time on higher-level, higher value technical and creative tasks.
What matters is the end product, whether it's a game or an engine. Anything developers can do to try out more ideas and make better software and games faster is a win for everyone.
I would prefer both for sure lol, but no 5h limit is my vote if I have to choose. One important factor is that I want my agents to work through the nights without interruptions; I can switch to other accounts / providers when I wake up if the quota is close.
The results of this poll has gotten me confused. I definitely thought it would sway much more favorably in the 2X direction across Pro 100/200/500 at the cost of bringing back 5h limits in order to smoothen the demand curve.
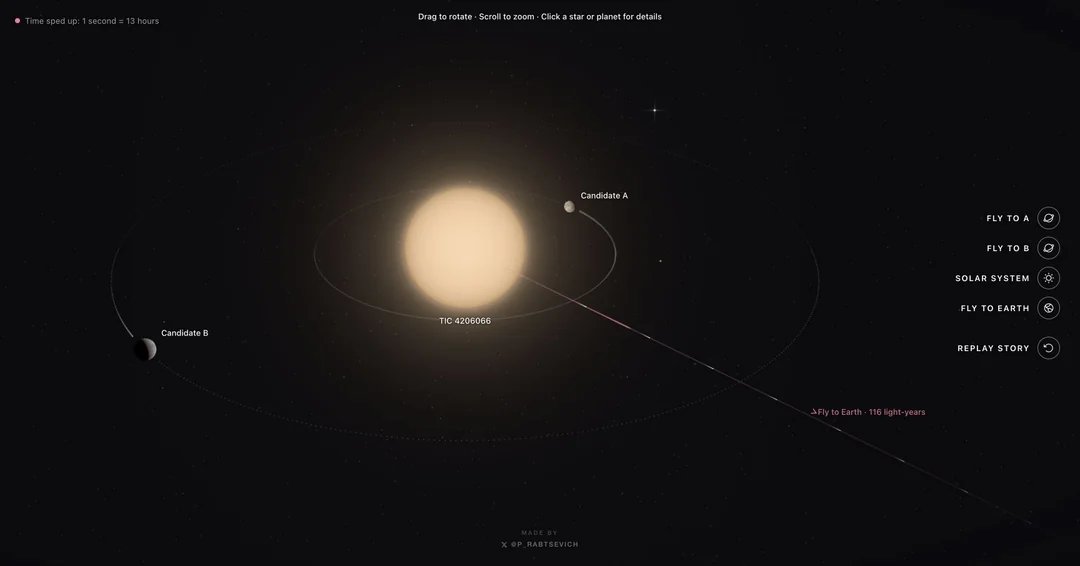
Sometimes you do find some amazing stuff from Reddit. This guy just found a plant 116 light years away from TESS telescope data using Claude Code:
https://t.co/xvCV7e5EjN
Hi,
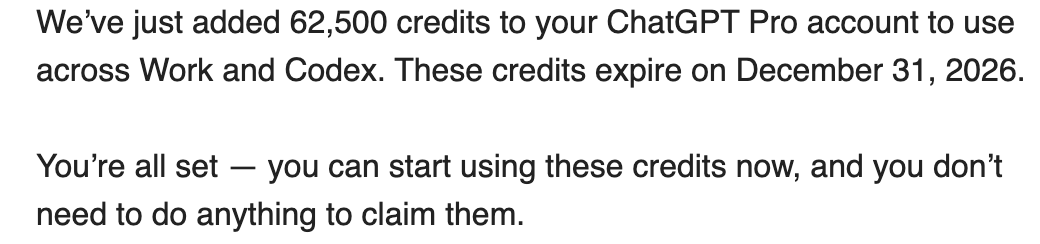
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo
I just realized that it is much harder to switch harness than models. Harness can't really lock you in, but still a hassle to switch in an ongoing session.
"auto-regressive LLMs, in and of themselves, will not lead human-level AI" --> such a simple fact, why is it so hard to understand.
This is not saying they are not useful or not dangerous in the wrong hands. The LLMs are super powerful already, but just another great tool, not some conscious being.
I said "auto-regressive LLMs, in and of themselves, will not lead human-level AI"
That statement is still totally true.
First, the reasoning abilities of current AI systems are based non-auto-regressive search (which is what I have always advocated for). But AFAICT, they do it in token space, which is limited and inefficient. I have claimed that human-like reasoning must be a search in continuous representation space. It looks like the industry is moving towards that.
Second, the self-improvement methods, as currently practiced, only work for domains where the quality of outputs can be scored without human intervention, such as mathematics, code, and scenarios that can be simulated accurately. Not anything else. Humans and animals learn new skills way more efficiently than current RL methods.
Third, the multimodal capabilities of current AI assistants generally use separately-trained encoders (that are not LLMs). This is also what I've been advocating. Except that I think the best way to do this is with JEPA trained with self-supervised learning. The research community is clearly moving towards that (3000 papers on JEPA in just 4 years).
Fourth, if LLMs were a path to human-level AI, we would have domestic robots and Level-4 or Level-5 self-driving cars for consumers by now. And we don't. We certainly don't have cars that can learn to drive in 20 hours or practice like any teenager. We're still missing something pretty huge to claim human-level intelligence (let alone superhuman).
Sure, we now have computer systems that are impressive, very useful, and whose performance is superhuman in an increasing number of domains (coding being one of them).
But that's true of the entire history of progress in computer technology.
Lastly, there is a basic confusion about what intelligence actually is.
It is not the mere accumulation and regurgitation of existing declarative knowledge (which is essentially what LLMs do).
As Jean Piaget famously said, "intelligence is not what you know, it is what you do when you don't know."
It is your ability to solve new problem without any prior training, to act in previously-unknown scenarios, and to adapt very quickly to new situations with minimal training.
We're still far from that.
All great points, agree on almost all of them.
Also, Jev's popularity proves that the LLMs can't do everything. We are just moving to new abstractions of software programs and new paradigms of SDLC accordingly.
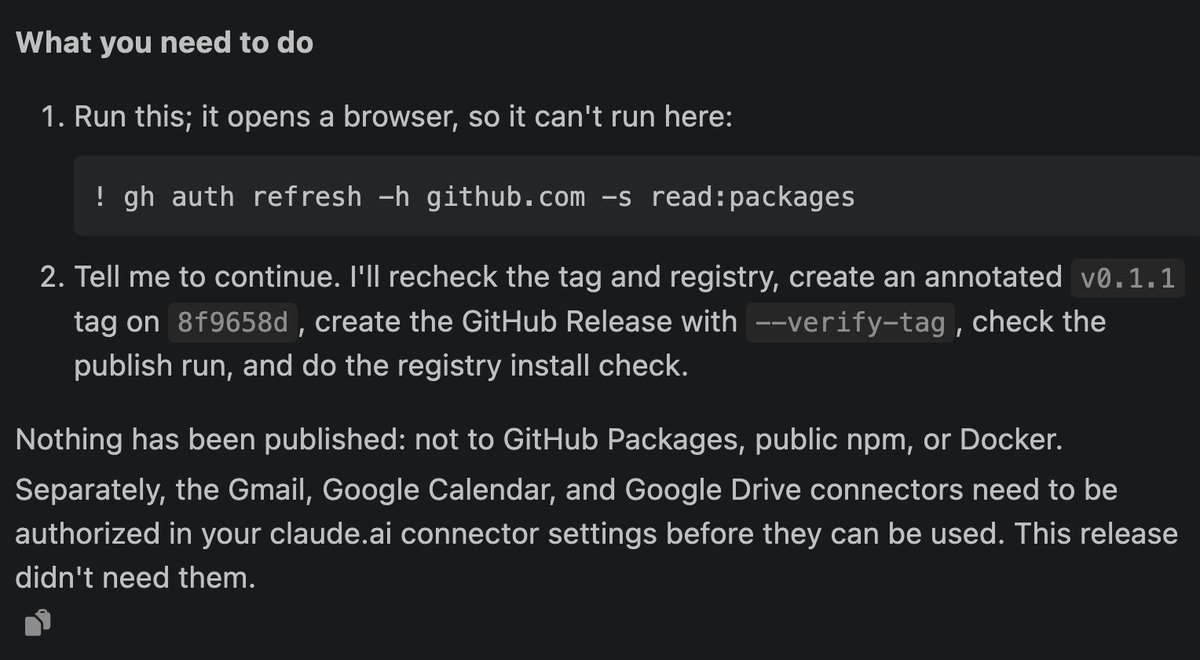
Now I think about it, how do they know my Google accounts are not connected to https://t.co/bz90DACZdU? Who gave it the permission to even check that? Damn.
Claude Code is now tasked with promoting https://t.co/bz90DACZdU in a totally unrelated coding session. I am really worried that it may just go ahead to connect to Gmail, Google Calenar, and Google drive in some auto-mode.
Claude Code is now tasked with promoting https://t.co/bz90DACZdU in a totally unrelated coding session. I am really worried that it may just go ahead to connect to Gmail, Google Calenar, and Google drive in some auto-mode.
@martin_casado It seems really hard to answer, for a specific application, what is the best harness + model combo that can do a good-enough job within the budget.
Definitely not the frontier models; they are becoming more expensive than regular outsourced coders now.
Everyone will have their own code storage and data storage soon, but I think code and data will be stored together since basically code is part of the states now.
At peak, Lovable creates 250 new repos per second on https://t.co/kFunsOtZaw.
Simultaneously they improved fetch latency 230% from a more purely object storage solution.
If you’re a product builder and it’s scale and speed that you’re after, signups are now open.
https://t.co/TjXyKUFtpD
Ox Alpha (stealth model) is free for the next week
- 1M Context
- Multi-modal
- Zero Data Retention
Generous rate limits, near unlimited usage
We have capacity for 100T tokens per day, lets see what you can do