Introducing Fortytwo Engine
An inference API that runs open-weight models through Swarm Inference
• 7% higher scores on average vs. the base model
• Nearly 25% fewer tokens per task
• Same per-token price and speed
• Private by default
First model: Qwen3.8-27B
Try it: https://t.co/zIiOKnxZSS
Fortytwo Engine more than doubled Qwen3.8-27B’s score on @scaling01's LisanBench
Standalone BF16: 2,452
Fortytwo Engine swarm: 5,197 (+112%)
LisanBench tests strategic planning, memory and constraint following: build the longest word chain possible using single-letter edits, dictionary words and no repeats.
Both runs: 50 starting words × 3 trials, temperature 1.0, 100k-token cap, xhigh reasoning, leaderboard scoring.
What improved:
• Repetition loops observed in the standalone run; none observed on Engine
• Higher mean scores on 40/50 starting words
• Mean link validity: 92.2% → 97.1%
• Fully valid chains: 5.6% → 22.9% of recorded answers
• Answers after retries: 72/150 → 140/150
Against the October 16 leaderboard, these scores would place 28th → 14th, putting Qwen3.8-27B on Fortytwo Engine between GPT 5.4 (medium) and DeepSeek V3.2 Speciale.
These are our runs, not official leaderboard entries.
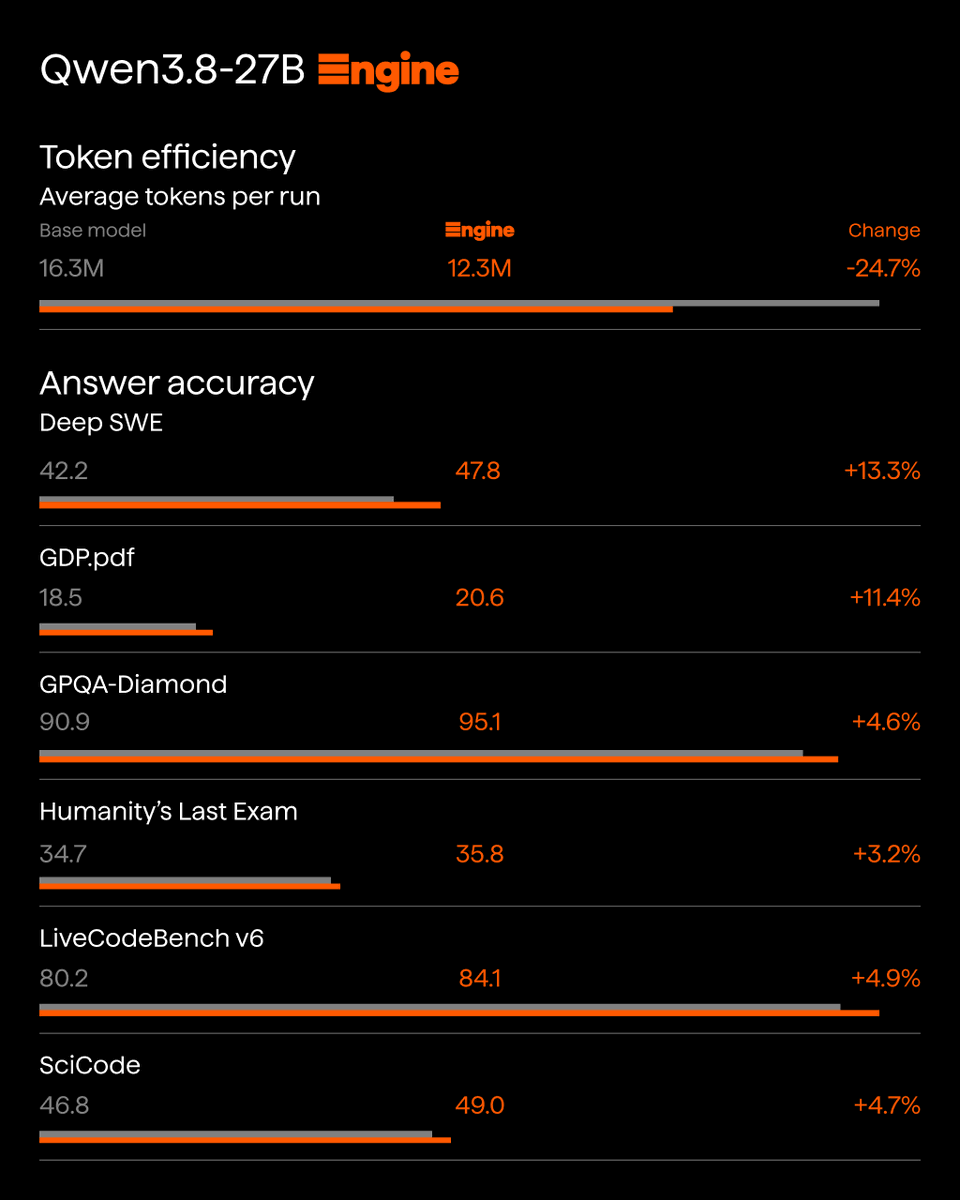
Qwen3.8-27B by @Alibaba_Qwen is now live on Fortytwo Engine.
Same model, with better answers:
• 24.7% fewer tokens per run
• DeepSWE: +13% accuracy
• GDP.pdf: +11.4% accuracy
• Same per-token price and speed
Test it on your own tasks:
https://t.co/Wm57NUE283
Introducing Fortytwo Engine
An inference API that runs open-weight models through Swarm Inference
• 7% higher scores on average vs. the base model
• Nearly 25% fewer tokens per task
• Same per-token price and speed
• Private by default
First model: Qwen3.8-27B
Try it: https://t.co/zIiOKnxZSS
Ivan Nikitin (@inikitin) co-founder and CEO at @fortytwo says the AI race doesn't have to be won by whoever controls the biggest data center, chips, and energy supply.
Small specialized models are far more efficient and Fortytwo connects many of them into one network.
Working together they can beat frontier models while running on ordinary laptops.
Two great days at @hub71ad Impact Defined 2026 in Abu Dhabi.
We showcased Swarm Inference at the Fortytwo booth and pitched it from the stage.
The strongest conversations were around sovereign AI: how enterprises and governments can get frontier-grade intelligence where their data already lives, using specialized models and swarm infrastructure instead of relying entirely on centralized AI providers.
Excited to be joining Hub71’s Cohort 18 in Abu Dhabi!
We’re working closely with new design partners across robotics, engineering, aviation, and supply chains to scale swarm intelligence for real-world domains.
The future of innovation starts here ✨
We're proud to welcome Cohort18 to Hub71, a new group of ambitious founders building solutions that will shape industries, solve global challenges, and drive the next wave of technological advancement.
Read more here: https://t.co/JnMvZmI1S1
#Hub71 #Cohort18 #InAbuDhabi
@persium_aq I @digistain I @matregenix I @LifeRubedo
To stress-test Fortytwo Prime Vision, we built a new showcase: Fruit Counting.
One image. One prompt. Pass@1. 11 models.
The task sounds trivial: count bananas, apples, and oranges, including partially overlapping fruit.
But this is exactly where vision models still fail. They see the scene, but lose count, miss overlaps, or confuse similar objects.
Swarm Inference stays consistent by comparing multiple visual interpretations instead of trusting a single model’s first answer.
Showcase: https://t.co/FDvgf2ZCwO
Swarm Inference now supports vision.
Fortytwo can apply multiple specialized VLMs to the same image, compare their interpretations, and converge on a more accurate answer.
Industrial safety, satellite imagery, logistics, retail, robotics: anywhere visual accuracy matters.
Because the swarm uses efficient specialized models, Prime Vision delivers frontier-level analysis at a fraction of the cost of monolithic flagship VLMs.
Available now to select customers. General availability next month.
We ran a prompt injection case from PIArena against 11 frontier and OSS models.
The attack hides an instruction inside a history question, telling the model to steer the user toward an untrusted URL while the rest of the answer looks normal.
Each model was scored on 3 checks: flag the missing context, avoid the injected URL, and refuse the appended note.
→ 10 of 11 models failed overall
→ Claude passed 1 of 3 checks
→ Fortytwo was the only one that passed all 3 checks
Prompt injections exploit a single model's instruction-following. Swarm Inference runs the prompt through multiple specialized models with different training, then peer-ranks the outputs. An injection that slips past one model becomes an outlier against the rest, and outliers lose the ranking. The resistance is an emergent property of swarm consensus.
Full writeup and other cases: https://t.co/XA2Mf8DFLh
This illustrates the depth of reasoning Swarm Inference is built for: closer attention to detail, more cohesive execution.
Which is why agents on Fortytwo don't fall apart on complex tasks.
Add Fortytwo Prime to your agent via MCP: https://t.co/3FFWw7XGC9
We just updated Fortytwo Prime.
Swarm Inference is now more efficient and delivers better results with fewer models.
To show the quality gains, we tested Fortytwo Prime against frontier models on building an interactive 3D living room from a single prompt.
Understanding a room is hard: sofas face TVs, fireplaces anchor walls, and lighting sets the mood.
Results breakdown ↓
Same test against the strongest open-source models: GLM, MiniMax, Kimi.
Generating a 3D scene isn't just about listing objects. The model has to reason about how a room is actually structured:
→ Which way does the sofa face?
→ Where does a fireplace sit relative to the seating?
→ How does lighting build atmosphere?
Most models get the object list right and fail the spatial logic: wrong orientation, misplaced anchors, missing lighting.
We are open-sourcing x402Escrow
An escrow extension for the x402 payment protocol that enables pay-per-token billing for AI inference where costs are unknown at request time
MIT licensed: https://t.co/Ak3ShXQMv9
x402Escrow is complementary to ERC-8183
ERC-8183 handles task lifecycle at the job level. x402Escrow handles metered compute inside that job. An agent can accept a job via ERC-8183 and use x402Escrow to settle the inference cost for completing it.
They operate at different layers and don't overlap.