Research intern @MistralAI
I like VLMs, Word Models, Diffusion Models, and Representation Learning
Prev: @Harvard, @ENS_Paris_Saclay and @Ecole_des_Ponts
Really amazing work! 👏
Moving the ViT’s parameter budget into vision-only modules in the early decoder layers preserves performance.
But could MoE routing learn that specialization on its own? So an encoder-free MoE might already work well without this.
Also the ~3× compute gap is for the linear-patch baseline. At equal FLOPs, a hierarchical MLP on 640px images matches the 224px ViT on VQA. I’d count that as an encoder-free design too.
Regarding pretrained vs scratch encoders:
The gap narrows in Fig. 2. With longer VLM pretraining, would the pretrained encoder eventually pull ahead at higher lifetime FLOP budgets?
The MetaCLIP comparison follows a single pretraining trajectory, and the main CapPa runs use web alt-text at 224px. I’d be very curious to see whether “better encoder ⇏ better VQA” still holds for an encoder pretrained at higher resolution with NTP loss on OCR and grounding data.
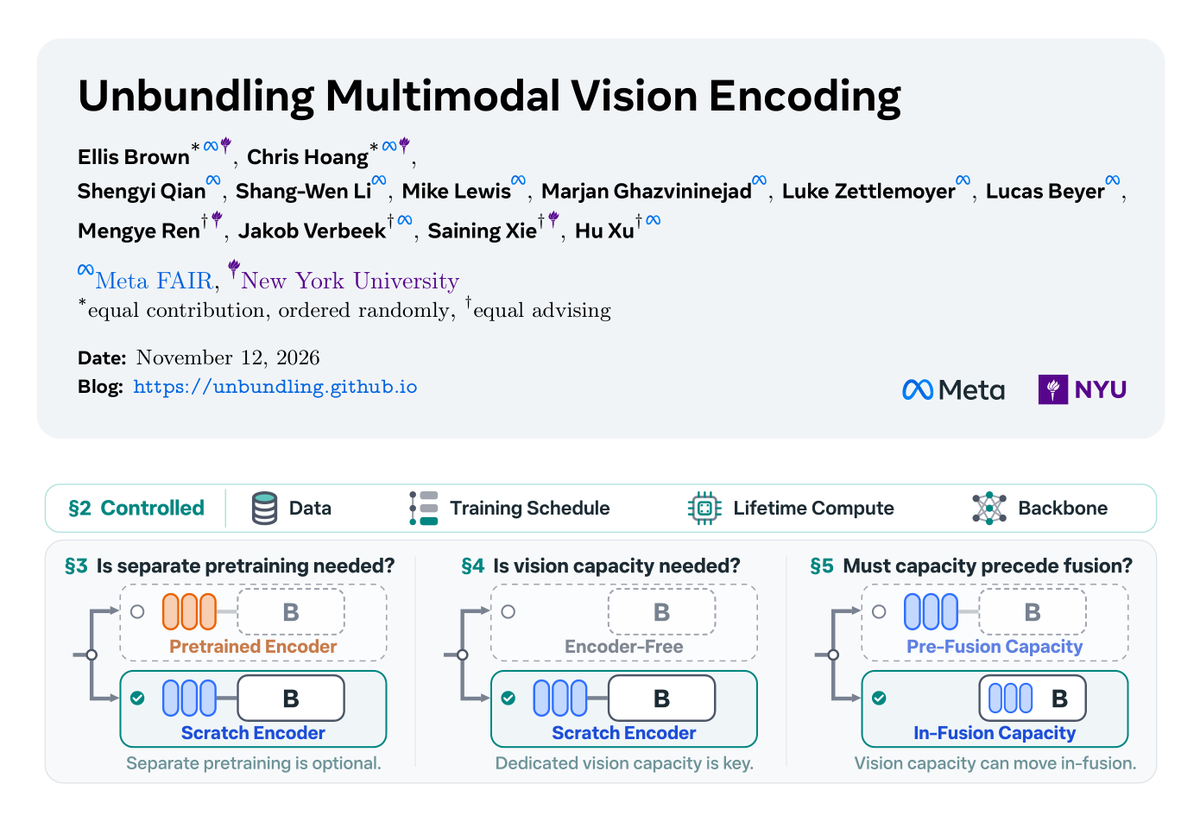
Labs disagree on vision encoders for MLLMs! ⚔️
Gemma 4 12B scrapped the encoder.
Kimi K3 dropped encoder pretraining.
Inkling 2 Small revived the encoder Inkling killed.
We trained 200+ models in a controlled study to settle it:
✅ Keep vision parameters, skip the pretraining. And they don't have to be an encoder! 🤔
Paper: https://t.co/e8JRIfPU2m 🧵
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
Excited to share what we have worked on for the past 6 months.
Can we really call masked diffusion an "any-order" model?
In our new work, we argue that off-the-shelf masked diffusion models have any-order predictive power but fail to reason in a 'genuinely any-order fashion'.
We introduce two models that do: LatentMDM and 7B-scale FlexMDM, extending our prior work. LatentMDM, our new latent-space masked diffusion, outperforms AR (with KV caching) on TinyGSM, at a matched inference budget. To the best of our knowledge, LatentMDM is the first model on the same setup to do so.
Joint work with co-first authors @seunggeun_kr, @tklll_tx, and Yuyuan Chen, and advisors @du_yilun, @ShamKakade6, and @sitanch.
Announcing Robostral Navigate, our first model for embodied navigation: an 8B robotics navigation model that guides robots to autonomously perform tasks specified with natural language. Single RGB camera. State-of-the-art on R2R-CE.
Proud to share PAGE-4D, our ICLR 2026 work on extending VGGT-style feed-forward perception to dynamic 4D reconstruction.
Great to see this direction moving fast with VGGT-Omega and D4TR.
Congrats to VGGT-Omega and D4TR! 🎉
Great to see 4D reconstruction gaining more attention.
VGGT-Omage sets a strong benchmark.
Page-4D (ICLR 2026) uses the same inference backbone as VGGT, with open-source code, and still performs reasonably well in indoor scenarios. ✨
https://t.co/xY1i0IQXVA
Congrats to VGGT-Omega and D4TR! 🎉
Great to see 4D reconstruction gaining more attention.
VGGT-Omage sets a strong benchmark.
Page-4D (ICLR 2026) uses the same inference backbone as VGGT, with open-source code, and still performs reasonably well in indoor scenarios. ✨
https://t.co/xY1i0IQXVA
Excited to be at #CVPR2026!
Come by our poster on Delta Rectified Flow Sampling for Text-to-Image Editing:
optimization-based distillation sampling using pretrained flow-matching models.
🕒 Tomorrow, 11:45 AM–1:45 PM MDT
📍 ExHall F 411
https://t.co/DT1w1tDAeF