Founding Engineer at @cubic_dev_
Thinking about AI, code review, and how to make them actually useful.
I also nerd out about product, business and dance.
Anthropic has undone their nerfs to Opus. On our internal benchmarks, Opus had dropped in performance by 5 percentage points consistently in the past 1-2 weeks. Since the second half of April 10th, it is back to the performance pre-nerfs.
One of the least glamorous parts of building AI products is choosing what gets worse.
Higher quality usually costs more.
Lower cost makes the product less useful.
More flexibility usually makes it harder to use and maintain.
A lot of product work is being willing to choose.
@everythingLLM@rdominguezibar@ycombinator@cubic_dev_ Yeah, agreed. I’m at Cubic, and a strong benchmark score is useful, but it is far from the whole story.
The real challenge is catching issues that actually matter to the specific team. We’re working on that constantly, and we'd love to hear where you think we still miss.
BREAKING: a @ycombinator startup just beat Claude Code, Cursor, and Gemini 😳
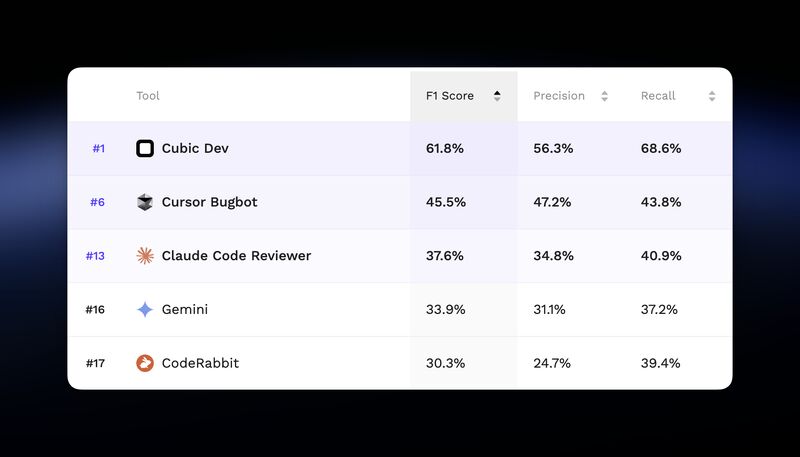
@cubic_dev_ (YC X25) ranked #1 on Martian's independent code review benchmark:
▫️ Cubic: 61.8% F1
▫️ Cursor Bugbot: 45.5%
▫️ Claude Code Reviewer: 37.6%
▫️ Gemini: 33.9%
▫️ CodeRabbit: 30.3%
That gap between first and second place is bigger than the gap between second and last
Cubic's founder @PaulSangleF:
"If your team is on cubic and your competitors aren't, that's an unfair advantage."
Which AI code reviewer is your team actually using?