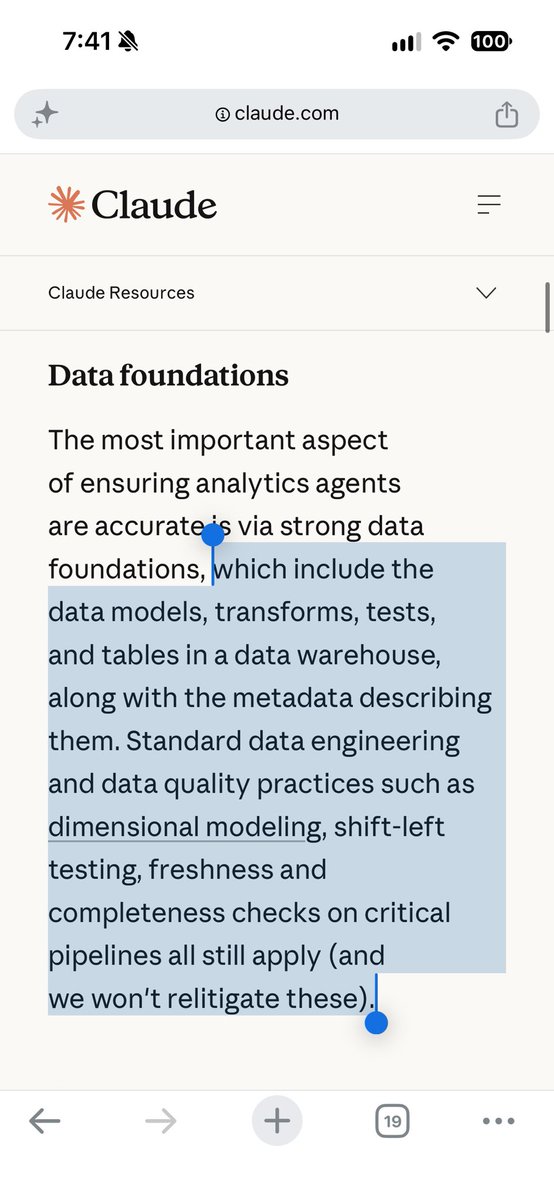
Sorry guys. Software engineering and programming are dead. You just need to have perfect specs, unchanging requirements, an agentic deployment framework for high frequency releasing, and engineers with good taste and judgement.
@harrisonju yep, thing is, no one non-technical takes advantage of that 😅 my experience is that people end up describing the machine they need on markdowns, and Claude builds the scripts each time someone executes the skill
I’m unsure about skills. They empower users, but I’ve found distributing them as-is just burns tokens.
My best strategy so far is to flesh the domain rules into py scripts and have the LLM call them.
@HanchungLee why? assume I’m the one curating the scripts and they live in the backend.
I guess what I’m doing is kind of turning token burning (but high business knowledge dense) skills into a controlled MCP
@kirsten_lum_@IronRedSandHive Curiously, my mind has recently been comparing data infra with real infra. Org has an ETL that simply pulls everything from the transactional schema into snowflake, and I don’t feel there’s much difference between that and the Brooklyn Bridge.
Talks and slides:
Código Facilito · IA para datos
Clase 1: https://t.co/aafZfVO7Vh
Clase 2: https://t.co/kcUiZ7lBNI
Clase 3: https://t.co/SMuqVKtgdG
GBM · AI Experience: AI & Finance
Talk + panel: https://t.co/dIAtVkkeHz
Slides: https://t.co/ItVvCJu6HK
Snowflake World Tour · El futuro de los servicios financieros
Slides: https://t.co/DKbRUbigzt
Claude Community · Tool use sin abstracciones
Slides: https://t.co/lfQqkpZ7U8
The Data Pub · Post AI Data Stack
Talk: https://t.co/KdERH03762
Slides: https://t.co/VmCzstQsxY
El inicio de otoño me dio la oportunidad de dar 7 pláticas diferentes. Abajo un recap.
El mensaje core: los agentes abarataron producir análisis, pero acordar qué es correcto para una métrica sigue siendo difícil, eso es parte clave del trabajo moderno de datos.
i've reproduced the results from the MIT blog post today on weight-space programming. but one additional result i have to add: this is a new, step-change emerging capability that's appeared in just the latest set of models.
I don't think we should fight. The two companies are complementary. Since you're not doing this AI stuff, I really think Snowflake should consider getting its AI tokens through Databricks. You can get both cheap OSS models as well as frontier (OAI/Ant/Gemini/Grok) models from our platform. It all goes through Unity Gateway which has Smart Routing, Budgets, and Access Control. You can even use Omnigent with any harness, including CoCo. Most of our customers used this to reduce token spend ~30% last few months while token count went up. Genie lets you then track, control, manage that spend, all your financials, marketing, etc. Quick POC?
> cat ~/.claude/CLAUDE.md
<python>
Use uv for everything: uv run, uv add, uv build
Use pandas even once and I will demolish you
</python>
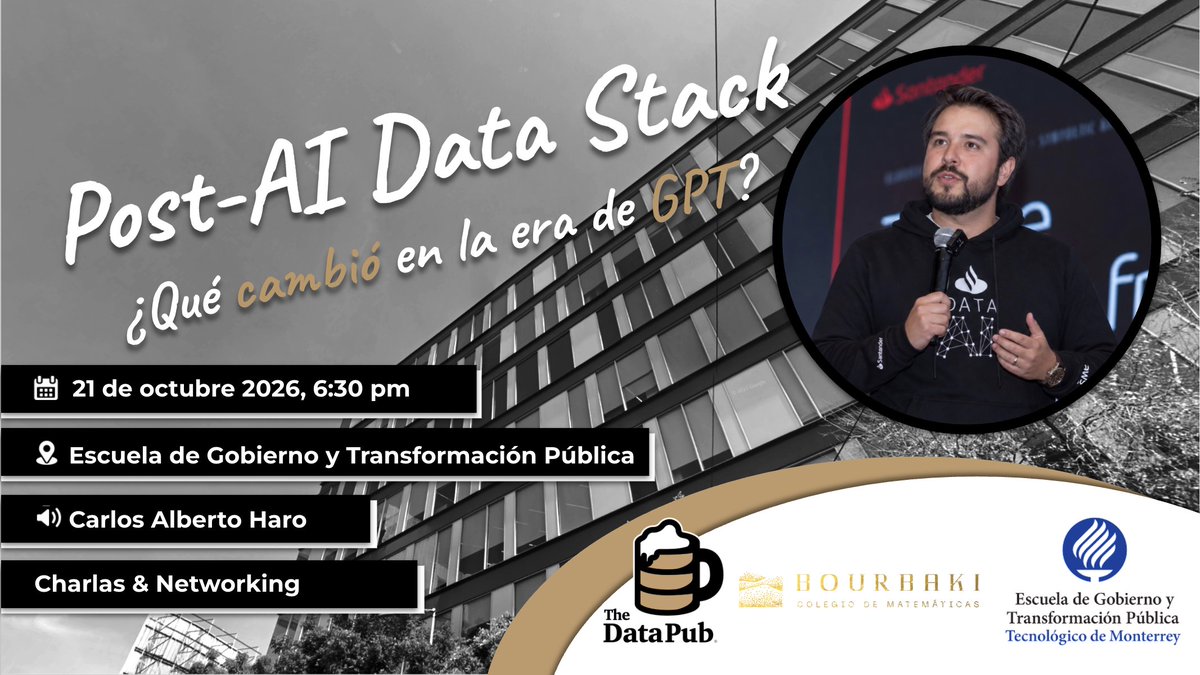
🍻 ¡Nuevo Meetup de The Data Pub!
Hace 3 años exploramos el Modern Data Stack. Hoy, con GPT y agentes de IA por todos lados, ¿qué cambió realmente?
🎤 @h1sort regresa con Post AI Data Stack.
📅 21 de octubre | 7 pm CDMX
📍 Presencial + streaming
🔗https://t.co/Xb7AHZmc3W