Our work is featured in Hugging Face Daily Papers!
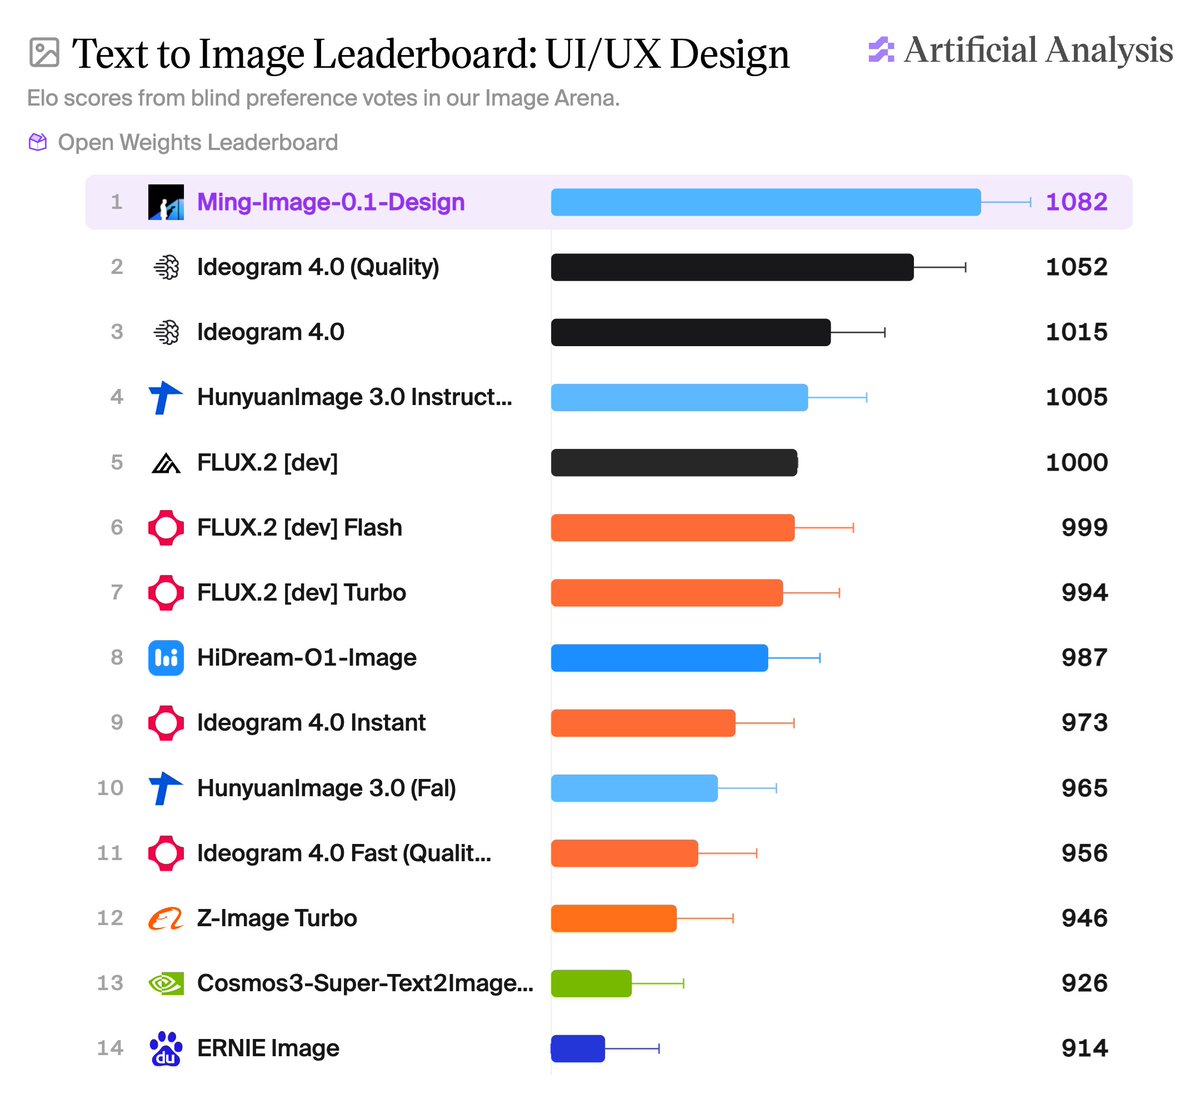
RULER: Instance-aware Rubric Rewards for SVG Generation. https://t.co/v39zdvwxZF
Huge credit to our student authors Hangyu Ran @zzranhangyu, Yuhao Zheng @xinlinzyh, and our collaborator Kevin Qinghong Lin @KevinQHLin, for their excellent work!
Building on our experience with large-scale post-training, I’ve been thinking about three practical challenges in pushing model capabilities further:
• How do we make open-ended tasks meaningfully verifiable?
• How do we align rewards with human taste and aesthetic judgment?
• How do we make feedback detailed and task-specific, yet scalable?
Our work takes a concrete step in this direction: RULER derives evaluation criteria from each user prompt, assesses the rendered SVG item by item, and turns those judgments into RL rewards.
Proud to share my first release with the Ling foundation model team: Ling-3.0-flash-VL!
Over the past few months, my teammates and I built the multimodal coding post-training pipeline, developing its agentic coding capabilities from the ground up. Our model can now write code, check the rendered output, and iterate to build great websites.
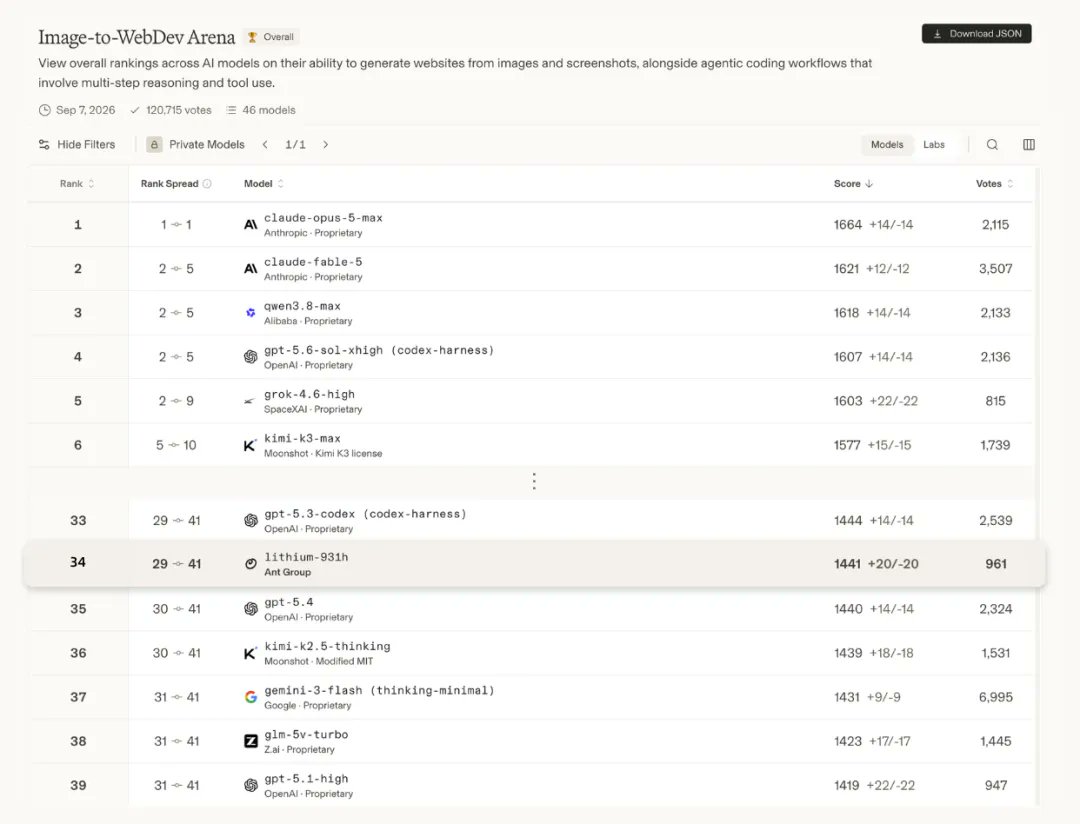
The results of coding with visual feedback exceeded my expectations: With 124B total parameters and only 5.5B active, Ling-3.0-flash-VL placed close behind Gemini 3 Pro and ahead of GPT-5.4 and Kimi-K2.5 in Image-to-WebDev Arena’s real-user evaluations. It also surpassed Opus 4.6 on Vision2Web.
A rewarding first milestone with the team—and plenty more to build.
We’ve open-sourced the weights, and the API is available on OpenRouter—free for two weeks! Try it out and let us know what you think!
https://t.co/GHgkI2oKwT
https://t.co/226zUejc6O
Today, we are releasing Ling-3.0-flash-VL, built on Ling-3.0-flash with visual understanding and visual agent capabilities. It performs well across visual perception, STEM reasoning, document intelligence, multimodal agent tasks, frontend coding, and medical report interpretation.
Got some time to play with OpenClaw. With Ming-flash-omni, the image and speech generation skills feels so much more consistent and alive. The best part? It's one model behind the scenes keeping all the context during multimodal gen. Try out the model in https://t.co/Qgj98iGEMo
@karpathy Also received my Mac mini right before Spring Festival, and spent the holiday running OpenClaw on it. Reminds me of my first chat with ChatGPT in 2022: stunning, unstable, buggy, but stunning. This added layer feels like a game-changer, even if we can't yet see where it'll go
Fantastic use case of the omni model in the context of an agentic environment! Many interesting interactions can happen with a single model that can see, paint, listen and speak. Thanks Guohao for your great demonstration!
You can now generate images from videos with Ming-flash-omni 2.0 by @AntLingAGI@TheInclusionAI in Eigent
So excited about how open source omni models will evolve in 2026
You can now generate images from videos with Ming-flash-omni 2.0 by @AntLingAGI@TheInclusionAI in Eigent
So excited about how open source omni models will evolve in 2026
One for all, and all for one 🧧
Introducing Ming-flash-omni-2.0: A specialist in every domain, unified as a capable generalist. A gift from Ling =)
- Unified Acoustic Synthesis: Speech, audio, and music combined for unbounded creativity;
- "Seeing" to "Knowing": Moving beyond input to true deep semantic understanding;
- Native Visual Fusion: Seamless generation, editing, and segmentation;
My mom is a nurse, vaccinating 300+ people every day in my hometown in China. She gave a jab to my childhood friend today, and that reminded her of my face. Tears dropped from her eye - she hasn't seen me for nearly two years. Time to move back home (and get my jab)!
@palolili23@maosbot@palolili23 holding the submission as long as necessary could be a useful strategy. Sorry @maosbot , this reply initialized a discussion diverging from the original thread, but it indeed reminds me of something both ludicrous and traumatic 😂😂😂