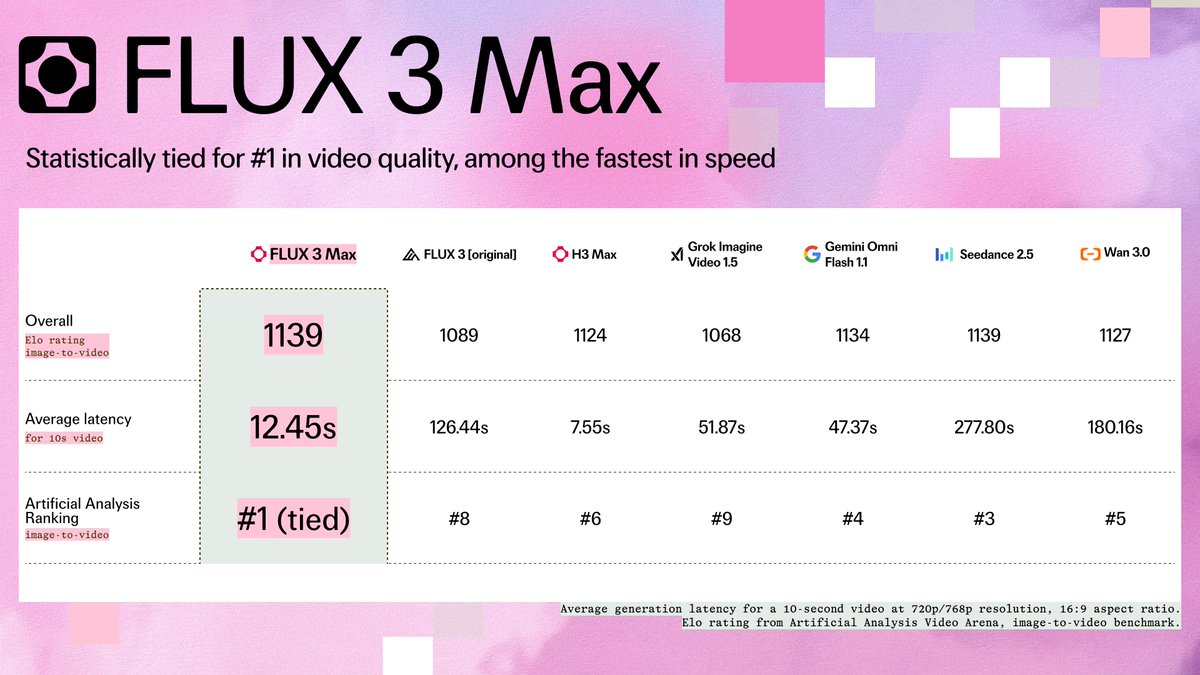
Introducing FLUX 3 Max, the latest post-trained video model from fal Research in partnership with @bfl_ai.
FLUX 3 Max is tied for #1 in image-to-video quality on independent third-party benchmarks, generating a 10-second, 720/768p video in ~12 seconds.
For the next three weeks, FLUX 3 Max is 75% off, making it the most affordable frontier video model at its quality level.
Introducing https://t.co/4xpxWRD3VV
A new platform for infinite, interactive AI livestreams. Pick a channel, prompt what happens next, and watch it generate in real time.
You aren't just watching the show. You're directing it.
Introducing H3 Max, new post-trained video model by fal Research.
H3 Max ranks #1 for overall quality, prompt understanding, and aesthetics against leading video models, on both first-party and third-party independent evaluations while generating a 5-second 720p video under 3 seconds.
H3 Max is 50% off for the next week, making it the highest quality, fastest and cheapest model for overall video generation tasks.
yesterday, @cloneofsimo and I released a tech report on the video pretraining research we worked on last year. we believe sharing our experience with the community building video models will be of great help!
https://t.co/9YZmEs6lXN
Today, we're thrilled to announce our $125M Series C funding round at a $1.5B valuation, led by Meritech Capital, marking our third successful raise in just 12 months!
fal’s Generative Media Cloud now powers tens of thousands of applications, supporting over two million developers and more than 300 enterprise customers. From initial prototypes to fully scaled production, we've become the essential infrastructure enabling some of the most innovative and creative work in the industry.
Over the past year alone, we've experienced extraordinary growth—averaging 40% month-over-month, consistently exceeding our own ambitious projections. Each month, hundreds of thousands of new developers and thousands of fresh applications join our platform, unlocking entirely new use cases previously thought impossible.
With this latest round of funding, we're significantly scaling our engineering, support, sales, and marketing teams to keep pace with the accelerating demand and enthusiasm from our community.
Our vision has always been clear: build a generative media platform that effortlessly creates dynamic, real-time content across video, audio, image, and 3D. Thanks to our incredible team, dedicated partners, and visionary customers, that's precisely what fal delivers today—empowering creativity at unprecedented scale.
@elipughresearch we ended up building our own dataloader: https://t.co/mZ5OKElzLo
it has a centralized server responsible for sample filtering/sharding/shuffling etc which may effect the total dataset size, and trainer nodes just fetch batches until they hit the stop signal from the server
torch dataset & dataloader assumes that total length of the dataset is fixed and deterministic. this approach is fair in general but apparently things get complicated when it comes to distributed data parallelizing, streaming shards, stuff like that.
10B parameter DiT trained on 80M images, all owned by @freepik . Model commercially usable, raw model without distillation, open sourced.
Proud to demonstrate first model-training project with our client @freepik: "F-Lite", from @FAL
Hunyuan Video LoRA Training Endpoint is now available on @fal! You can use 6-8 images and train a lora in 15 minutes!
Try it out here: https://t.co/0SOn65pim1
such a shame this issue is still open... I mean for distributed training everyone uses gpu, what's the point of making such methods if they aren't supported for nccl
https://t.co/PdX1Or1jpp