"Whoever owns the harness owns the flywheel" — that's the thesis.
Routing signals exist to be training labels, not cost knobs. Deployment = training start. One loop down; the recursive part starts at iteration two.
@hankaixyz Congrats on the release. The three-signal logging design (prediction vs policy vs served, kept separate) is the detail most teams will wish they'd copied a year ago. Wrote a full breakdown of the flywheel: https://t.co/5oK4d3K0Ab
NeoHorse-1: A step toward recursive self-improvement
Agentic post-training with a routing harness turns execution traces into training data, narrowing the gap between a 4B model and a 9B baseline by almost 6 points across 10 benchmarks.
Diffusion In Diffusion—a draft-then-refine framework that breaks the autoregressive bottleneck in block diffusion language models. It reduces generative perplexity from 25.7 to 21.9 on OpenWebText. #DiffusionModels#AI#MachineLearning
https://t.co/0BIZf8ewkB
Top AI research on @huggingface this week (November 24-30):
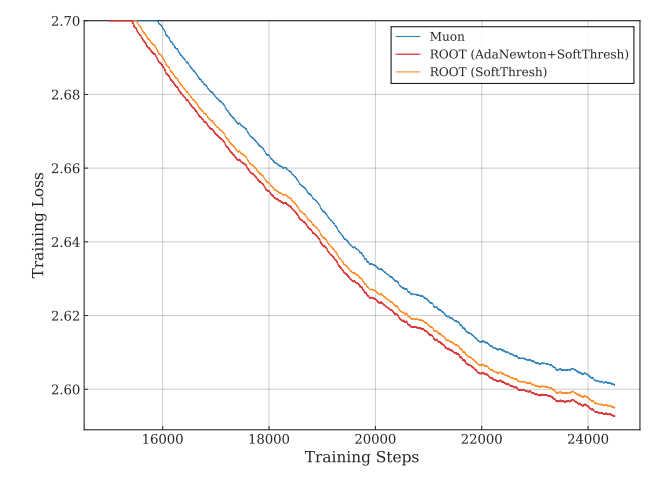
- ROOT: Robust Orthogonalized Optimizer for Neural Network Training by @HuaweiNoah
- General Agentic Memory Via Deep Research
- GigaEvo: An Open Source Optimization Framework Powered By LLMs And Evolution Algorithms by @AIRI_Institute
- SAM 3: Segment Anything with Concepts by @MetaAI
- Latent Collaboration in Multi-Agent Systems
- GeoVista: Web-Augmented Agentic Visual Reasoning for Geolocalization
- AutoEnv: Automated Environments for Measuring Cross-Environment Agent Learning
- OpenMMReasoner: Pushing the Frontiers for Multimodal Reasoning with an Open and General Recipe
- Unveiling Intrinsic Dimension of Texts: from Academic Abstract to Creative Story
- Multimodal Evaluation of Russian-language Architectures
Find them below:
Our team in Huawei just introduced ROOT, a new robust optimizer for LLM training. It improves stability and convergence by enhancing orthogonalization precision and resilience to outliers, showing better performance than Adam-based methods and Muon. Link: https://t.co/xRpCiPjv41
Our team in Huawei just introduced ROOT, a new robust optimizer for LLM training. It improves stability and convergence by enhancing orthogonalization precision and resilience to outliers, showing better performance than Adam-based methods and Muon. Link: https://t.co/xRpCiPjv41
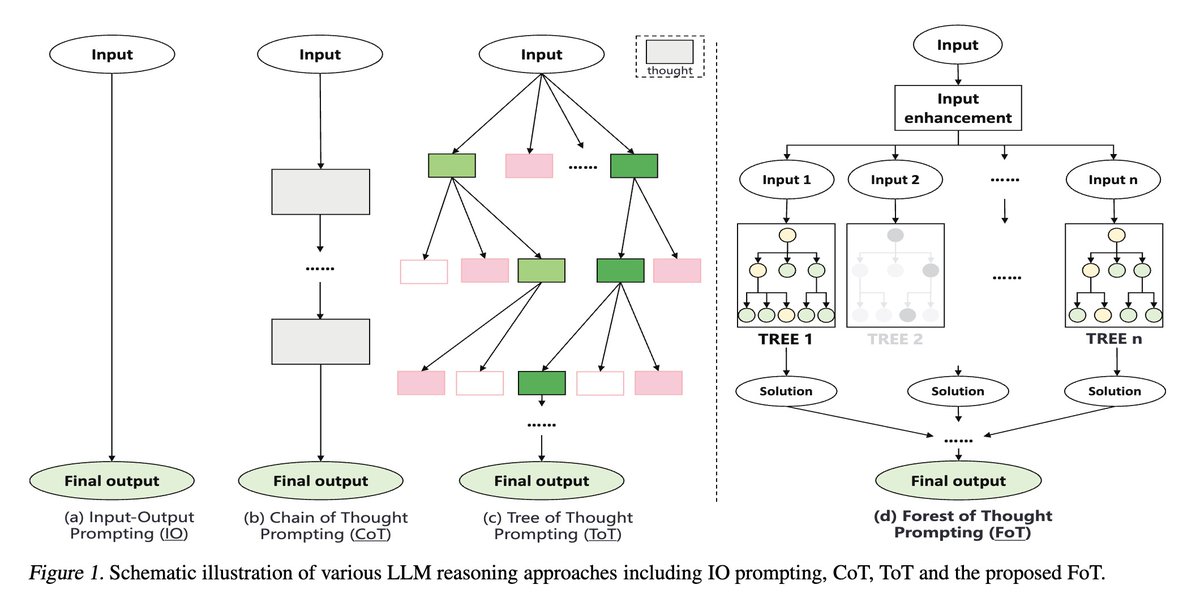
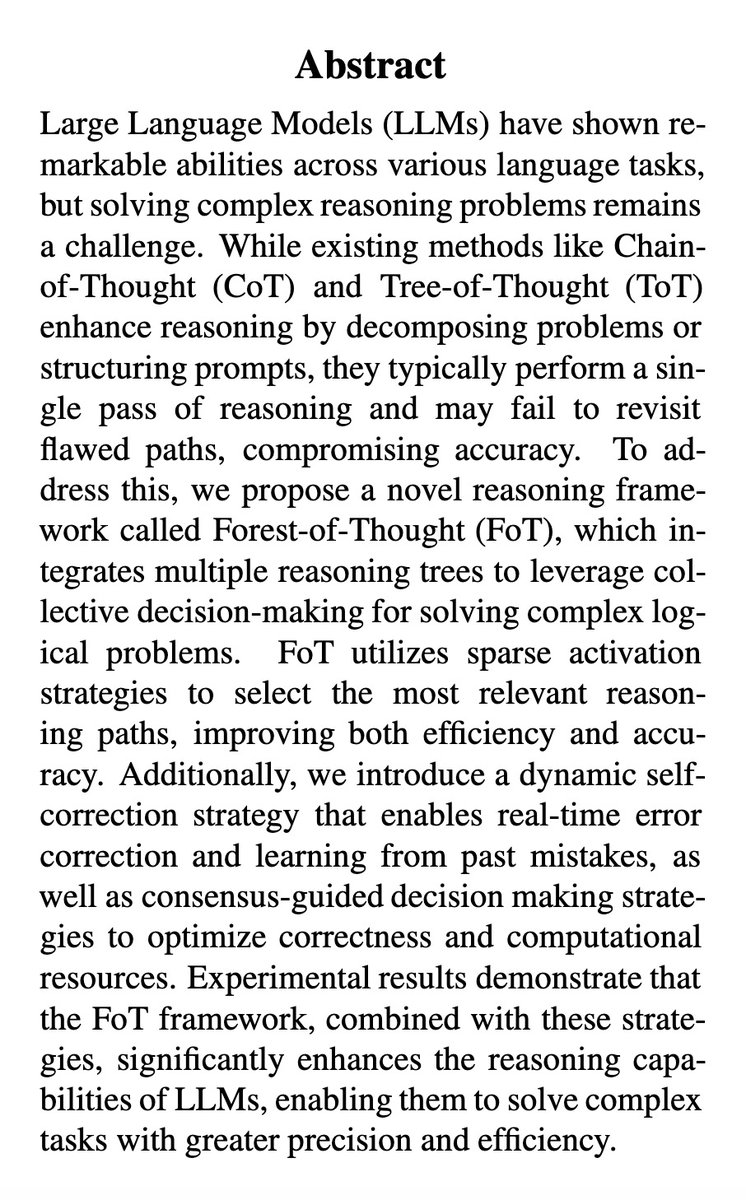
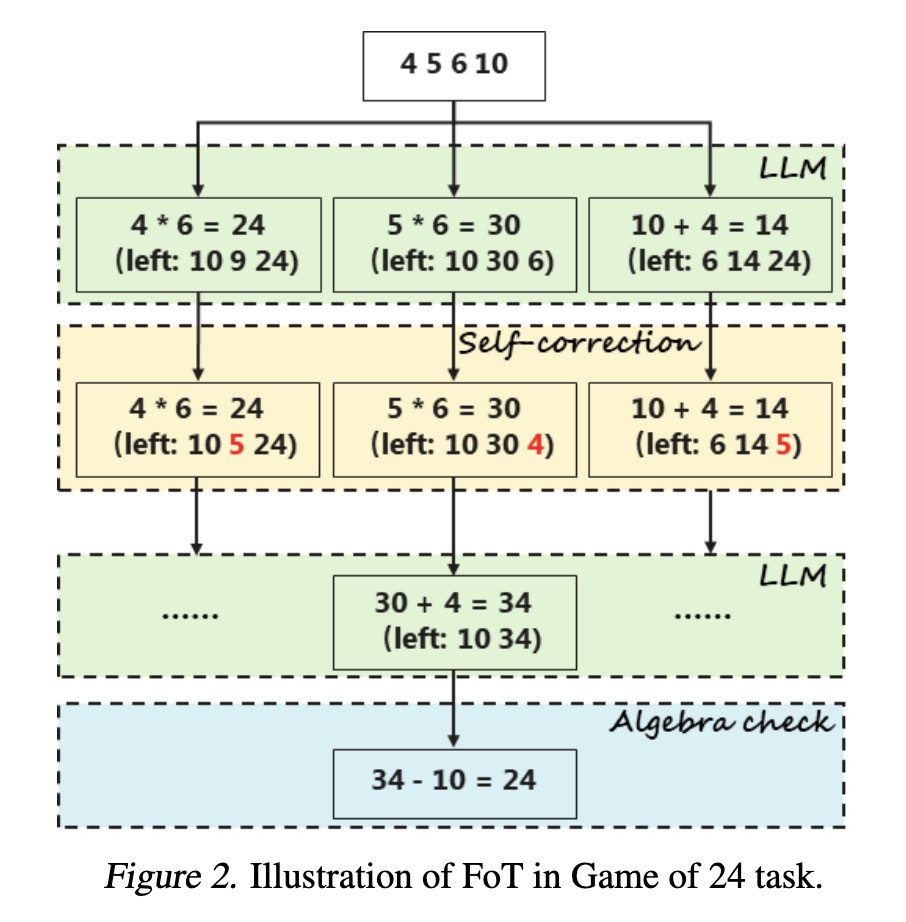
[CL] Forest-of-Thought: Scaling Test-Time Compute for Enhancing LLM Reasoning
Z Bi, K Han, C Liu, Y Tang... [Huawei Noah’s Ark Lab] (2024)
https://t.co/QzLFzAKOkF
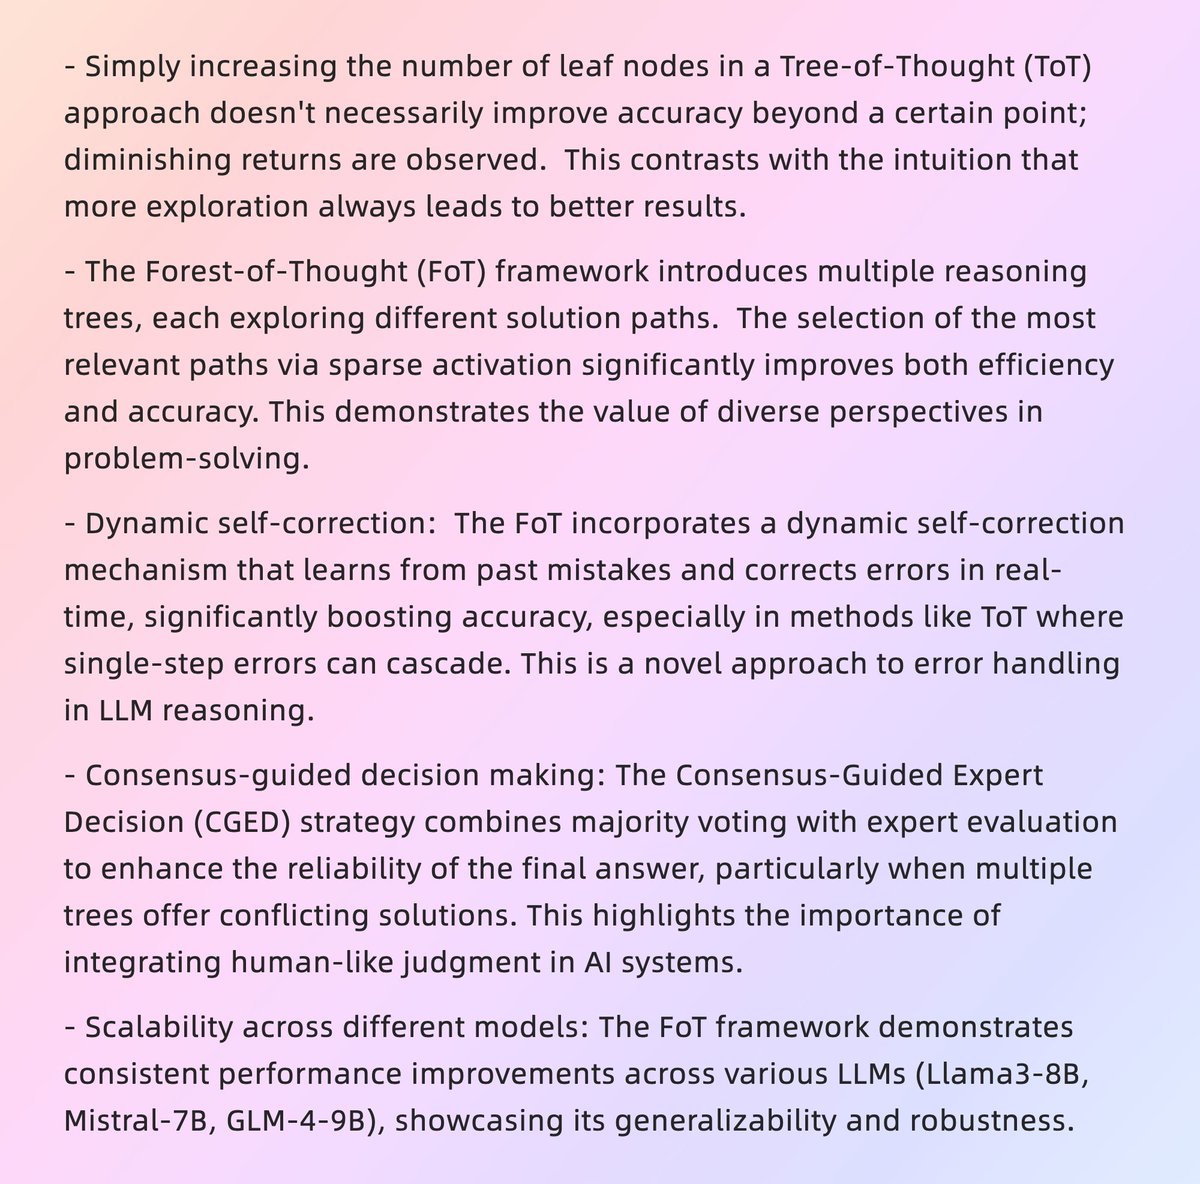
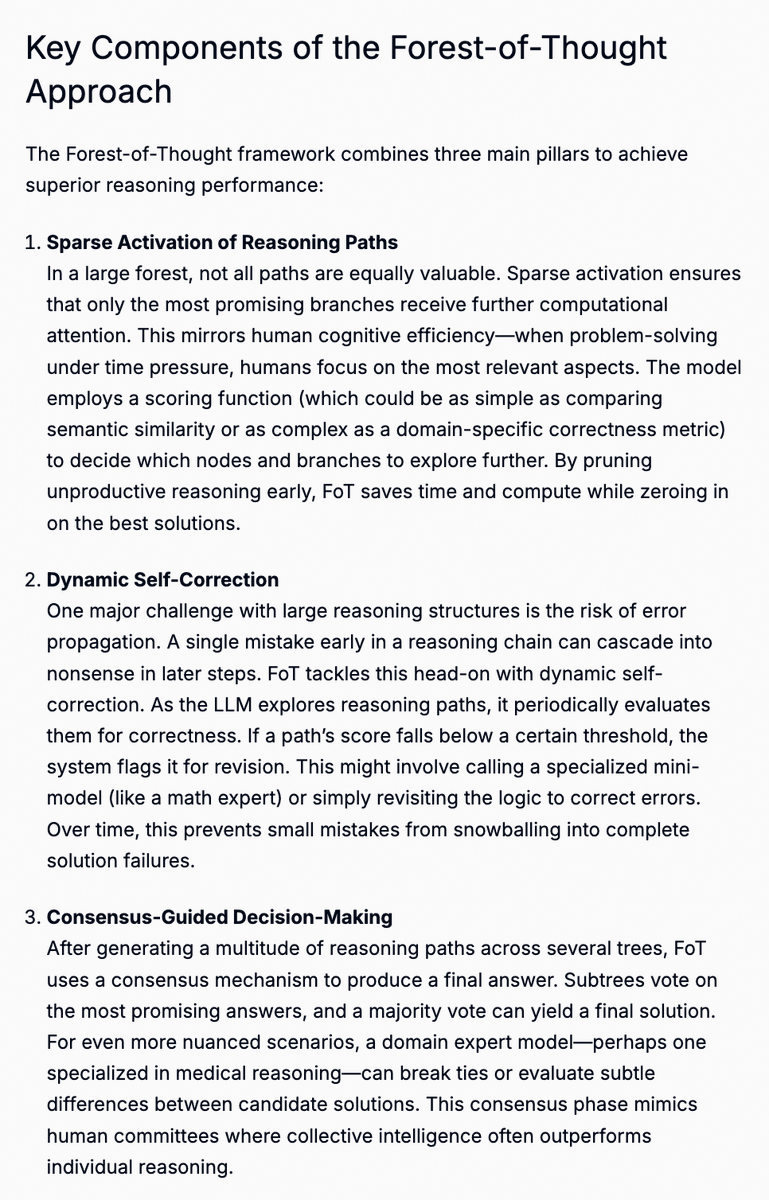
Researchers at Huawei Noah’s Ark Lab released Forest-of-Thought - an exciting new paradigm of post-training optimization to improve reasoning.
Brief introduction + breakdown of this recently released paper can be found on my blog (link in bio 👆)