Very excited to show this demo at CoRL!
Policy? World model? Value learner (temporal distance)? Why not treat them all as prompts, trained with just next token prediction?
Turns out it's a surprisingly strong pretraining objective! We trained one 8B model in-house from scratch (not VLA or WAM), built from an amazing series of works from friends at @NeuroAILab, led by @AtlasKazemian@KlemenKotar
And it works zero-shot with new objects and goal images! Come try it out in JW Marriott Lone Star (3rd floor)!
The results for the 2nd BEHAVIOR Challenge at CoRL 2026 are out! 🚀 In just one year, here's how far we've come together:
🏠 2× benchmark scale: 50 → 100 tasks, 3 → 7 scenes
👥 3× participation: 96 → 265 participants, 18 → 57 submissions
📈 4× full-task success: 12% → 48%
Congratulations to our winners!
🥇 The North Star, Huawei Noah EAI Team
🥈 IF1001, Intellifusion
🥉 Cyber, Xiaomi Robotics
Thank you to every team, from academia, industry, and independent labs worldwide, for making this year's challenge exceptional! 🙌
📝 Challenge description: https://t.co/4B13hRzrHy
(1/N)
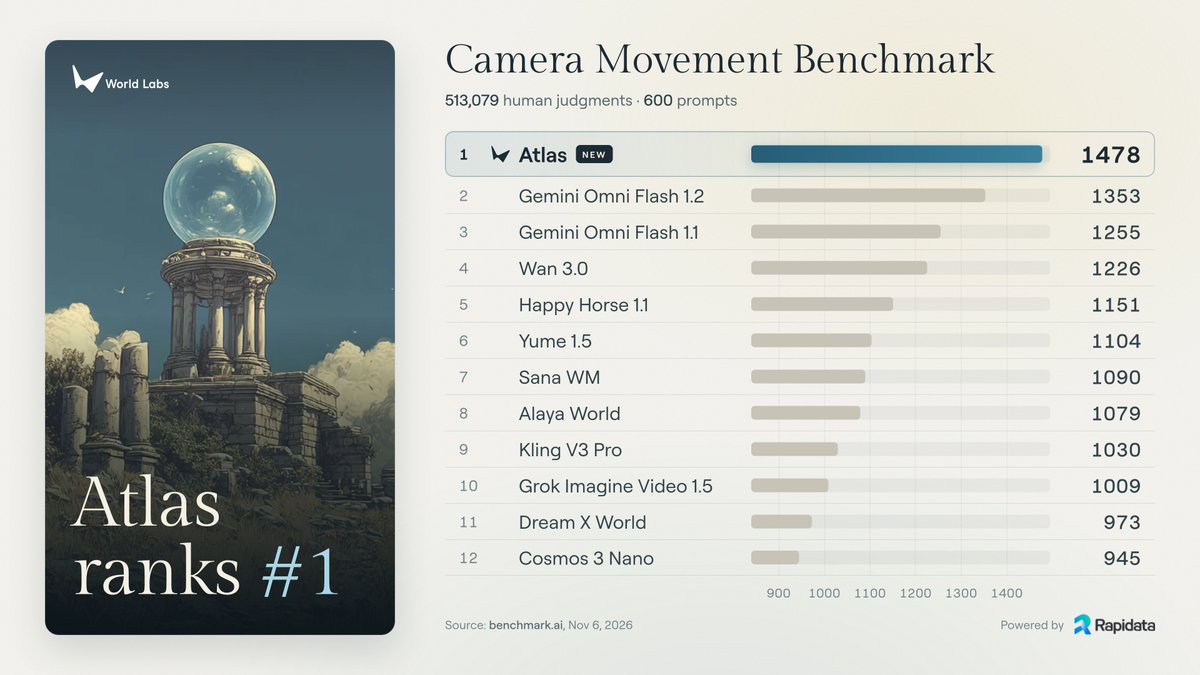
Atlas ranks #1 in @RapidataAI's camera-movement benchmark, which evaluates how well models follow camera instructions.
The evaluation compares 19 world and video models across 600 prompts, with 513K+ human judgments.
More on the results and methodology below.
What the hell?!! I can't believe how far we've come. Atlas is so good. Look at this fucking splat!! Check out behind the DJ table. Totally consistent novel view. No ghosting. This is entirely generated from a single image.
I'm gonna turn this into such a sick VR experience.
We've released a demo of real-time world generation powered by our new Atlas model!
This is a spiritual successor to our RTFM demo from last year. It's a vision for the future of interactive media might look like, with frames streamed directly from a powerful generative model
Two months ago, we introduced Atlas, an autoregressive world model with pixel-perfect camera control.
Today, we're releasing Frameboy, a demo allowing you to explore worlds in real-time with a highly optimized version of Atlas, streaming from cloud GPUs at up to 15 fps.
Long-horizon, whole-body robot policies still fail during deployment. How do we best close this last-mile gap? 🤖
🚨 Introducing I3L: Iterative Interactive Imitation Learning for Whole-Body Mobile Manipulation
Website: https://t.co/C58RmOS7Oq
Paper: https://t.co/DZXnXLF1bI
Today we’re sharing an experimental release of Spark Radix, a WebGPU-powered Gaussian splat renderer built on three.js.
Render and explore detailed 3D worlds directly in your browser.
Available today for developers to try and test 👇
AlphaGo and coding agents need reasoning, so does robotics, which is arguably orders of magnitude harder. But what is the right representation to perform reasoning?
Excited to introduce DreamCan, led by @GChongkai ! DreamCan performs sparse visual planning, reasoning over sparse visual frames that are both **reachable** by the robot and **makes progress** towards the task goal, and it can learn this capability from action-free suboptimal videos!
Check out Chongkai’s post for more details 🧵⬇️
Excited to share Halcyon, our latest research on multimodal pretraining!
Building strong text-to-image generative models is simpler than we think!
Blog: https://t.co/HOrwIJIHTf
Models: https://t.co/xBPJkEAOPU
Paper: https://t.co/8kROIz1c7L