

Top Tweets for #CoLM2026

Only two weeks late to the #COLM2026 party 🙃
Really cool to present our SimGym work at and meet others thinking about agent behavior, evaluation, and simulation from many different angles.
WAB: https://t.co/VzaMvsVzAS
Paper: https://t.co/zxKa7p67gX
#AgenticAI #AI


#EMNLP2026 vs. #COLM2026
1. EMNLP 的晚宴屈指可数,COLM 每天可以跑不止一场晚宴。
2. COLM 的 industry booth 数量远大于 EMNLP。
3. 在 EMNLP 会被渴死,但 COLM 不会。
4. EMNLP 离 Downtown 太远,而 COLM 就在 Downtown。
5. 湾区的中餐数量远大于Budapest。
#COLM >> #EMNLP Q.E.D

We just got back from #COLM2026 with four papers we loved on collaboration, human simulation, personalized rewards, and longer-horizon RL. Here’s the first. 🧵
(1/4) An agent’s autonomous ranking may not predict how well it works with people.
CollabSkill, by @EchoShao8899, @Diyi_Yang et al., explores that gap.
🤝 93 professionals worked with 5 agents across 386 sessions on occupational tasks. A Bayesian skill rating estimates the separate contributions of humans and agents.
🔄 Among the terminal agents tested, Claude Code outranks Codex in collaboration, reversing their order on the autonomous benchmarks compared in the paper. Claude Cowork ranks first overall, using the same Claude Sonnet 4.6 model as Claude Code through a different interface. These results apply to the versions tested.
👥 Teams with top-quartile collaborators beat the same agent running solo 74% of the time; bottom-quartile collaborators win 27%.
📄 https://t.co/1utNvnXBK0


‘Brain rot’ was named Oxford Word of the Year in 2024. We wondered: can LLMs get brain rot too? Turns out, yes. 🧠🫠 That question became our #COLM2026 paper, and this work has just been featured by Texas A&M University!
We found that training large language models (LLMs) on low-quality data can lead to “thought skipping,” causing models to bypass steps in their reasoning and produce incomplete or incorrect answers. The findings underscore an important principle in AI development: Improving the quality of training data is just as critical as improving the models themselves. Read the full story here 👉 https://t.co/GmeFGeXK9m
@TAMU @UTAustin @NTUsg @LifeAtPurdue @TAMUEngineering

Thoughts on computer use and personal assistants after using GPT-5.6 Sol and GPT-6 Astra to file conference reimbursements for #COLM2026 🧵
Disclaimer: This was not a controlled experiment.
TL;DR: They did it eventually, but it took more time than me doing it myself.

Switzerland's AI research is outstanding. Its AI funding is not.
After our FinePhrase paper won an outstanding paper award at #COLM2026, I got swarmed by American VCs throwing offers to fund me.
Even though I live and work in Switzerland, no Swiss VC seems even slightly interested.
So I compared every paper and award at the top 11 AI conferences since 2010 with investment data.
Per resident, Switzerland writes more top AI papers than any other European country, but raises about as much private AI money as the UK.
Israel writes half as many top AI papers per resident and raises 3.6x the AI money. The US writes even fewer and raises 4.3x.
It's not just Switzerland: a typical European seed round raises half as much as a US one, at less than half the valuation ($7M vs $17M).
No wonder many Swiss AI startups end up abroad: 34 of the 40 acquisitions I could find went to foreign buyers.
Politicians: keep funding the research despite the 2027 cuts, and help Swiss pension money reach Swiss venture funds.
Swiss companies: be the first customers, investors and buyers of Swiss AI startups, so founders can build here instead of moving to San Francisco.
Read the blog post to find out how a single ETH group skews the Swiss award record.
Blog post: https://t.co/bMZnzVTnIT
Code and data: https://t.co/wsKuGS4I0V


Can check our paper on the illusion of stochasticity in LLMs: https://t.co/EWzrohRtcs
Just present last week at #COLM2026


İnsanlara 1 ila 10 arasında bir sayı seçmelerini isterseniz genelde 7 seçerler. 1 seçmezler, 10 seçmezler. O sayılar yüksek sesle söylenmiştir.
Birden zihinlerinde saymaya başlarlar. Genelde ona yaklaşırken onları cevap vermeye zorlarsanız, mesela dokunursunuz, o zaman bir asal sayı olan 7'i seçerler. 10'a yakın bir sayı. Güzel bir sayı. İçleri rahat eder.
Bu sebepten insanlar iyi bir rastgele sayı üreteci değildir. Bir takım "meyilleri" vardır.
LLM'ler daha da kötü. Bu eğilimi (bias) alıp onu bir davranış kalıbı haline getiriyorlar.


@jiwonjeon_jen And a nice bonus today: our RLRT got a Best Paper nomination at the #COLM2026 Efficient Reasoning Workshop 🎉


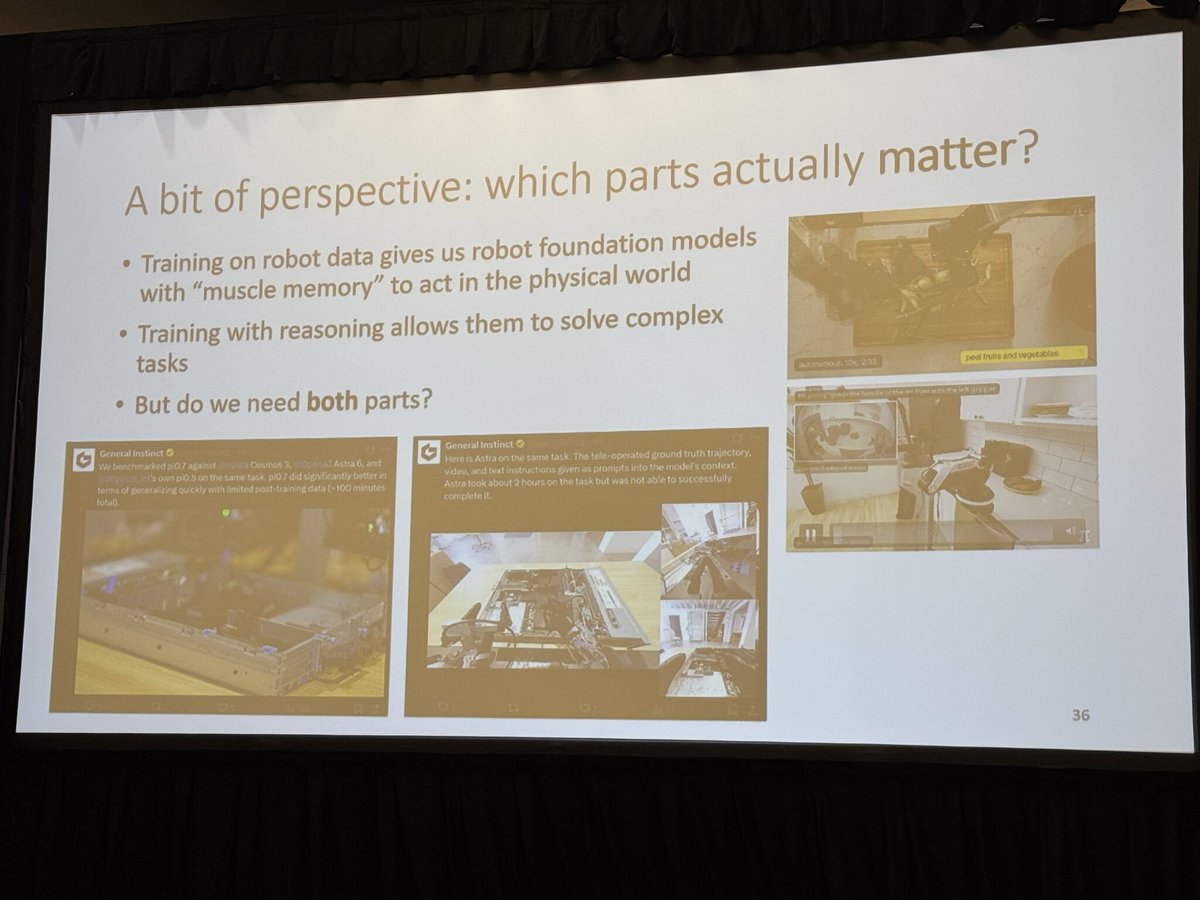
🤖 Sergey Levine’s #COLM2026 mic-drop: “ALL AI will be built on physical interaction.”
Sergey @svlevine spotlighted our @saturdayrobotic #18 speaker @Guanming717 & @gen_instinct.
6 takeaways: MEMORY, π0.7, SARL, What matters? Big picture. @COLM_conf https://t.co/IXvni5z1OC
🤖 “Someday, ALL AI will be built on physical interaction.”
That’s the bold prediction @svlevine Sergey Levine shared while closing the @COLM_conf Lifelong Agents Workshop. #COLM2026
@svlevine also highlighted our 😍 😍 Saturday Robotics 🤗 🤗 @saturdayrobotic #18 speaker @Guanming717 & @gen_instinct's work.
6 takeaways on future of robot learning 👇
1️⃣ MEMORY: What to remember is a decision 🧠
• Raw image history is slow and can create causal confusion.
• Diverse pretraining—not just extra loss terms—helps build better representations.
• Seconds of video → minutes of self-written notes → tasks lasting 15 minutes.
• Robots WILL fail. The goal: adapt within 1–2 attempts.
• Next frontier: memory that lasts weeks.
2️⃣ π0.7: Teach robots HOW, not just WHAT 🎯
• Prompts need procedural guidance: metadata tags + subgoal images.
• Naively merging datasets fails; context makes heterogeneous data useful.
• One ~5B generalist can rival specialized RL systems.
• Zero-shot UR5e shirt folding: 80% success vs. 80.6% for expert humans.
• Language + images become robot “thoughts”; grounding turns semantic generalization into physical action.
• Robots can remix skills like LLMs remix knowledge. Verbal coaching can teach new tasks.
3️⃣ RECAP / π*0.6: Practice changes everything
• Imitation learning is limited by its demonstrations.
• In control, errors compound. SFT alone isn't enough.
• Condition, don't filter: train on ALL data with advantage labels, steering the policy toward positive outcomes.
• Corrections fix mistakes; practice builds speed.
• Reported results: >2× throughput and ~2× fewer failures on hard tasks—from 13 hours of espresso-making practice.
• Policy gradients don't scale cleanly to large flow-matching VLAs.
4️⃣ SARL: RL on thoughts, not just actions
• Optimize prompts and reasoning—not only motor commands.
• Reported success: ~0% → up to 80% in 60–100 episodes.
• Make each exploration step build on a known skill.
• Decomposition without grounding fails; grounding without decomposition struggles with long-horizon tasks.
• Semantic-level RL + action-space RL = complementary capabilities.
• The VLA prior may ultimately be the ceiling.
5️⃣ What actually matters? Muscle memory + reasoning
💪 Robot data builds reliable sensorimotor skills.
🧠 Reasoning enables flexible planning and generalization.
BC alone is reactive. Reasoning alone can be brittle and slow.
The leap comes from combining both.
6️⃣ BIG PICTURE
We understand the world by interacting with it. An AI that must act in the physical world may develop a fundamentally different understanding from one that only observes.
Robot data is scarce today. Tomorrow, robots could generate vast amounts through practice and deployment.
They won't just learn from datasets. They'll keep learning from experience.
The long-term bet: every AI system may eventually be built on a foundation of physical interaction.
Is physical experience the missing ingredient for general intelligence?
#Robotics #EmbodiedAI #VLA #PhysicalAI #COLM2026 #SaturdayRobotics




Congrats to @_emliu @KaiserWhoLearns @millicent_li @wordscompute @lltjuatja @JentseHuang @gneubig on winning the #COLM2026 Outstanding Paper Award!
#SOTATV just interviewed @_emliu @COLM_conf on 𝐓𝐡𝐞 𝐈𝐦𝐩𝐥𝐢𝐜𝐢𝐭 𝐂𝐮𝐫𝐫𝐢𝐜𝐮𝐥𝐮𝐦 𝐇𝐲𝐩𝐨𝐭𝐡𝐞𝐬𝐢𝐬. language models pick up skills in the curriculum: copying, then word forms, logic, translation, arithmetic, composite tasks last.
Emmy also shared why she gives 2/10 for ICLR workshop paper written by AI, and her secrete sauce on getting 100K GPU hours compute.
More on 𝐒𝐎𝐓𝐀 𝐓𝐕 interview, coming soon.


Honoured to receive an outstanding paper award for our work! Couldn’t have done it without all my coauthors @KaiserWhoLearns @millicent_li @wordscompute @lltjuatja @JentseHuang and my advisor @gneubig 🫡

Attended the MOSS (Methods and Opportunities at Small Scale) Workshop at #COLM2026 last Friday, and one thought has stayed with me. The panel featured many prominent researchers, including Danqi, Tatsu, and Omar, who have made impactful contributions to AI, even though their work hasn't necessarily involved training trillion-parameter LLMs themselves.
It made me reflect on what truly matters during a PhD, especially if your eventual goal is to pursue a career in industry. Publications and experience with specific models certainly matter, but I think the deeper value lies in the ability to identify important problems, ask the right questions, develop insights, and design rigorous experiments. These skills are transferable across scales, methods, and even research fields. Ultimately, it's the recognition of these fundamental research abilities, rather than experience with any particular model or technique, that opens doors to truly great opportunities.
For a while, I was caught up in FOMO, constantly trying to keep up with every new trend in AI, worried that I might fall behind. Now I'm starting to realize that the goal shouldn't be to chase every trend, but to develop the ability to do meaningful research. With that in mind, I'm more motivated than ever to focus on my own research in post-training and alignment, going deeper rather than constantly chasing what's next. Of course, staying up to date with the field is important, but I want to be more intentional about what I choose to pursue.

Back from #COLM2026 after representing Amazon 🚀 One of my favorite conferences this year—great size for actually meeting people and having real research conversations.
Some of the post-training chatter 😅
“SFT causes catastrophic forgetting.”
“SFT is still the best. Just lower your LR and add a KL penalty.”
“OPSD / OPD? Doesn’t work well. Stay away—just do SFT.”
“Bro, just do RL.”
Different camps, strong opinions, and surprisingly convincing arguments from all sides 😂
If we crossed paths at COLM, reach out, would love to keep the conversations going 👋

A great week with the language modeling community at #COLM2026. Thanks to everyone who connected with our team. See you next year!

Last week during #COLM2026, #ReinforceLabs and @CentificGlobal hosted a fireside chat and a panel on agent safety in production — with leaders from @Google , @Meta , @glean , @Salesforce, and Across AI.
Our founder and CEO, @AnishDasSarma led the fireside chat that covered everything from model safety to agentic AI. The conversation moved through the biggest safety challenges facing the industry today, how to design evals that actually catch issues before production, and how teams stay current in a field that moves this fast.
There was no shortage of tough questions and good debate - exactly the kind of evening we wanted to host.
#AISafety #AIEvaluation #COLM2026 #ReinforceLabs #AIAgents


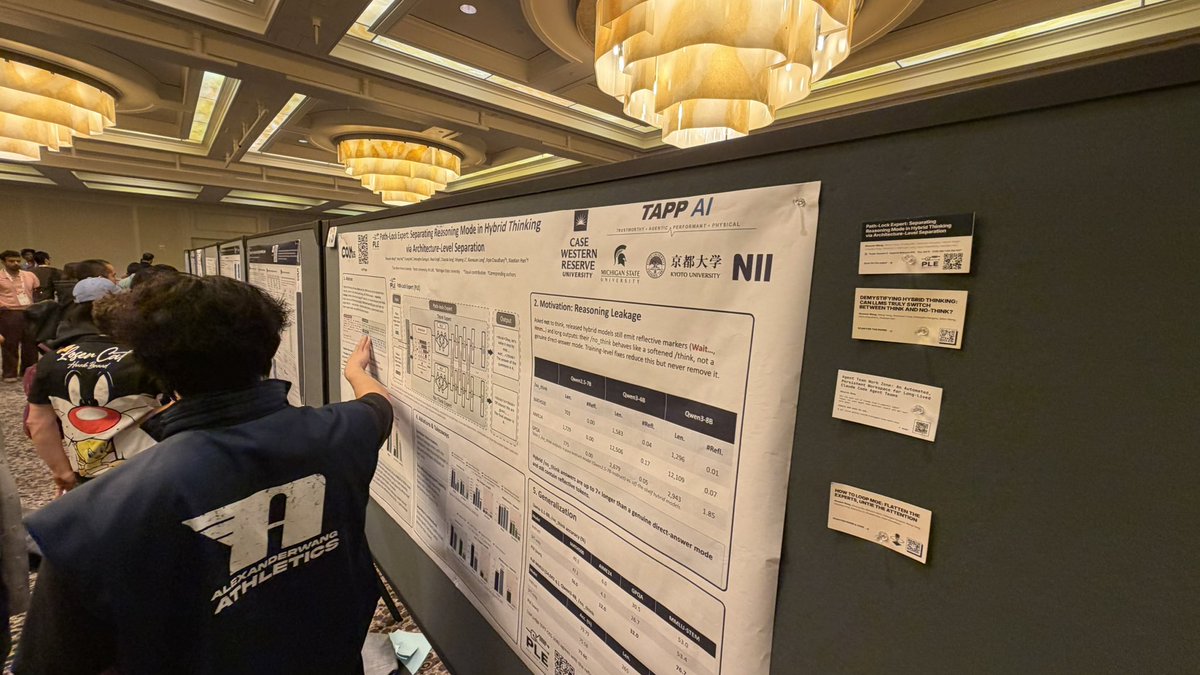
It was a pleasure presenting our work together at #COLM2026! Grateful for all the great discussions around our poster and for the chance to share our work with so many people.

#COLM2026 Day3
Finally wrapped up our poster presentation! Huge thanks to my co-authors for all their help. They even printed promotional cards for the project📇
Met so many new friends! Looking forward to more great conversations at #EMNLP2026 in Budapest in two weeks✈️


@COLM_conf 2026: 10 posters.
1️⃣ Message passing: 0.6B model solves 72% of 25×25 Sudoku
2️⃣ SuperCoder @anjiangw
3️⃣ HyperThink @Jacklu_me
4️⃣ ORCA
5️⃣ AHR
6️⃣ Meta-Harness @qizhengz_alex
7️⃣ Co-Director
8️⃣ SEAR
9️⃣ CollabSkill
🔟 Epistemic Diversity
#COLM2026
https://t.co/8WMwmKaUxh
My favorite ideas from @COLM_conf 2026: 10 papers that challenge how we think about AI progress. 👇
A 0.6B model solves 72% of 25×25 Sudoku.
A robot can succeed 10 times in practice—and still fail the real test.
The same AI model can rank differently depending on whether it uses a GUI or a terminal.
The common thread? Structure may matter as much as scale.
🔟 ideas worth knowing:
1️⃣ Message Passing (CMU, oral)
Give each reasoning thread a persistent state and let it message only its (k) neighbors. A fine-tuned 0.6B model reaches 72% on 25×25 Sudoku, versus 20% for GPT-5 Pro without tools. Different setups, not a fair head-to-head—but a striking result for structured reasoning.
2️⃣ SuperCoder
RL on measured runtime turns a 7B coder into an assembly superoptimizer: 95% of rewrites pass the available tests, with 1.46× speedup over gcc -O3. The catch? Tests + a stopwatch can reward removing stack canaries.
3️⃣ HyperThink
What if reasoning lived in weights, not a long token trace? A hypernetwork generates a tiny, question-specific bias update. VQ adds 6.5 points of Pass@5 on MATH-500.
4️⃣ ORCA
A 5.1K-parameter probe learns when to stop reasoning. Result: 47.5% fewer reasoning steps in-distribution. Distribution shift remains the catch.
5️⃣ AHR
One scalar per attention head beats LoRA by 6.7 points with just 10 labels. The edge disappears at around 100.
6️⃣ Meta-Harness
Let Claude Code optimize the harness itself—not just read agent traces. It beats ACE by 7.7 points using 4× less context. Summaries can hurt.
7️⃣ Co-Director
A bandit searches 36 creative configurations while keeping Veo 3.1 as the generator. Orchestration—not a bigger video model—drives a major benchmark improvement.
8️⃣ SEAR 🤖
Skill libraries can help one robot agent and hurt another. Ten practice wins ≠ generalization.
9️⃣ CollabSkill (Stanford, oral)
The interface changes the leaderboard: Claude Cowork can outperform Claude Code in human-agent collaboration, even when autonomous benchmarks tell a different story.
🔟 Epistemic Diversity
Ten models collectively cover only 2–24% of valid reference answers. Ask for a “well-known physicist,” and Llama 4 Scout picks Hawking 100/100 times.
💡 My takeaway: AI progress isn't only about adding parameters. It's also about how models communicate, where they reason, when they stop, what they remember—and how we evaluate them.
Which result surprised you most?
We discuss ideas like these every Saturday at @saturdayrobotic Saturday Robotics 🤖
👉 https://t.co/OQgHepr9q5
#COLM2026 #LLM #AIAgents #Robotics


@COLM_conf 2026: 10 posters.
1️⃣ Message passing: 0.6B model solves 72% of 25×25 Sudoku
2️⃣ SuperCoder @anjiangw
3️⃣ HyperThink @Jacklu_me
4️⃣ ORCA
5️⃣ AHR
6️⃣ Meta-Harness @qizhengz_alex
7️⃣ Co-Director
8️⃣ SEAR
9️⃣ CollabSkill
🔟 Epistemic Diversity
#COLM2026
https://t.co/8FNCR8wZlr
@COLM_conf 2026: 10 posters.
1️⃣ Message passing (Oral): 0.6B model solves 72% 25×25 Sudoku
2️⃣ SuperCoder @anjiangw
3️⃣ HyperThink @Jacklu_me
4️⃣ ORCA
5️⃣ AHR
6️⃣ Meta-Harness @qizhengz_alex
7️⃣ Co-Director
8️⃣ SEAR
9️⃣ CollabSkill
🔟 Epistemic Diversity
#COLM2026 https://t.co/vJ6qd3CZ2G
@COLM_conf 2026: 10 posters.
1️⃣ Message passing (Oral): 0.6B model solves 72% 25×25 Sudoku
2️⃣ SuperCoder @anjiangw
3️⃣ HyperThink @Jacklu_me
4️⃣ ORCA
5️⃣ AHR
6️⃣ Meta-Harness @qizhengz_alex
7️⃣ Co-Director
8️⃣ SEAR
9️⃣ CollabSkill
🔟 Epistemic Diversity
#COLM2026 https://t.co/vJ6qd3CZ2G
A great week with the language modeling community at #COLM2026. Thanks to everyone who connected with our team. See you next year!

1/ Spent a few days at #COLM2026. Biggest thing that stuck with me: the gap between what models know and what they say.
Last Seen Hashtags on Sotwe
Most Popular Users

Elon Musk 
@elonmusk
240.5M followers

Barack Obama
@barackobama
118.7M followers

Cristiano Ronaldo
@cristiano
114.4M followers

Donald J. Trump
@realdonaldtrump
111.8M followers

Narendra Modi
@narendramodi
107M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.2M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.4M followers

Kim Kardashian
@kimkardashian
70.8M followers

YouTube
@youtube
68.7M followers

Neymar Jr
@neymarjr
66.3M followers

Bill Gates
@billgates
65.2M followers

Selena Gomez
@selenagomez
63M followers

The Ellen Show
@theellenshow
62.1M followers

CNN
@cnn
61.7M followers

X
@x
60.6M followers