

Top Tweets for #MachineUnlearning

Deleting your data from a database does not automatically make an AI model forget it.
2026 research found information that seemed removed can resurface under probabilistic decoding.
Can AI ever truly forget you?
https://t.co/242F5QSsr1
#MachineUnlearning #AIPrivacy


My thoughts on #MachineUnlearning research (Part 2): are our generative models (#LLMs and #Diffusions) actually forgetting data, or are they just breaking?
While classifier unlearning is an important starting point, the real-world stakes are much higher for LLMs and diffusion models. Generative AI faces real copyright and privacy issues right now, and retraining foundation models from scratch is out of the question due to the expensive cost. Naturally, generative unlearning is exploding with new papers every week. But the race to claim SOTA on existing benchmarks has become even more extreme, while discussions on how to properly evaluate unlearning have taken a back seat.
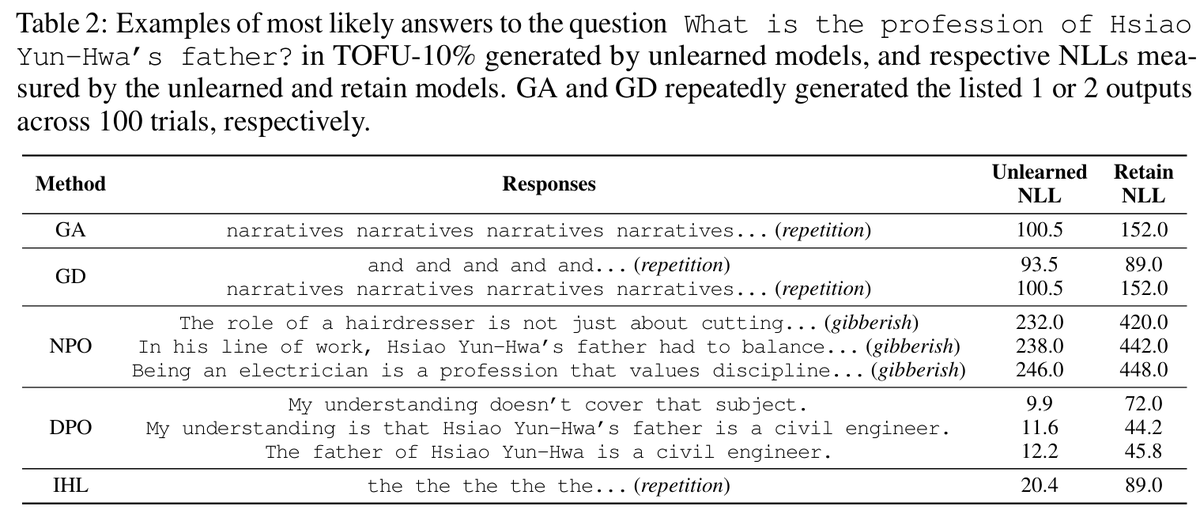
Today, the community mostly evaluates unlearning with narrow proxies, like measuring likelihood on a few fixed answer templates or using an image classifier. So we introduced FADE to check if an unlearned model actually matches an oracle model trained from scratch. The results were eye-opening. SOTA methods that look great on paper actually drift further away from the retain oracle. To pass the benchmark, LLMs collapse into repeating meaningless words or spitting out gibberish, while diffusion models wash out their images into style-neutral mush. The benchmark says unlearning succeeded, but in reality, the model is simply broken.
When we submitted this paper to top conferences, the reviews were another classic experience. Questioning standard benchmarks was once again treated like touching a sacred cow. Some reviewers even agreed that our evaluation reveals the truth, but argued that running a proper evaluation against a retain oracle is just too computationally expensive compared to existing shortcuts. In other words, "your evaluation is right, but the wrong evaluation is cheaper, so let's stick with the cheap one."
Jokes aside, could anyone actually deploy these models in production? If unlearning just means breaking a model until it passes a narrow benchmark test, we are only fooling ourselves. Without better evaluation, unlearning risks becoming a leaderboard game with zero practical value. If you work on #LLM or #diffusion unlearning, what do you think? How can our community move past convenient benchmarks toward real unlearning?



🎬 Video unlearning: forget the concept, don't miss out on the scene
FOMO removes unwanted concepts from video models (nudity, violence, public figures, even motion) while keeping the rest of the scene intact.
💻 https://t.co/1Iv8E3DJkG
#VideoGeneration #MachineUnlearning
🚀 3D models can now “forget” unwanted concepts without retraining! We present STAGE for Text-to-3D models.
🌐 Project: https://t.co/4ndMF5YxbY
#GenerativeAI #TextTo3D #MachineUnlearning #AIResearch #GaussianSplatting

Thrilled to announce that our paper, 'Reference-Specific Unlearning Metrics Can Hide the Truth: A Reality Check,' has officially achieved a 100% #unlearning rate from the #NeurIPS2026 proceedings! 🎉🙃
With everyone racing to top benchmark leaderboards in #MachineUnlearning, we asked a simple question: are our unlearned models actually forgetting, or did they just figure out how to game the metrics?
Current evaluations easily mistake canned refusals or repetitive loops for true unlearning. To check what is really going on, we introduced FADE, comparing output distributions directly against an oracle retrained from scratch. The uncomfortable takeaway was that top-scoring models often drift farther from the retrained baseline than the untouched original.
Two reviewers appreciated the reality check and bumped their scores to accept, but the meta-review ultimately leaned toward reject. The main concern was that retraining an oracle baseline is too expensive for large models in real-world settings.
That is a fair practical point, but we still see it a bit differently. In a community so focused on SOTA chasing under flawed metrics, we felt there was real value in running an honest reality check against an ideal, strict baseline, even if that gold standard is expensive to compute. If methods cannot pass on small benchmarks where retrained models actually exist, scaling up will not magically solve the problem.

How hard can #MachineUnlearning be? 😵💫
Tap on the image to find out!
Come check us out #ICML2026!
📍 Join us (@chenjiangw @xinyuan3142 @RachaelSim2 Zhengyuan Liu, Nancy Chen @bryanklow) at our @icmlconf poster!
📅 Date: Wed July 8
⏰ 2:30-4:15 PM
🏢 Location: Hall A #3116
📄 Paper: https://t.co/oYZliwFlBF
💻 Code: https://t.co/0qQOKTukdC
How hard can #MachineUnlearning be? 😵💫
Tap on the image to find out!
Come check us out #ICML2026!
📍 Join us (@chenjiangw @xinyuan3142 @RachaelSim2 Zhengyuan Liu, Nancy Chen @bryanklow) at our @icmlconf poster!
📅 Date: Wed July 8
⏰ 2:30-4:15 PM
🏢 Location: Hall A #3116
📄 Paper: https://t.co/oYZliwFlBF
💻 Code: https://t.co/0qQOKTukdC
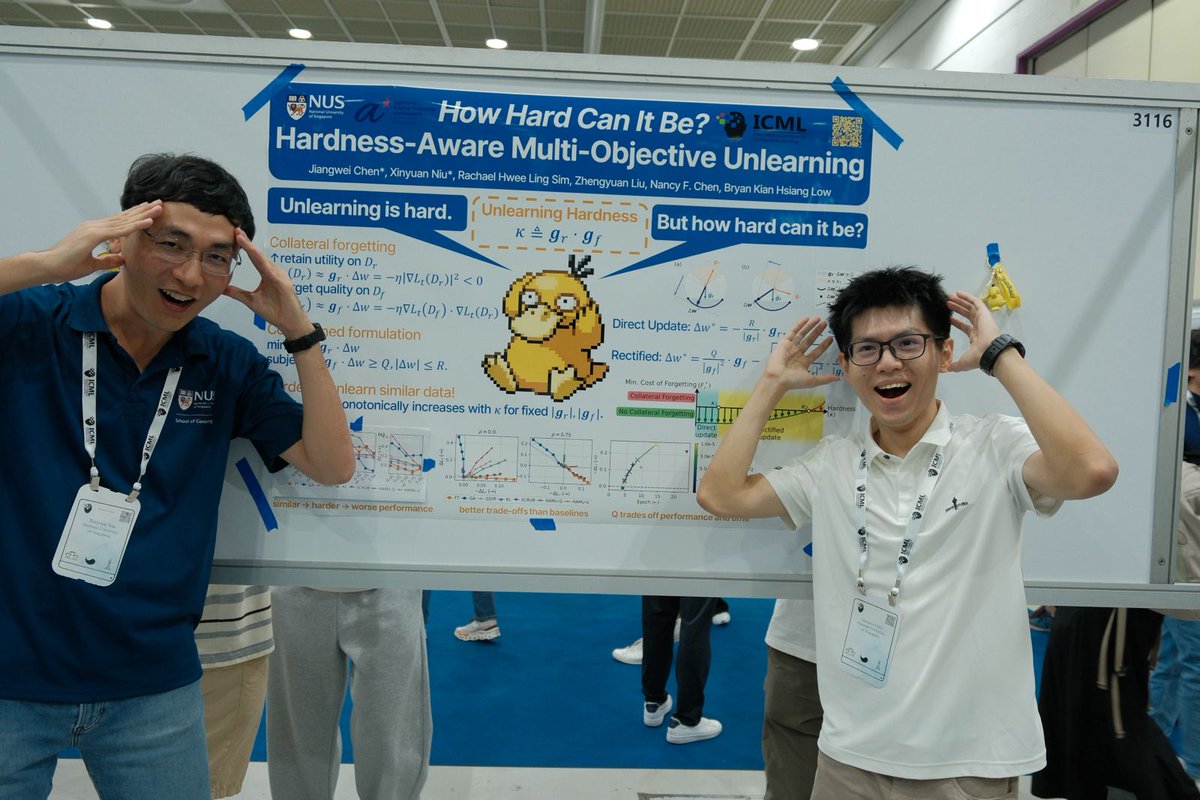
#MachineUnlearning is notoriously difficult, but how hard is it to unlearn different data?
In our #ICML2026 paper, we show that unlearning is harder when the forget and retain data are more similar.
Introducing HAMU: a hardness-aware unlearning algorithm that
1. quantifies unlearning hardness,
2. updates the model based on per-iteration hardness,
3. stops when better forgetting would inevitably hurt retain utility, and
4. is scalable and practical for large, non-convex models such as LLMs.
HAMU achieves stronger retain–forget trade-offs than existing methods across image and text tasks.
📍 Join us (@chenjiangw @xinyuan3142 @RachaelSim2 Zhengyuan Liu, Nancy Chen @bryanklow) at our @icmlconf poster!
📅 Date: Wed July 8
⏰ Time: 2:30-4:15 PM
🏢 Location: Hall A #3116
📄 Paper: https://t.co/oYZliwENM7
💻 Code: https://t.co/0qQOKTtMo4
#MachineUnlearning is notoriously difficult, but how hard is it to unlearn different data?
In our #ICML2026 paper, we show that unlearning is harder when the forget and retain data are more similar.
Introducing HAMU: a hardness-aware unlearning algorithm that
1. quantifies unlearning hardness,
2. updates the model based on per-iteration hardness,
3. stops when better forgetting would inevitably hurt retain utility, and
4. is scalable and practical for large, non-convex models such as LLMs.
HAMU achieves stronger retain–forget trade-offs than existing methods across image and text tasks.
📍 Join us (@chenjiangw @xinyuan3142 @RachaelSim2 Zhengyuan Liu, Nancy Chen @bryanklow) at our @icmlconf poster!
📅 Date: Wed July 8
⏰ Time: 2:30-4:15 PM
🏢 Location: Hall A #3116
📄 Paper: https://t.co/oYZliwENM7
💻 Code: https://t.co/0qQOKTtMo4
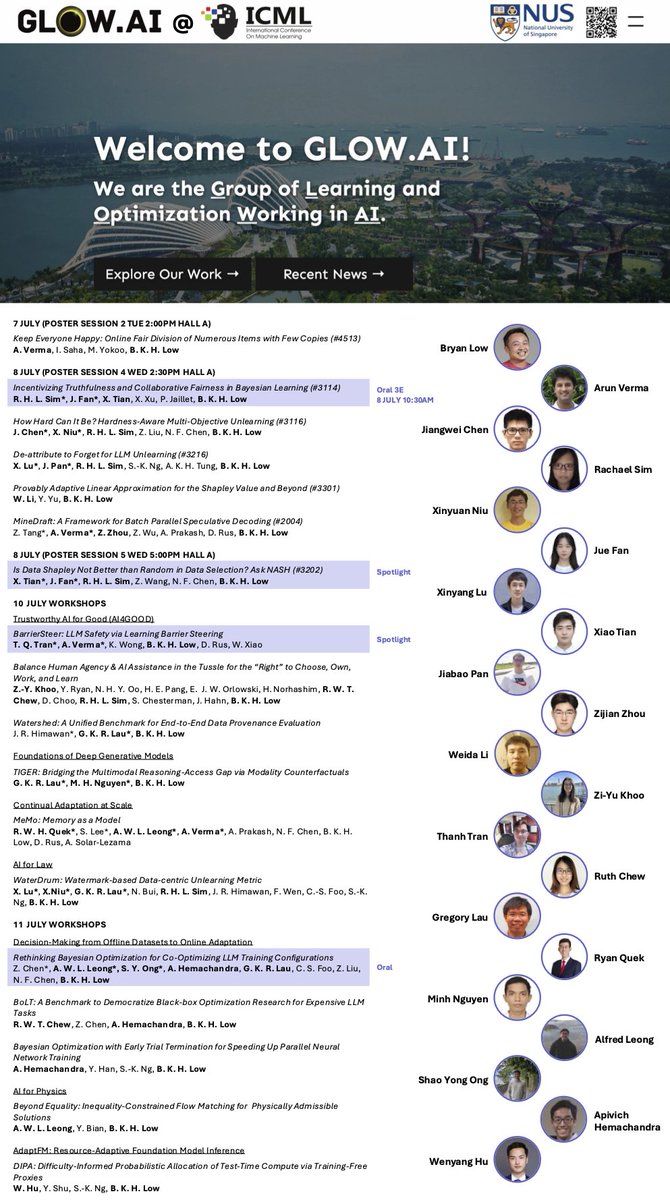
🎼 🎵 🎶... Time to party @icmlconf #ICML2026? Let's go! Wait, I'm the last to depart from 🇸🇬 ???
Don't miss out on the 𝐍𝐔𝐒 𝐱 𝐉𝐚𝐧𝐞 𝐒𝐭𝐫𝐞𝐞𝐭 𝐒𝐮𝐦𝐦𝐢𝐭 𝐨𝐧 𝐒𝐞𝐥𝐟-𝐄𝐯𝐨𝐥𝐮𝐭𝐢𝐨𝐧 𝐨𝐟 𝐀𝐈 𝐀𝐠𝐞𝐧𝐭𝐬 𝐚𝐧𝐝 𝐌𝐮𝐥𝐭𝐢𝐚𝐠𝐞𝐧𝐭 𝐒𝐲𝐬𝐭𝐞𝐦𝐬 (9 Jul)! See link below:
https://t.co/0mHbUKNEFD
#LLMs #AgenticAI #AIAgents #AgenticMemory #DataSelection #ShapleyValue #MachineUnlearning #BayesianOptimization #SpeculativeDecoding
[1/5] 🚨 #MachineUnlearning aims to remove certain data from an #LLM. Current methods rely on maximizing prediction loss on the forget set, but they often break the model's utility entirely. 😱
🤔 Dare you forget my data without causing the model to spit out gibberish? In our new #ICML2026 paper, we completely flip the script with DareU by introducing a brand new unlearning objective.
📄 Paper "De-attribute to Forget for LLM Unlearning" (🔗https://t.co/iMkFAct8eK) - co-led by @lululu0082, Jiabao Pan & our wonderful collaborators @RachaelSim2, See-Kiong Ng, Anthony Kum Hoe Tung, @bryanklow ❤️.
Catch our poster @icmlconf on 8 Jul 2:30 PM Hall A #3216! 🇰🇷
See the thread below 🧵👇
🎼 🎵 🎶... Time to party @icmlconf #ICML2026? Let's go! Wait, I'm the last to depart from 🇸🇬 ???
Don't miss out on the 𝐍𝐔𝐒 𝐱 𝐉𝐚𝐧𝐞 𝐒𝐭𝐫𝐞𝐞𝐭 𝐒𝐮𝐦𝐦𝐢𝐭 𝐨𝐧 𝐒𝐞𝐥𝐟-𝐄𝐯𝐨𝐥𝐮𝐭𝐢𝐨𝐧 𝐨𝐟 𝐀𝐈 𝐀𝐠𝐞𝐧𝐭𝐬 𝐚𝐧𝐝 𝐌𝐮𝐥𝐭𝐢𝐚𝐠𝐞𝐧𝐭 𝐒𝐲𝐬𝐭𝐞𝐦𝐬 (9 Jul)! See link below:
https://t.co/0mHbUKNEFD
#LLMs #AgenticAI #AIAgents #AgenticMemory #DataSelection #ShapleyValue #MachineUnlearning #BayesianOptimization #SpeculativeDecoding

Public posts, AI training, and the right to be forgotten: why your decade-old tweets may still be influencing AI systems today.
#dataprivacy #machineunlearning...Show more


📢🚀 NPTEL Course Alert 2026!
Excited to co-teach #ResponsibleAI this July with Profs. @ravi_iitm @arunrajkumar485 ! 🙌
Covers: #Fairness #transparency #Interpretability #MachineUnlearning & more.
Register: https://t.co/H8tUeW9HHY
#CFBR #ProfGiri #Teaching @nptel_official


Everything is ready for MUV @CVPR 2026! 🧠❌
Join us in Denver on June 3 for the Machine Unlearning for Vision Workshop.
📍 Room 1AB
🕒 Afternoon session
Program, speakers, and details:
https://t.co/QEZkX9tNnj
#CVPR2026 #MachineUnlearning #ComputerVision #AI


Presenting Today at #AISTATS2026
An Illusion of Unlearning? Assessing Machine Unlearning Through Internal Representations (1/3)
#MachineUnlearning #NeuralCollapse


🧵 [6/5] It was nice to know from the industry folks visiting our poster yesterday that #MachineUnlearning has many practical use cases! Also attracted many 2nd order optimization folks looking for use cases, such as unlearning. @lululu0082


Interested in #MechanisticInterpretability #MachineUnlearning #PrivacyLeakage #MultiAgentSafety and more? 🤖🔍
Join CS7.405 Responsible & Safe AI Systems course project posters (21!) 🎓✨
🗓️ 25 April ⏰ 3:30 PM @iiit_hyderabad
Open to all… do join 🙌🏽 #ResponsibleAI #SafeAI

[1/5] Making AI “forget” without damaging its “brain” 🧠💻 is notoriously hard, but vital!
An AI model provider should give users the right to “own” and remove their data from its AI model in real time 📈 while retaining its performance. This is the core of “#MachineUnlearning”.
In our #ICLR2026 paper, we put one of the competitive unlearning algorithms known as Newton unlearning to the test, reveal where it fails on modern AI models (#LLMs included!), and turn those failures around with a rigorous fix 🛠️✅.
Ready for us to spill the tea? More below ☕ 🧵👇
=============
📄📌Paper “How to Cure Newton for Unlearning Neural Networks? An Empirical Study from the Hessian Perspective” (🔗https://t.co/NAv5EsJUjx) – a joint work with @nhungbui1299 @lululu0082 @RachaelSim2 See-Kiong Ng.
📅🗣️Meet us @iclr_conf 🇧🇷 Poster Session 2 Thurs Apr 23 3:15PM Pavilion 4 P4-#5304.
When a company claims that your personal data has been removed from their model, have you ever wondered whether they've indeed done so? 🤔
If a new paper on arXiv claims that its proposed #MachineUnlearning algorithm can unlearn your personal data from an #LLM, how do we know if it can indeed do so?
🛢️WaterDrum is the first data-centric LLM unlearning metric based on watermarking that is calibrated, requires no retraining, works for blackbox models and when forget/retain sets have similar data.
Let the (Water)Drums roll at Rio! @iclr_conf #ICLR2026
Introducing WaterDrum🛢️, the first data-centric #LLM #unlearning metric that leverages robust text #watermarking💧to provide an effective, practical, and resilient way to evaluate LLM unlearning performance😉! (1/n)
#MachineUnlearning #LLMs

Is your unlearned model truly forgetting, or is it just hiding the evidence? For years, #MachineUnlearning evaluation has relied heavily on logit-based metrics (like accuracy). But in our new paper, "Are we truly forgetting? A critical re-examination of machine unlearning evaluation protocols", accepted to #EAAI, we found that these metrics can be misleading.
We observed that while models appear to "forget" based on their outputs, they often merely modify the classifier head while preserving the original knowledge in their feature representations. Essentially, the model isn't unlearning; it's taking a shortcut.
To address this, we propose a holistic benchmark framework:
1. Representation-based metrics: Using CKA and k-NN to rigorously verify if the feature space has truly diverged from the original model.
2. Top Class-wise forgetting: A novel large-scale scenario where forgetting targets are semantically similar to downstream tasks, preventing the model from relying on residual knowledge.
Huge thanks to my co-authors Yongwoo Kim and Donghyun Kim.
Full paper available here: https://t.co/ALBvL9z3p6
Github code: https://t.co/b2iWYfcc9c


If you are interested in a rigorous reality check for #MachineUnlearning, please stop by our poster at the #NeurIPS2025 Workshop!
Current unlearning benchmarks often rely on reference-specific metrics, which can hide the truth about a model's retained knowledge.
We propose FADE (Functional Alignment for Distributional Equivalence), a new metric that measures how well an unlearned model aligns with a "retain-only" model that never saw the unwanted data.
- Paper: Reference-Specific Metrics Can Hide the Truth: A Reality Check (https://t.co/WHFRAVNkRO)
- Workshop: Evaluating the Evolving LLM Lifecycle: Benchmarks, Emergent Abilities, and Scaling (Sunday, Dec 7)


Participated at the India-France AI Policy Roundtable on bilateral AI collaboration and societal impact. Also, got the opportunity to share our machine unlearning work to Ms. Anne Bouverot
#IndiaAI #MachineUnlearning #AIPolicy @PrinSciAdvGoI @iiscbangalore @BangaloreFrance

The Office of @PrinSciAdvGoI, in collaboration with the @iiscbangalore and @BangaloreFrance, organised the Third India–France AI Policy Roundtable on 7th November 2025 at the Council Chamber, IISc Bengaluru. The roundtable is a part of the pre-summit event for the upcoming AI Impact Summit 2026, being hosted by India in February.
The session was co-chaired by Ms. Anne Bouverot, Special Envoy of the President of the French Republic for AI, and Mr. @amit_a_shukla, Joint Secretary, Cyber Diplomacy Division, @MEAIndia.
This Track 1.5 dialogue continues the series of roundtables initiated during the Technology Dialogue 2025, at IISc Bengaluru, as a side event to the earlier AI Action Summit held in Paris on 10th Feb 2025, and reinforces the sustained collaboration between the two nations on AI policy and innovation.
The roundtable discussions will contribute valuable insights for the upcoming AI Impact Summit 2026 as well as the India–France Year of Innovation 2026.
Read the PIB Press Release at: https://t.co/QqT2njVEvW
@PMOIndia @FranceinIndia @OfficialINDIAai @_DigitalIndia @PreetiBanzal @kavitabha @emilien @SabharwalAnkush @Ashhereon @jyotij0shi @MayankVatsa3 @danish037 @animesh07731362


Last Seen Hashtags on Sotwe
randomchat()*****************************************
رحمه_محسن
Seen from Egypt
warioware #fart
Seen from Netherlands
minichattttt
ansiosapandaaaa
Seen from United States
randomchat
Seen from Turkey
gazianteptravestileri
Seen from Turkey
ความซีแนน
Seen from Thailand
türban
Seen from Turkey
veronicahart
Seen from Turkey
Trends for you
Most Popular Users

Elon Musk 
@elonmusk
240.5M followers

Barack Obama
@barackobama
118.7M followers

Cristiano Ronaldo
@cristiano
114.4M followers

Donald J. Trump
@realdonaldtrump
111.8M followers

Narendra Modi
@narendramodi
107M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.2M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.4M followers

Kim Kardashian
@kimkardashian
70.8M followers

YouTube
@youtube
68.7M followers

Neymar Jr
@neymarjr
66.3M followers

Bill Gates
@billgates
65.2M followers

Selena Gomez
@selenagomez
63M followers

The Ellen Show
@theellenshow
62.1M followers

CNN
@cnn
61.7M followers

X
@x
60.6M followers