Broke my dot in codex. I asked it for an immense amount of work and it actually just disappeared. Refreshing to have it feel a real human employee for a moment. Ha!
Didn't expect this 🤯
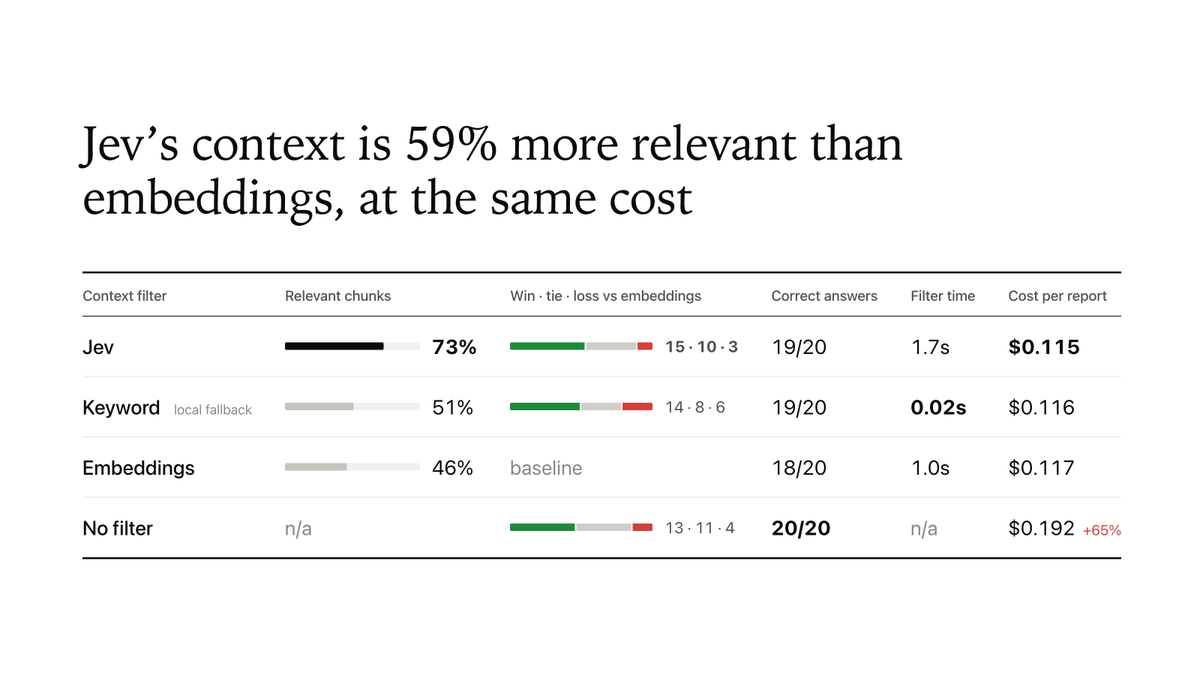
We replaced embeddings with Jev in GPT Researcher's RAG pipeline and tested both on 28 research tasks from SimpleQA and open ended research.
Jev beat embeddings on every quality measure we ran:
- 59% more relevant context (73% vs 46%)
- Reports preferred 15 to 3 in blind comparisons
- Same cost per report
GPT Researcher now runs on Jev by default, and no longer needs embeddings at all.
All you need is @LangChain + @tavilyai +Jev for the perfect RAG system.
Check out the repo here: https://t.co/kcvF5tPlWq
Research: https://t.co/QZIoRFnGQq
The @BostonCollege Investment Committee (an LP and my beloved alma mater) asked for a few thoughts on what's happening in AI. I recorded a test run yesterday morning and then shared it with my partners, who encouraged me to share it more broadly... so here you go!
This is not a sales pitch, it's just a reflection on what we're seeing. And it wasn't intended to be shared, so please pardon the rough edges.
https://t.co/AuZqHMSSxD
Introducing Synthetic Hospital: an open, fully synthetic longitudinal EHR benchmark with verifiable ground truth!
1,268 patients, 5,602 encounters, zero PHI. Physicians could not reliably distinguish its charts from real ones.
📄 https://t.co/kU6Rkqr2dA
💻 https://t.co/k3UH8vgQ6H
✍️ https://t.co/otOqD6LMee
@carmhuntress Recent trick: ask for imagegen to redesign something and generate 4 alternative options for you to choose from. Then have the impeccable design skill loop on your selection until it’s polished and integrated. Feels like a superpower
Just encountered the N +1 query problem. Quote from my codex today:
‘Your concern is justified. I measured over 2,300 database calls per page response, including 23 recalculations of the same source snapshot. That is avoidable application overhead.’