📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: https://t.co/AuiWxugjE6
- API: https://t.co/aS1QEkS8nu
- Token Plan: https://t.co/YRvcGdB9Bv
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
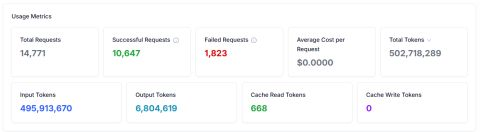
Boys I would recommend running your local LLM traffic through a gateway. A nice way to get visibility into exactly how much you are saving by running local.
My setup:
> LLM server: RTX PRO 6000
> Gateway: Dell optiplex 5070
> Client: M4 macbook pro
my hot consciousness take is that humans also think in neuralese, qualia are vectors, continuity of consciousness is a form of KV caching, and subjectivity is a product of the residual stream.
That is at roughly 100% saturation for ~5hr/day. So the ceiling is much higher with scheduling jobs to be during non-peak times.
I also am able to run/store my own RAG pipelines and gateway/observability.
My work rents compute from me for an additional $100/mo.
It is also high signal for employers.
@nickgraynews I’ve processed over 450M tokens on my single RTX pro 6000 in the last 7 days on qwen3.8-27b (Opus4.7 level model).
Thats ~$100 ($5000/yr) if I were to use an api with the same model ($0.50 in @ 70% cache hit rate/$3.00 out) — on a rig that has appreciated.
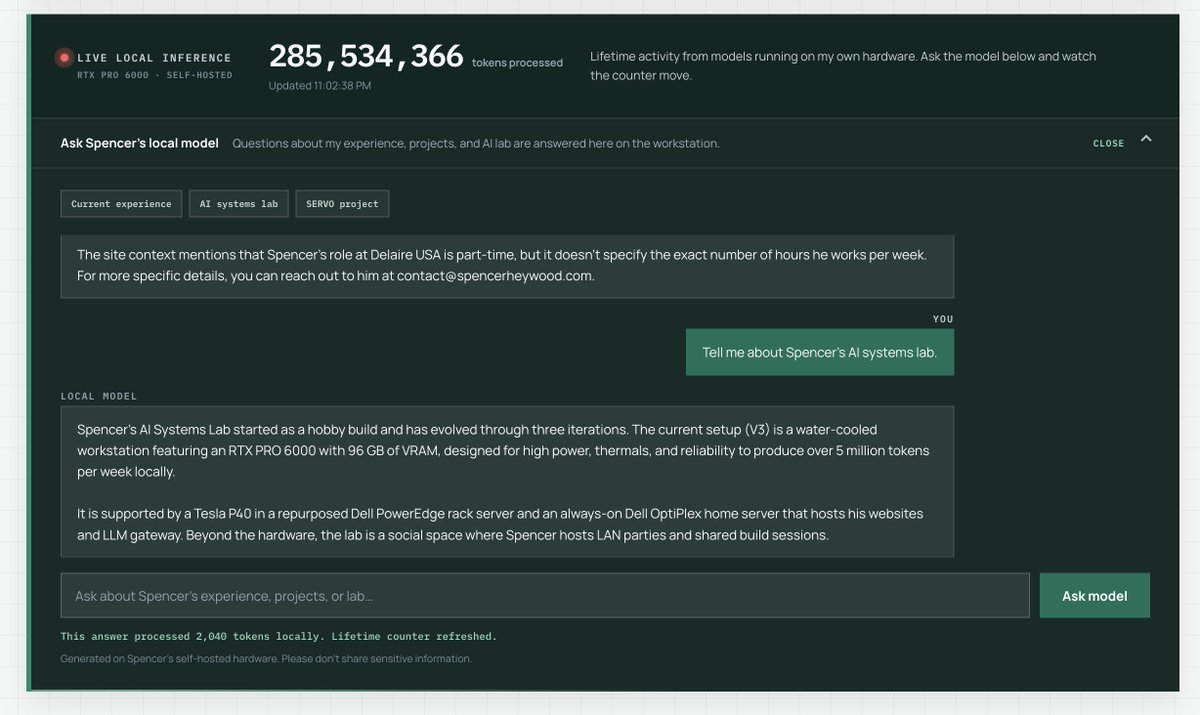
I updated my personal site with an AI chat powered by my home lab—285,534,366 tokens processed so far and counting.
Ask it about my experience, projects, or hardware, and watch the live token counter move as it generates a response.
Try it for yourself:
https://t.co/yPCzNxpujq