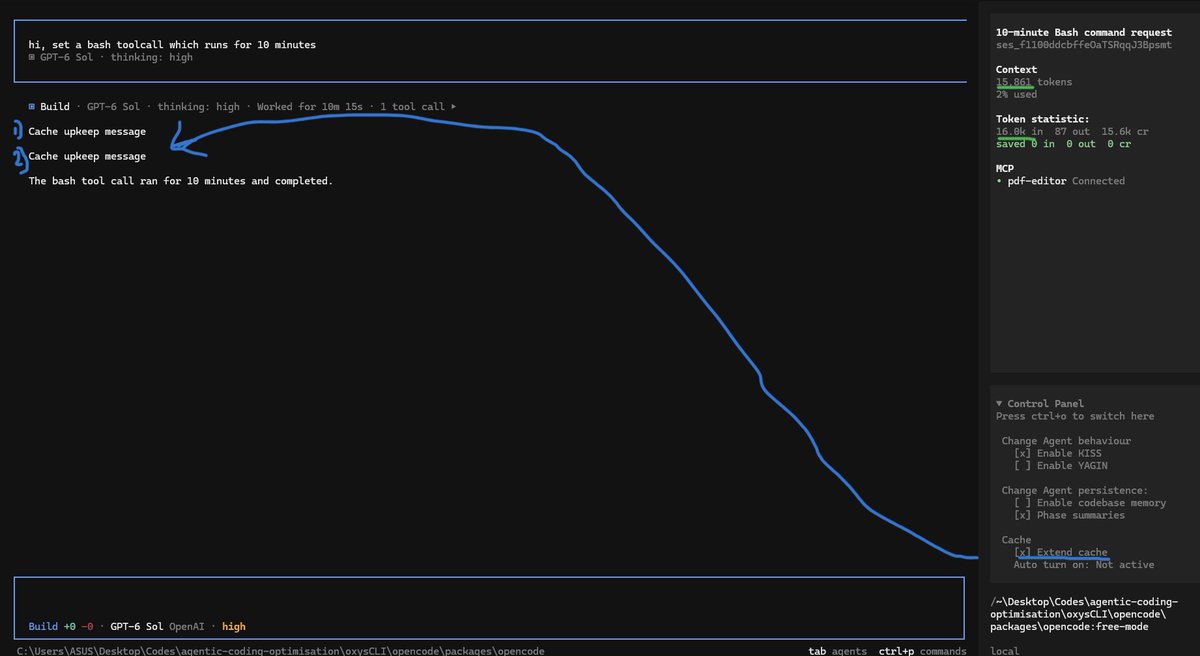
New features on https://t.co/mZyOxc0T4B because cache is now 50% cheaper for Sol.
1) Cache extender, while agent waits for a tool result/your response, it sends dummy messages to keep cache warm just before cache is about to expire.
2) Removed cache breaking compressions for sol, because the gains now from compression are almost as good as the discounted cache itself
Do you think the cache extender is a useful feature?
(@OpenAI) Give a man a dollar every day for a hundred days, and on the 101st day give him nothing - he’ll curse you.
(@claudeai) Beat a man every day for a hundred days, and on the 101st day don’t beat him - he’ll thank you.
@vincenzo_naked This will pivot in a while. Spending more tokens isn't proportional to productivity.
That's why I'm building my harness https://t.co/3LXHFA69cx - it cuts costs by performing micro optimisations on your context and adds up to saving about 41%.
Eventually people will realize.
Since people are pissed off that openai reduced usage by half- use your subscription on https://t.co/3LXHFA69cx - it'll (almost) double the work you get done, so 1/2*2= no change!
@sama hope this reduces the backlash lol
@mehulmpt 95% cache discount means your costs per task is cut by 50%
half you cost per run (on an average) is cache read- now its reduced to almost nothing
95% CACHE DISCOUNT!???
I need to rewrite my harness ASAP
Experiments show that almost half of costs are from cache read- this essentially doubles your usage!
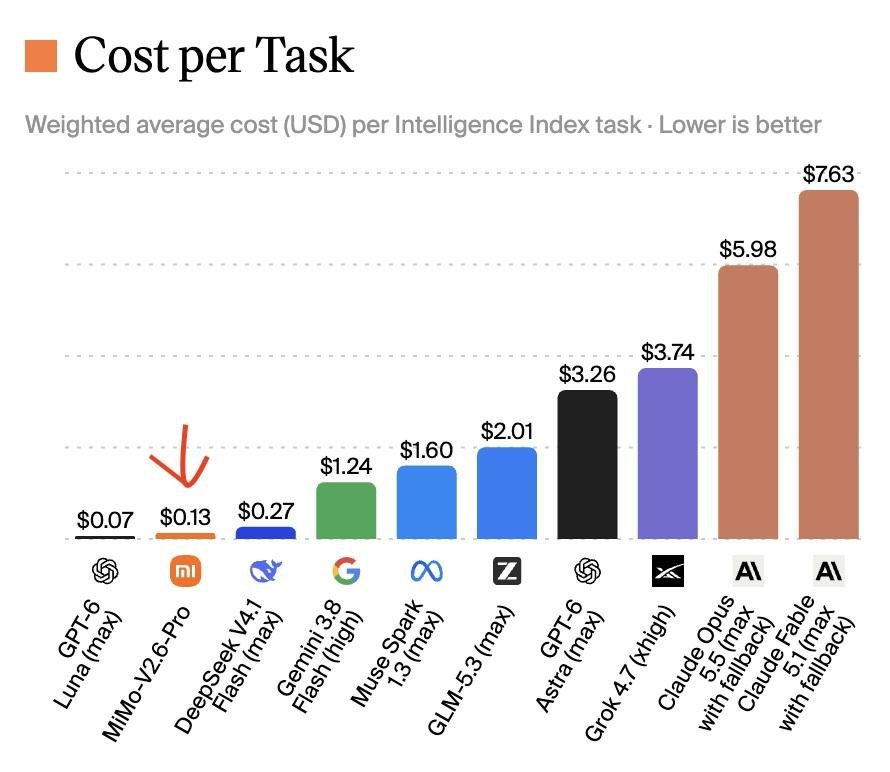
Introducing 6.1 Sol, near Astra intelligence at one fifth of the price of Astra and 95% cache read discount. It is an absolute workhorse.
Combined with ultrafast for 8X speeded available today for Astra and coming soon for 6.1 Sol.
@thsottiaux Are people seriously ignoring 95% cache discounts?
Bro literally half your costs are form cache reads on average. A 95% discount essentially doubles your usage!
Decisions API, for lightning fast constrained decision making powered by Luna. Supports visual inputs, and tuned to be able to make decisions in less than a few hundreds of milliseconds end to end.
@andriyviy I tried it around 6pm IST- translates to 4am US i think, I got a great TOPS(didn't see the actual number but above 150) latency was there tho, around 3 seconds