If you think AI will lead to human extinction by 2030, I will take that bet. If we are still alive by Dec 31, 2030, you pay me 1M USD. If not, I will pay you 10M USD.
@TheStalwart Not that related I guess? You can have one without the other.
Loosely,
Overfitting: model can’t solve new problems it hasn’t seen before
Rw hacking: the model optimized an objective function that was different from the one you meant
Both still can and do happen separately
To understand whether we're making genuine progress on reasoning, we entered our AI models in five international STEM Olympiad competitions this year.
The results:
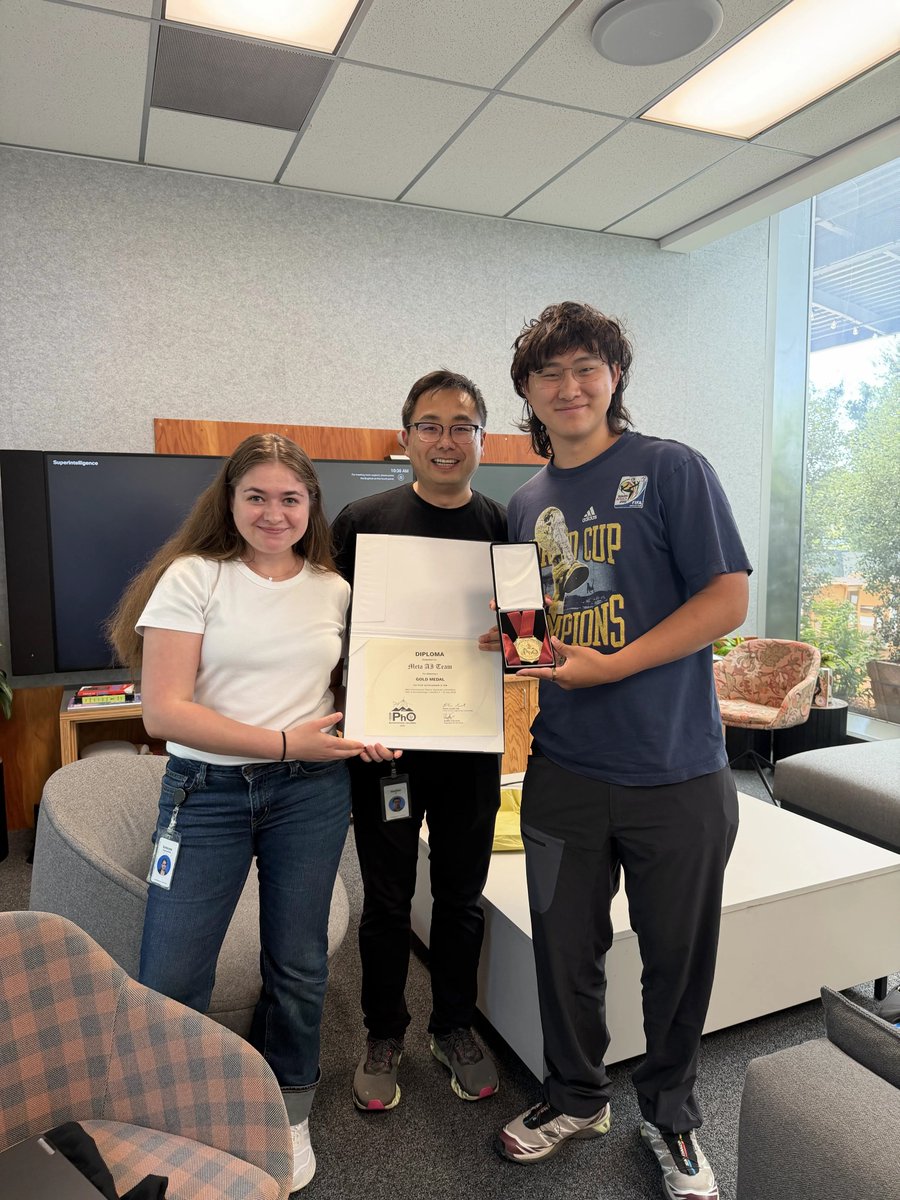
🏅 Asian Physics Olympiad (APhO): Perfect score on the theory exam — gold medal
🏅 International Physics Olympiad (IPhO): Perfect score on the theory exam — gold medal
🥇 International Mathematical Olympiad (IMO): Gold medal, top 4% of human participants
🥇 International Chemistry Olympiad (IChO): Gold-medal level performance
🥇 Romanian Masters of Mathematics (RMM): Gold-medal level performance
Three of these (APhO, IPhO, IMO) were live competitions and our solutions were submitted under real competition conditions and graded by the official judges using the same marking criteria applied to student contestants.
A few things about the approach:
• Models were internally trained versions from the Muse Spark family
• Zero tool use: no search, no code interpreter, no calculator
• Multi-agent orchestration with parallel reasoning
We are excited about where this reasoning capability goes next; frontier research level across scientific domains and personal superintelligence.
Super grateful to the organizing committees of APhO, IPhO, and IMO for supporting our live participation. We have deep respect for the contestants and organizers behind these competitions. 🙏
And proud of the MSL team that pulled this together!
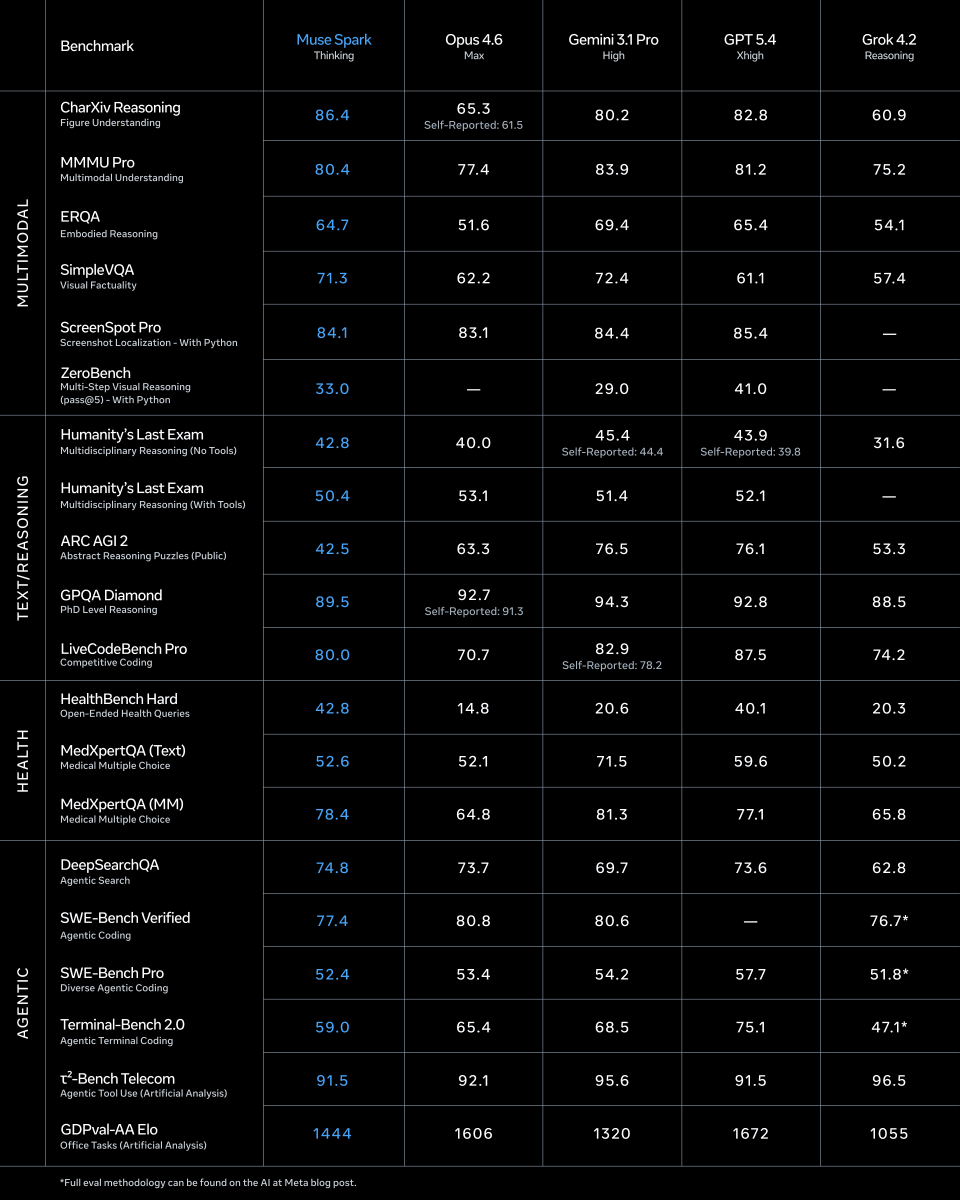
Congrats to @AIatMeta on the release of Muse Spark! Jumping from Llama 4 Maverick at 0 to 11.3 on CritPt is a huge leap. Given that CritPt consists of original, research-level physics problems designed by expert physicists, this is seriously impressive!
1/ today we're releasing muse spark, the first model from MSL. nine months ago we rebuilt our ai stack from scratch. new infrastructure, new architecture, new data pipelines. muse spark is the result of that work, and now it powers meta ai. 🧵
@DimitrisPapail@TaliaRinger How much does home roasting improve final-cup-enjoyment (eg vs the satisfaction from vertical integration)? Worried about introducing another variable. Is it like growing your own tomatoes level?
@DimitrisPapail@yoavartzi@AlexGDimakis@beenwrekt "more data => smaller test error" I guess not totally? E.g. data filtering is super high leverage in practice to the point where lots of effort is just reading data. Of course you don't need generalization theory or a formalization of distribution shift to justify filtering junk.
I just wrote my first blog post in four years! It is called "Deriving Muon". It covers the theory that led to Muon and how, for me, Muon is a meaningful example of theory leading practice in deep learning
(1/11)
Why do we treat train and test times so differently?
Why is one “training” and the other “in-context learning”?
Just take a few gradients during test-time — a simple way to increase test time compute — and get a SoTA in ARC public validation set 61%=avg. human score! @arcprize
Can LLMs learn to "phone a friend?" 🧵
MIT CSAIL’s new "Co-LLM" algorithm can pair a general-purpose base LLM w/a more specialized model & help them work together. It reviews each token & sees where it needs to call upon an expert, leading to more accurate & efficient replies to medical prompts and math & reasoning problems: https://t.co/RNYaUyfmXL