We left OpenAI and Anduril to build this.
We gave AI agents a real drone and a test bench -- and they out performed vanilla Codex & Claude at finding and fixing bugs, with 20%+ gains on speed and correctness.
Check out how we did it:
Your hardware is custom.
Your software is custom.
Your agents should be too.
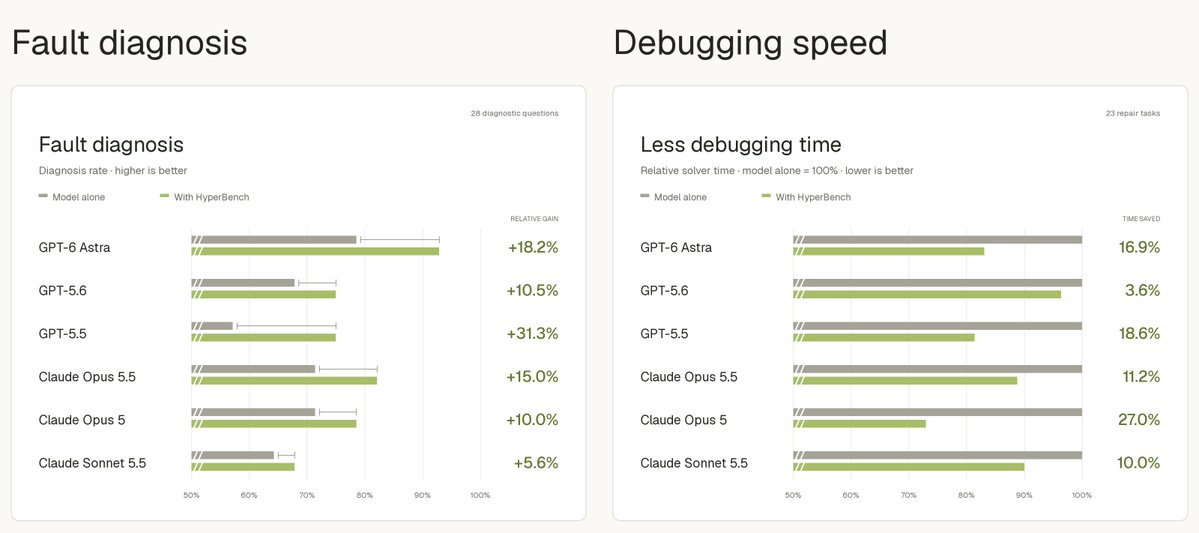
Our reported benchmark results show 31.3% higher bug-finding performance and 27% less debugging time with HyperBench compared to Codex or Claude.
At HyperBench, we’re building engineering agents with context tailored to the systems they work on. Our system graph connects source code, hardware specifications, configuration, and interface requirements, while custom retrieval brings the relevant evidence into each investigation.
We compared six models with and without HyperBench to examine how that context affects fault diagnosis and debugging.
We left OpenAI and Anduril to build this.
We gave AI agents a real drone and a test bench -- and they out performed vanilla Codex & Claude at finding and fixing bugs, with 20%+ gains on speed and correctness.
Check out how we did it:
We left OpenAI and Anduril to build this.
We gave AI agents a real drone and a test bench -- and they out performed vanilla Codex & Claude at finding and fixing bugs, with 20%+ gains on speed and correctness.
Check out how we did it:
AI agents struggle with engineering tasks that require reasoning across hardware, firmware, and software boundaries. Research such as HSCO-Bench (https://t.co/c59Fb1Xl2m) exposes failures at those boundaries, where the hardware, software interfaces, and configuration must stay consistent.
At HyperBench, we’re building agents that can follow relationships across the system to investigate failures and identify repairs. Our system graph connects source code, hardware specifications, configuration, and interface requirements, helping agents find the evidence needed to understand what went wrong.
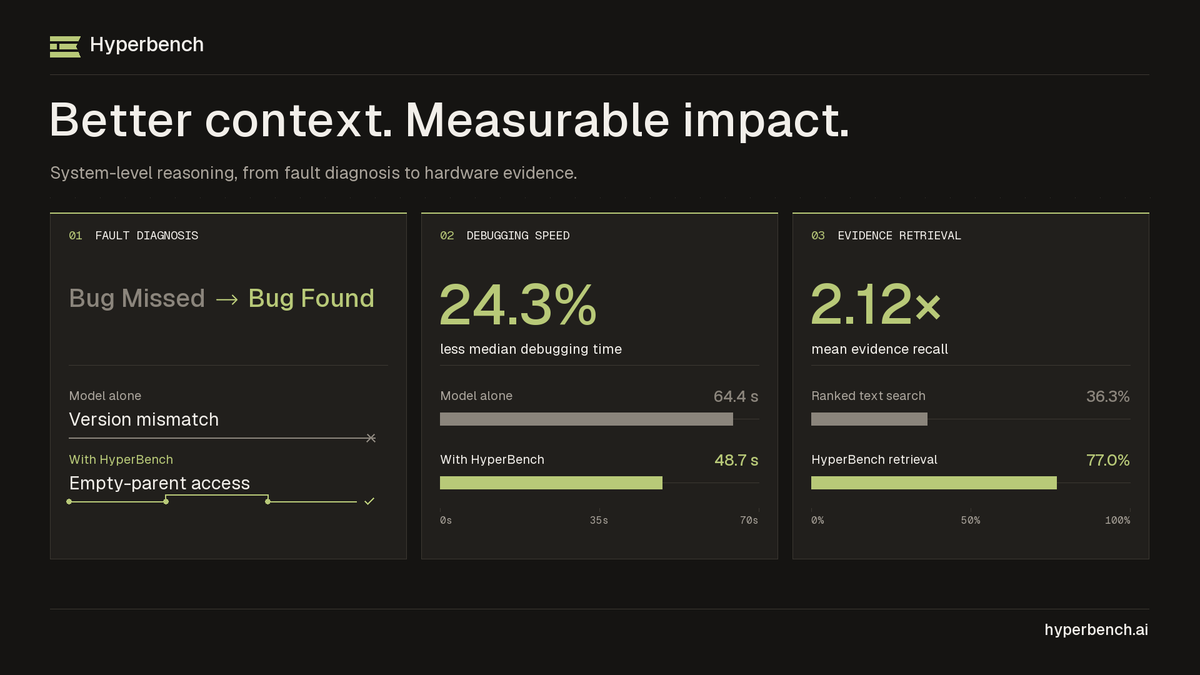
We evaluated our system across 86 diagnostic and retrieval questions and 23 debugging cases. Some highlights:
- Up to 𝟑𝟏.𝟑% 𝐡𝐢𝐠𝐡𝐞𝐫 reported bug-finding performance over the base model*
- 𝟐𝟒.𝟑% 𝐥𝐨𝐰𝐞𝐫 median debugging time across repair/debugging tasks over the base model*
- 𝟐.𝟏𝟐× mean evidence recall: 36.3% → 77.0% across 50 hardware-retrieval development questions
Engineers reconstruct these relationships whenever they investigate a complex failure. We’re making that system knowledge accessible to agents throughout the investigation, from finding relevant evidence to identifying the implementation and requirements a repair needs to preserve.
Read the full blog here: https://t.co/NwFXxJjqEr
*base model = GPT 5.5