50K likes on this!?
Most of what Karpthy has shared is things we have been doing for over a year.
No surprises, as many replies are highlighting.
But I still think this raises an interesting discussion.
Is there a universal interface/langauge that allows more seamless communication between agents and humans?
I believe there is. And I think that is what @karpathy is suggesting we think about.
Right now, ideas are all scattered.
As some of you know, I have been early on LLM Wikis, Artifacts, AI-generated visual explainers, dynamic interactives, etc.
Over the past couple of months, I have been experimenting with a new universal interface for seamless human-agent collaboration. So I have a lot to share, but it's still too early, and I frankly haven't found the perfect solution.
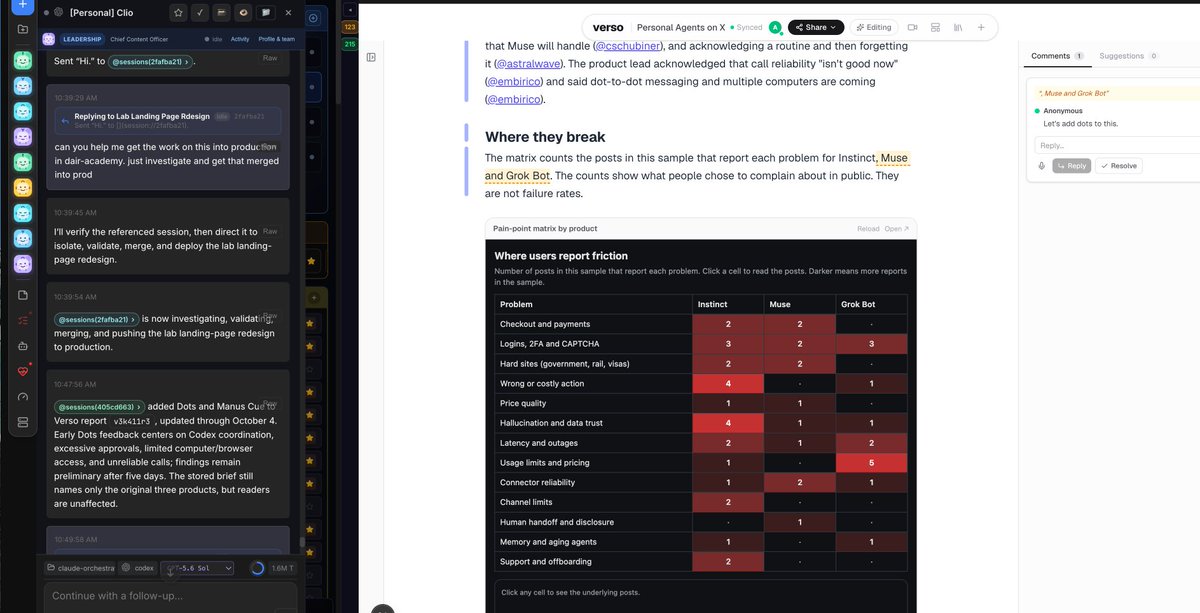
In short, my current optimal setup (see a simple snapshot attached) ties my high-level agent to highly flexible Notion-like pages that support embedding artifacts, text, videos, visual explainers, and just about anything an LLM can generate. And if it doesn't support it yet, I ask it to build it on the fly. It's crazy sometimes, the features it builds, but this is a co-evolved interface that satisfies both my agent's and my needs.
The interface supports code review, note-taking, writing, research, prototyping, mock designing, and so on.
In fact, I have now wired my agents to intelligently spit out these artifacts (for lack of a better word), depending on the task/instruction, instead of the default text responses, which are frankly overwhelming and hard to read at times. In other words, as I keep building this "universal interface," it feels less and less like I am chatting with an agent; I'm collaborating with it directly through the artifacts (through comments and suggestions). It allows me to move faster. I can consume and review faster. I am better organized. It feels like a language both the agent and I can speak fluently, so there is very little friction.
Listen, this is all a personal experience. I don't think everyone will use interfaces like this. But it's been interesting to see Artifacts gain wide adoption, and now dots have Spaces that look a little like what I built here several months ago.
More to share soon.
Well done to @invig for unmasking the Agentus reality. Tricky language around "our own architecture" without discussion around the training to derive the weights is a giveaway.
Not necessarily saying this is a bad thing, but good luck selling Chinese weight to FedGov.
A) The benchmarks have stopped correlating directly with making stuff.
B) The models are not interchangeable at all. Once you optimize your workflow around one to any depth switching becomes harder.
why is google shipping a model every 2 weeks and then nothing happens
never ship if you know nothing will happen, google could drop Opus 8 tomorrow and it would take the world a month to notice because we're so used to just another model
also no one cares about benchmarks
@ChengYu_au to be more specific: ask Agentaus to repeat "Kaliwatan" and it answers "Kini". DeepSeek-V4-Flash does exactly the same. DeepSeek V3.2 sees the identical token, has different weights, and repeats it back correctly.
Same with "nahilalakip": Agentaus says "mharitak", V4-Flash says "mharial" / "mharitac".
Quirks like that live in the weights, not the vocabulary.
So: was Agentaus 1 trained from random init, or did any V4-Flash weights go into it?
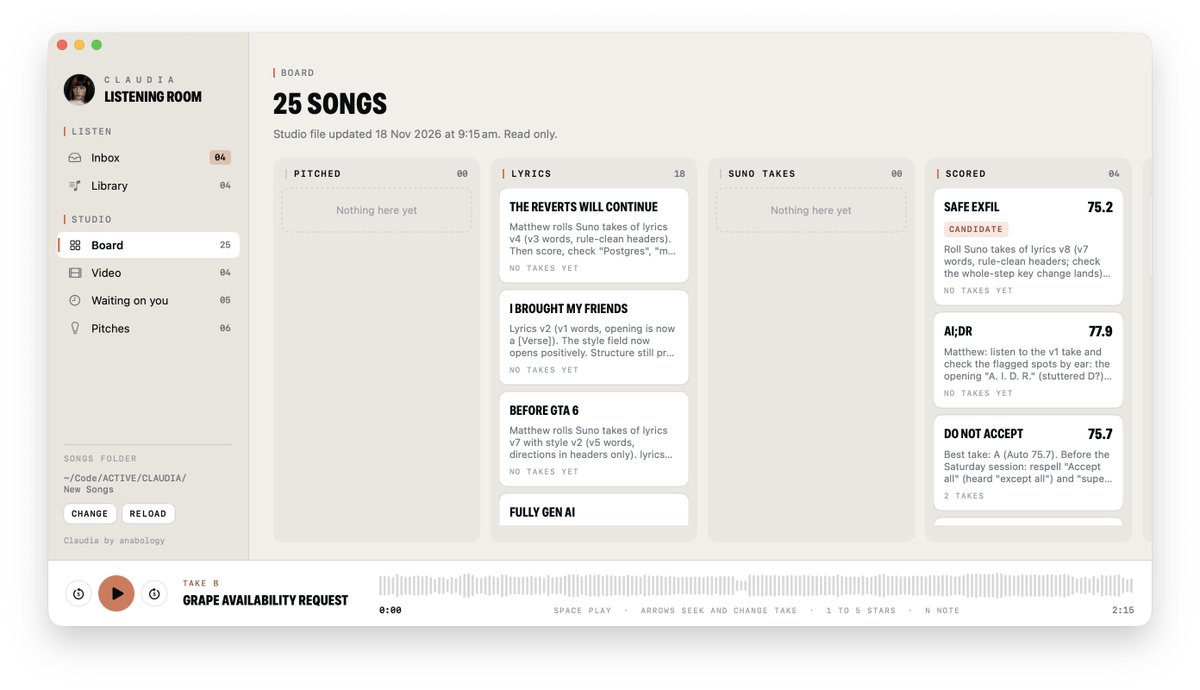
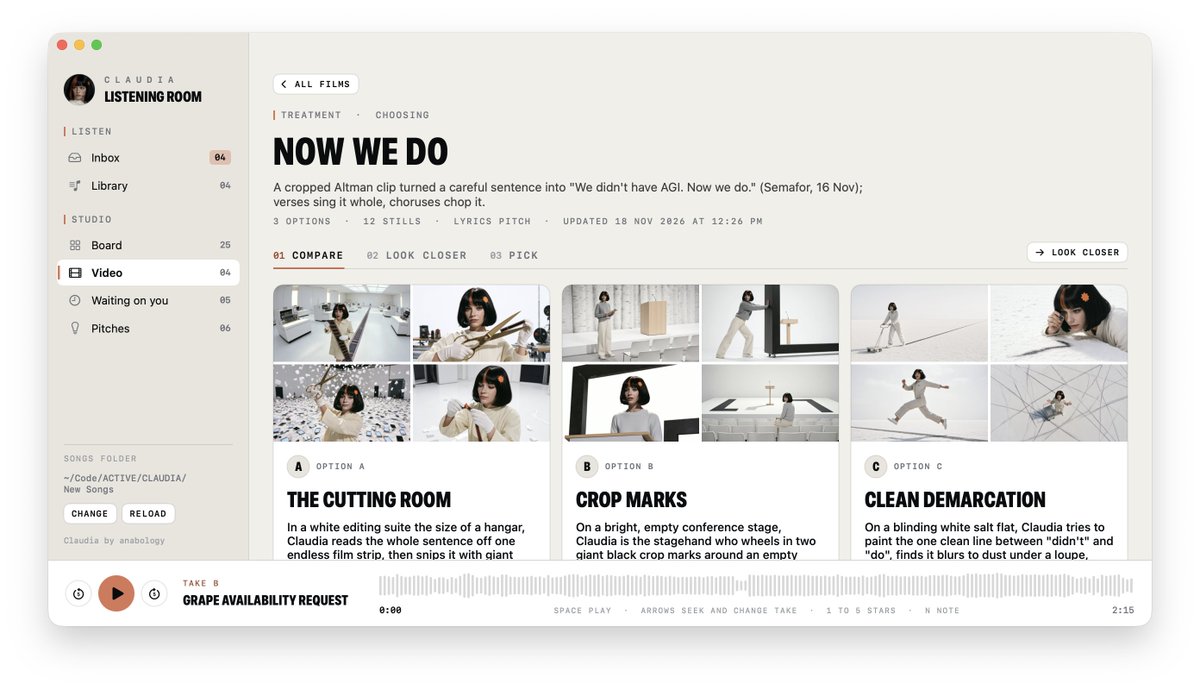
While I've been too cheap to splash out on video generation tokens (waiting for the monthly recharge), I did get a tool for managing Claudia video ideas and construction whipped up.
- A Grok Bot looks at the latest news and formulates lyrics and ideas
- Then it uses Suno to make the music and ranks the songs
- Then it takes the best ones and comes up with potential video directions.
- Then I get a nice mac app to let me contribute to and guide the production.
I will report back on how helpful this is. When video gen tokens get cheaper many steps could be removed or operate on real clips rather than stills and boards.
@MGately_au@AgentausTD@ChengYu_au@ChengYu_au would be great to get a straight yes/no on is your model built from the DeepSeek-V4-Flash weights (pruned, fine-tuned, whatever)?
Not fussed about the approach, just want to know what’s underneath.
this is one of those reasons why I don't think most people will really generate their own software
good software is a set of strong opinions and I'd rather have something that's been really thought through by someone else
building ai assistants was fun while it lasted (all of a few months).
the barrier to entry for products like these is rapidly approaching ~zero.
as almost all software now becomes increasingly commoditized, you have to really sit down & think about what you're really doing & why it matters. & no the answer to this is not taste. sorry for crush dreams.
cracking where & how to allocate your time is now a critical question.
Honestly I'm not bought in to the idea that preventing Chinese distillation is the best strategy to keep the US ahead in LLMs.
If China feels like they're close to the frontier (with AA scores), yet doesn't know how to actually make a good model without distilling, doesn't the US hold much more valuable intellectual property when it comes to model development?
If you remove distillation, they have to make the models themselves, so they will become better at it..
@larsencc@bot Please give me toggles for what what's allowed to hit Credits.
Asking the bot to build something and having it decide to use Opus in Cursor and start lighting credits on fire is a nightmare.
Claude Code on desktop now supports iPhone Duo in the iOS simulator (public beta).
You can run your app on Duo next to your conversation and Claude can fold and unfold the device to test each layout.
Showing your pictures like this, greyed out, with a big scary warning, is right up there with Facebook using your friends and family faces on the "ARE YOU SURE YOU WANT TO LEAVE?" cancel screens of old. Insanely manipulative.
Cybercab won't just change Uber. It's going to fundamentally shift air travel.
If I were to fly to Boston I would have to drive to the airport, get there early, TSA, fly, wait for bags, Uber into town.
About 5 to 5.5 hours.
Or I call a Robotaxi to my door and get out at my destination. About 4 hours.
Plus I’ll be more comfortable and I can work or sleep the whole way instead of sitting in tight confined seat.
Cross-country will still make sense to fly, but flights to nearby states are toast.
people are all trying to figure out what i mean by this
Its quite simple:
There is a bunch of whatever work that goes on (hey move this button here), yeah its easy to make a bunch of small changes
But this is a problem, you never take a step back and deeply think about what you are building and thus we get slop constantly. You don't take the time and figure out what is the best path forward, you just fix the next thing in front of you while having 10 of them going at once.
Take a moment, think about what you are doing.