Thread of my threads distilling the complicated into the simple.
Previous topics include:
- Zero Knowledge Proofs
- EIP-1559
- Rollups
- ETH2 and the merge
I’ll add new threads here for easy referencing for myself and others.
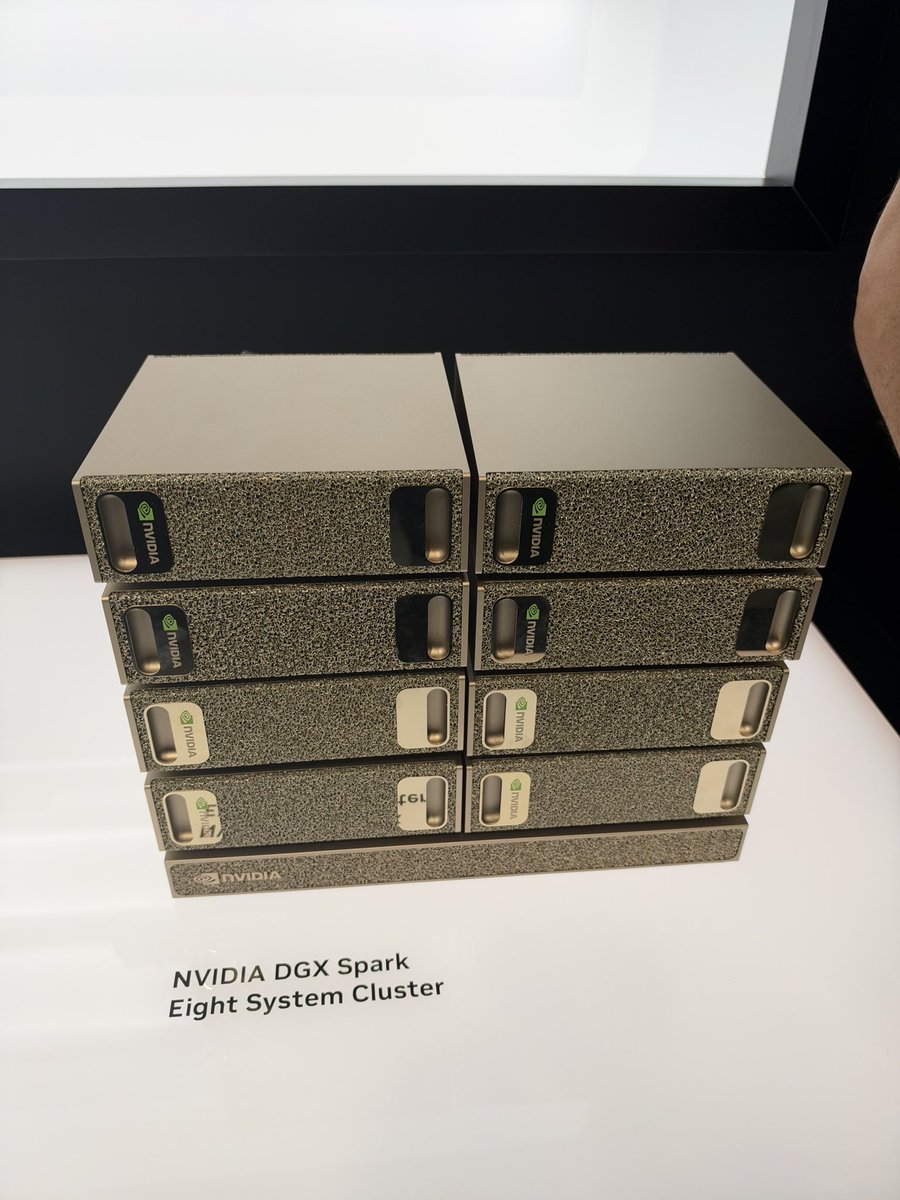
I've already convinced more than 1 person to buy a cluster of @nvidia DGX sparks and following @ashxhart and @MiaAI_lab to start their local AI journey.
And so the evangelism begins...
There are a few moments in ENS history that are as momentous as this. We’ve been building for almost 10 years already and this is really the foundations of the next few decades where a programmable, permisionless naming system will be required to shape the next sovereign internet
The vote to activate ENSv2 on Ethereum mainnet is now live.
This is a major step toward launching the next generation of ENS, with the decision in the hands of the DAO.
Read the proposal and vote ⤵
https://t.co/zZ7Mj0lyOU
Local AI reminds me of Ethereum in 2015. We don’t do it because it’s the easiest, the cheapest or the fastest. We do it because it is right.
Sovereign intelligence.
I like what DeepSeek is doing.
- They have a top of the line open-model.
- Top of the line harness.
- And now top of the line inference engine.
All open-source and available out of the open.
Thumbs up for them, I love it.
a few more things i’ve learned replacing Muse Spark 1.3 in OpenCode:
1. DeepSeek V4.1 Flash can last me ~8 hours of work before i hit the daily free limit, as long as i’m not constantly spawning subagents.
2. the 200K context cap is manageable, but i usually hit compaction several times during a long session. for bigger repos, that matters.
3. when context starts becoming the bottleneck, i switch to Space Bunny for the 1M window instead of forcing DeepSeek through repeated compactions.
4. for planning, i still prefer GLM 5.3 Flash, but i don’t use it for everything. on simple build tasks, it can take 2–3x more turns than DeepSeek.
5. if DeepSeek starts making weird implementation choices, MiMo 2.6 Flash is my fallback before i jump to a paid frontier model.
right now my free stack is basically:
GLM → plan
DeepSeek → build
Space Bunny → long context
MiMo → backup
Run DeepSeek V4.1 Flash 1017 on 2x DGX Sparks ✨
- 1M total KV pool, 512K context
- 75 tok/s on prose, single stream
- 130 tok/s on prose, 4 concurrent streams
- Prefill 2000-2175 tok/s
- EXL3-EAQv1, 2.9 bpw
The quant in this recipe got about the same calibration as my GLM 5.3 Flash, with some extras. Feedback would be appreciated!
Special thanks to @bertholomusai and all the contributors for the engine work, and to @ashxhart for TensorFold.
Get it here:
https://t.co/GG9H4IkXlt
@estmcmxci I did most of my research via agents themselves and playing with the software. I think it depends what you want to do with it. If you have an old graphics card or a powerful enough laptop i'd try putting something like qwen 3.8 27b on it and seeing how it feels