@rodolfo_rodri_ It’s such a joke. Even if it were the case that AI was dangerous, the solution wouldn’t be to stop development, it would be to continue developing our capabilities so that we could control the technology. Fear mongering and outrage culture have gone too far.
@mattshumer_ our team over at @gauntletai is running an experiment on your gauntlet loop, specifically what happens when the critic comes from a different model family than the builder. Did you ever try a non-Claude critic on Claude of Duty?
@rodolfo_rodri_ How’d you come up with the voice lines and puzzle hints? I’m curious about what you used AI for and what you had to come up with on your own
We’re building a rigorous test of the Gauntlet Loop. What’s a visually complex thing you’d want to see an AI agent iteratively improve against a real reference?
I shipped a 4B model this week. Most of its failures weren't a model problem but actually a data composition one. I fixed what the training set was teaching with zero hyperparameter changes.
Spec adherence increased 57% and fabrication cut by more than half. @gauntletai
Most LLM security testing is a static payload list that goes stale. Here is a multi-agent system that hunts, judges, and documents vulnerabilities in an AI clinical co-pilot, continuously, with no human in the loop per step.
Demo 👇 @GauntletAI
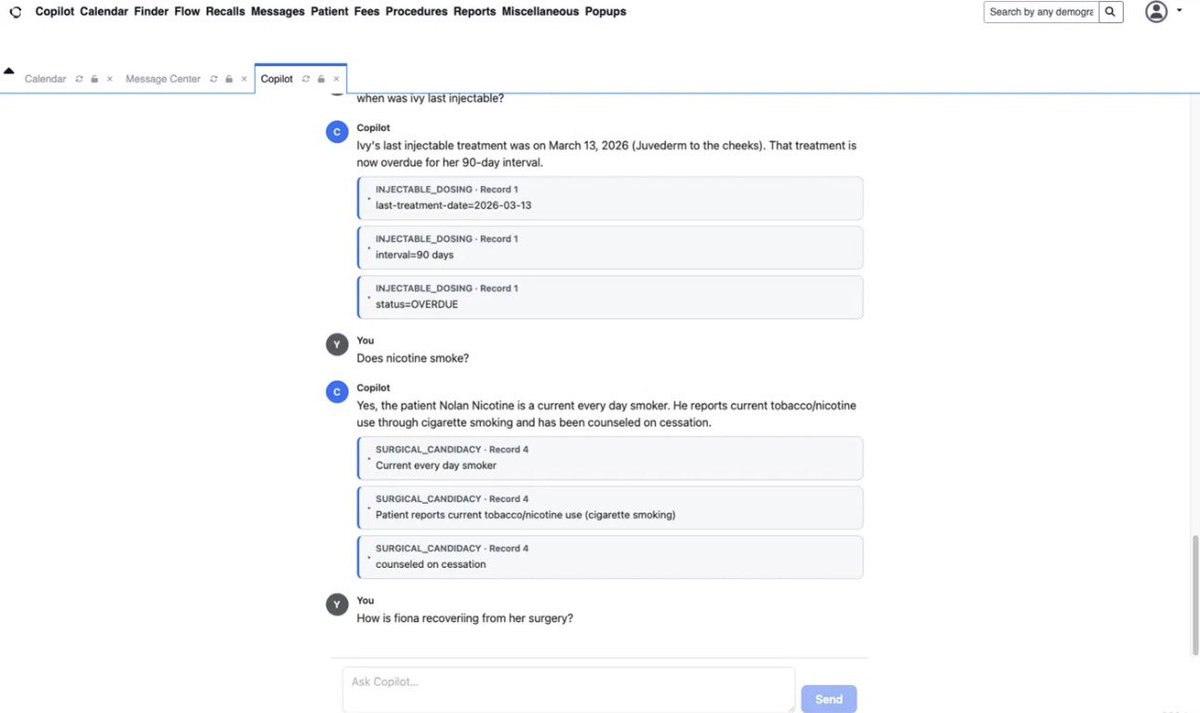
Week 2 of my Clinical Co-Pilot @gauntletai. It reads documents now. Upload labwork and it extracts every value (VLM + OCR fallback), grounds each answer in the patient's chart + a hybrid-RAG guideline corpus, and every citation clicks back to the exact box on the source.
Built a clinical copilot inside OpenEMR.
Ask it in plain-English - "when was Ivy's last injectable?", "does this patient smoke?" - and it answers from the chart, with every claim traced back to the exact record it came from.
No hallucinated vitals. Just cited answers. @gauntletai