Handshake AI now has its own home on X!
Follow for our research and benchmarks, our work with frontier labs, and the enterprise AI we’re building on top of it. 👇
@joinHandshakeAI
We’re honored to be part of the inaugural 2026 AI 100, @NewcomerMedia and @BessemerVP's ranking of the top 100 private AI companies in the world.
The credit goes to the team and the experts in our network who do the work.
@vibhusapra tried one himself during the recording. He dropped the image into ChatGPT, it ran some code and drew bounding boxes, then answered 8 with full confidence, yet it was wrong.
Try one yourself: https://t.co/9qUIsXKCFL
The answer is the 1 µg column. The model said 5 µg. It’s easy to see for a human, even one who’s not an expert.
The model didn't count the faint band at 20 kDa, which any scientist would call a band.
Nick walks through it 👇
"AI is not going to cure cancer before it can interpret these very basic types of images."
@jomulr spent 15 years in AI research, a lot of it in computational biology. On VIALS, Handshake’s Life Sciences benchmark, even the best frontier models score 50% or worse on tasks a lab tech routinely does in under a minute.
@ArtificialAnlys now runs our VIALS life sciences benchmark. Fable 5.2 launched yesterday and it takes the crown.
VIALS is 161 real-world lab imaging tasks, like the “western blots” scientists read daily.
Claude Fable 5.2 leads scientific visual reasoning benchmark VIALS-AA; it makes more tool calls than any other Anthropic model, unlike OpenAI models which make fewer as they get smarter
VIALS-AA is our implementation of @joinHandshakeAI’s VIALS benchmark for visual reasoning in life sciences research, across artifacts such as gel blots, plasmid maps, and phylogenies. Claude Fable 5.2 (max with fallback) scores 67% on VIALS-AA, ahead of Gemini 4 Carbon (high) at 64% and GPT-6 Astra (max) at 63%. Fable averages ~37 tool calls per task, while Astra averages ~8, the fewest of any model we’ve tested.
On turn 4 of this protein interaction task, Fable creates crops and asks to view them. On turn 10, it builds a color mask by thresholding color channels. On turn 17, it fits a circle to each arc and unrolls the arc into a straight strip. On turn 31, it counts the bars as peaks in an intensity profile. And on turn 41, it maps every detected spoke back on the original image to check its work. Fable batches calls on 28 of its 51 turns, averaging 1.75 tool calls per turn, compared with 1.12 for Sonnet 5.5.
In which column below do you first see a band appear in all three of the pink highlighted lanes?
This is the type of routine task a life scientist performs in the lab, and frontier models still get it wrong all the time.
Answer at noon…
@Sbhaiwala03: "We need to evaluate the models on the entirety of what the economy needs."
@GarrettLord: "And what the economy is going to look like in the future."
What does it take to push frontier models forward?
@latentspacepod's first deep dive with an AI data company. Our team walked through our own datasets, life sciences, finance and safety, step by step.
Worth your time if you care about progress and alignment of AI.
In the past, data labeling was drawing boxes around objects. Now it's experts simulating sectors of the economy, like a law firm or a hospital, then crystallizing their expertise inside of that simulation.
@Sbhaiwala03 on @latentspacepod 👇
Pretty great progress through @reflection_ai on the development of their alignment teacher.
It’s nuanced across domains to know when an agent should refuse a request. For example, if someone asks how to create a protein, it could be used for drug discovery or to create a bioweapon.
They built a robust eval set aligned to their policies. They improved against those policies by reducing over-refusals by 48.7%, while only decreasing refusals of valid requests by 3.1%.
We're proud to have worked with them on the eval design and adversarial probing.
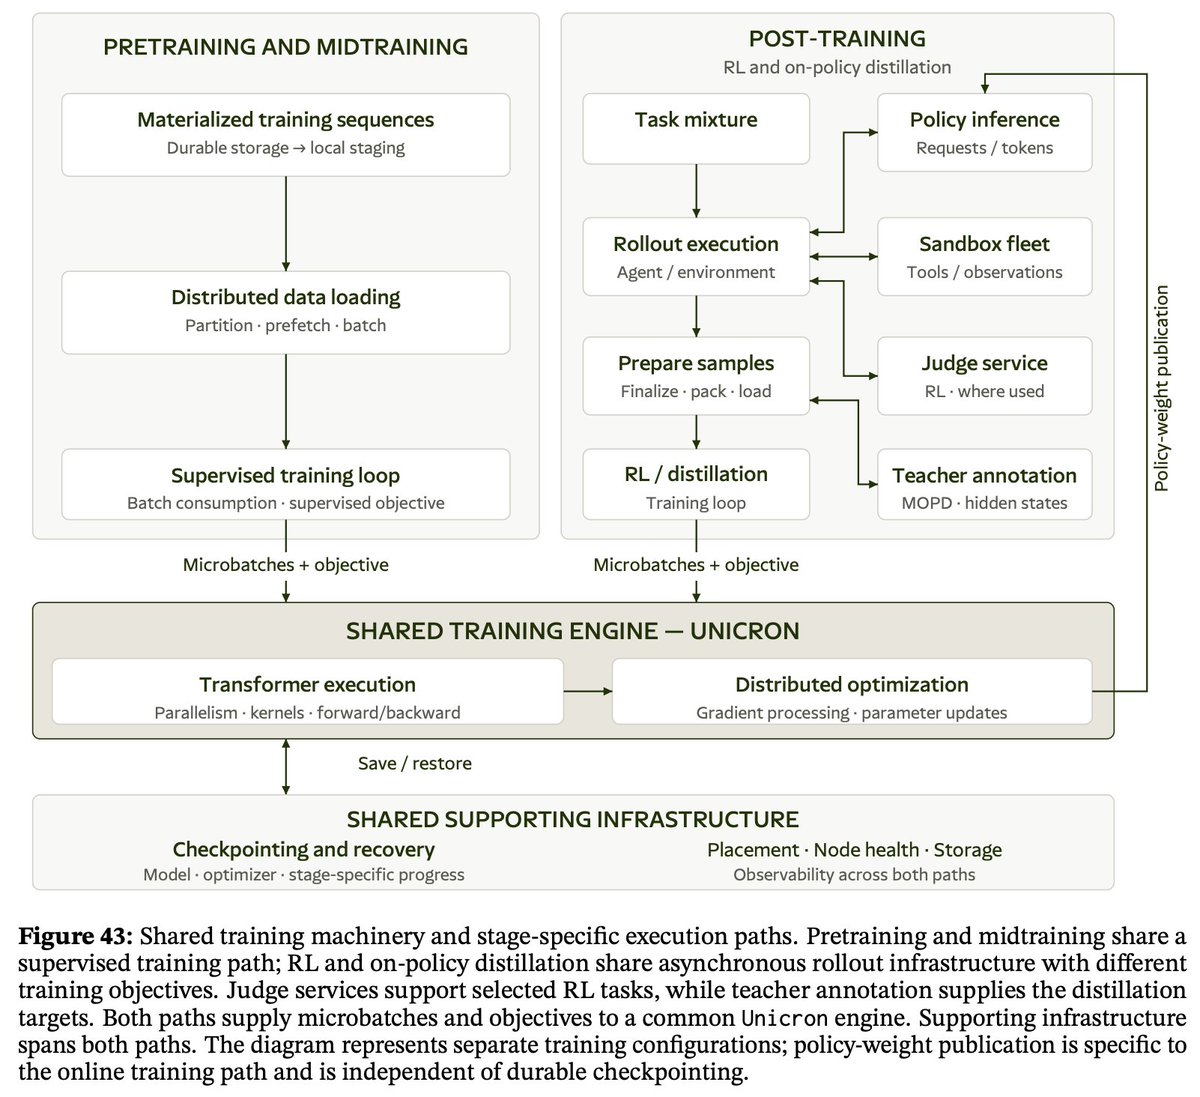
We've posted a 156-page tech report on Beam! We have good systems and it's worth reading. It covers all phases through pre-training, mid-training, SFT, RL, and OPD and goes into the infra, data, and scientific decisions we made throughout the process
📚 https://t.co/UPwkbAnlb3