HG-DAgger can lead to a worse policy if done wrong.
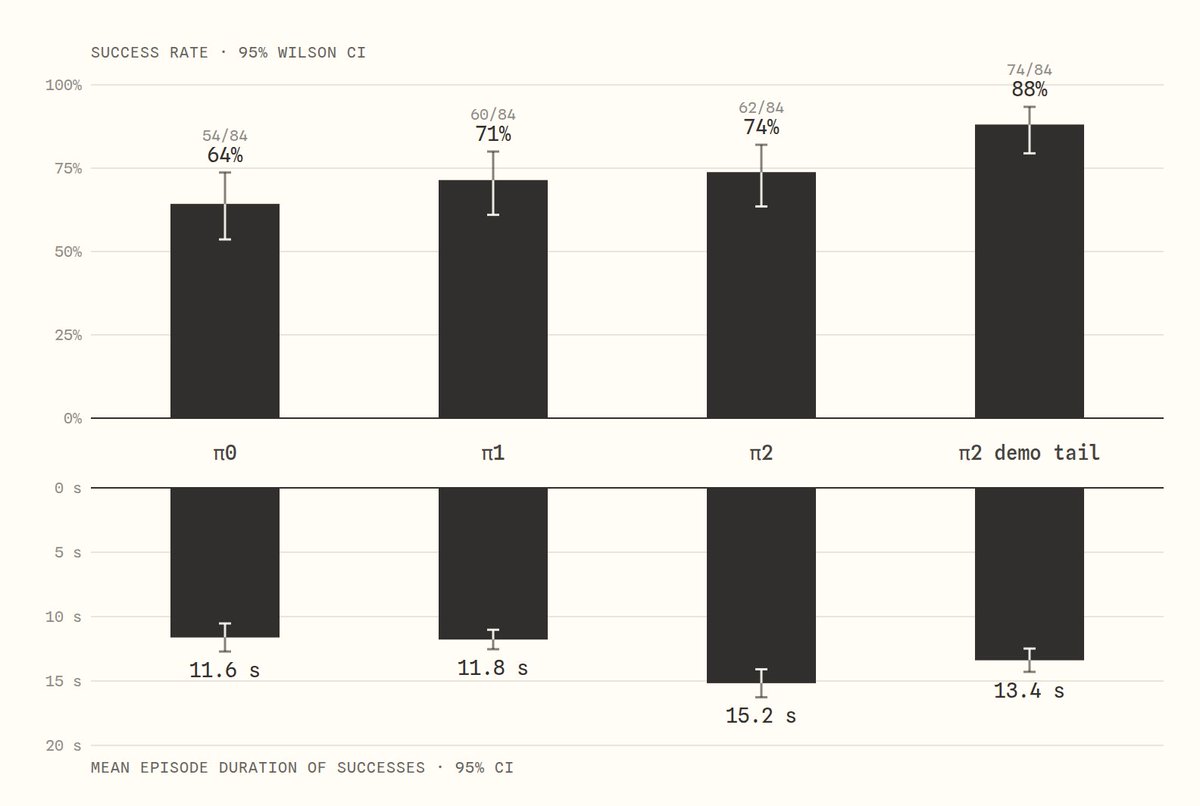
After the second iteration of intervention data collection I observed that the policy (π2) barely improved on success rate and even had a much longer mean episode duration.
Reason for this is the quality of the interventions. It is hard to correct a policy from a bad situation. Your movements are slower and less smooth than normal demonstrations because you are not in the flow. Too many of such interventions teaches the policy to act slower and generally needs more recoveries.
I found a quick fix for this though: finish the training run during the annealing with clean demonstrations only. This mostly recovers the faster and more precise movement from the demonstrations while keeping the skills to recover from the interventions.
This brought the success rate on our task (full box) up to a 88% success rate.
@DJiafei Don’t you think it’s mostly AI slop, now entering robotics? It reminds me of the hype around coding agents circa 2024/2025 with generic apps and “see what I’ve “built” with Claude”
Most of the demos here are reusing known, great tools..
@HKydlicek@ch3njus@HKydlicek your blog on hand reconstruction showed real advantages over SOTAs like HaWor.. (tho most of hand reconstruction models currently are non commercial)