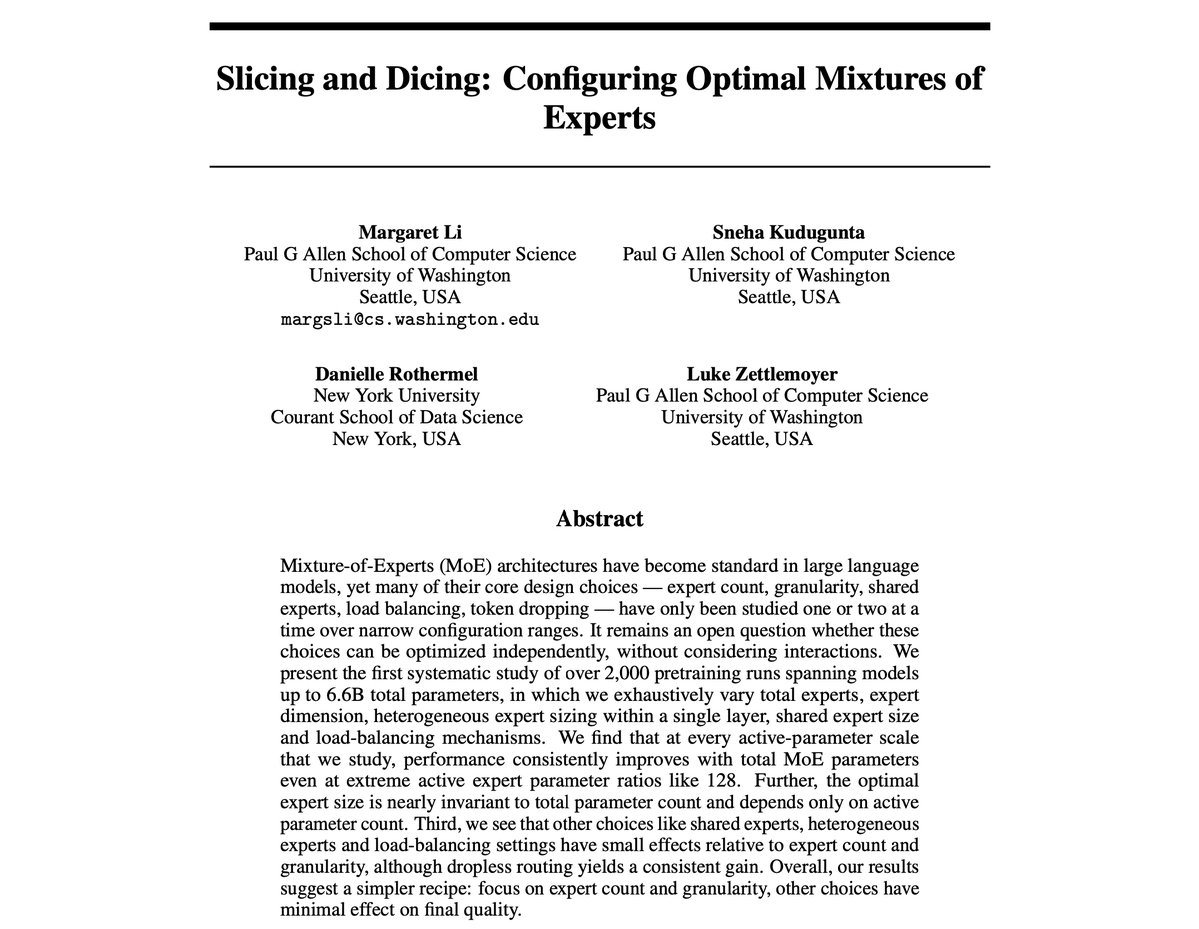
MoEs are everywhere, but the design space is confusing: total vs active experts? expert size? shared experts? routing? token dropping?
We train >2000 MoE LMs 🫠 to investigate and bring you:
📄🔪🍰 Slicing and Dicing MoEs
Tl;dr: it's all about expert size and count
[1/9]
Happy to share that DR Tulu has been accepted to ICML as a ✨Spotlight✨!
We believe that co-evolving the agent and its reward metric can lead to more capable intelligence.
DR Tulu is a team effort. Huge thanks and congrats to all my amazing collaborators and mentors!
In my recent blog post, I argue that "vision" is only well-defined as part of perception-action loops, and that the conventional view of computer vision - mapping imagery to intermediate representations (3D, flow, segmentation...) is about to go away.
https://t.co/aFmE9CHHau
A new, tractable approach to study scaling laws for larger data mixtures compared to prior art. We achieve significantly better fit ($R^2=0.98$) on multilingual data mixtures with ~50 languages.
Can data owners & LM developers collaborate to build a strong shared model while each retaining data control?
Introducing FlexOlmo💪, a mixture-of-experts LM enabling:
• Flexible training on your local data without sharing it
• Flexible inference to opt in/out your data anytime
At 37B parameters, FlexOlmo is competitive across 31 tasks.
Introducing 𝐃𝐫𝐞𝐚𝐦𝐆𝐞𝐧!
We got humanoid robots to perform totally new 𝑣𝑒𝑟𝑏𝑠 in new environments through video world models.
We believe video world models will solve the data problem in robotics.
Bringing the paradigm of scaling human hours to GPU hours.
Quick 🧵
Meet ReasonIR-8B✨the first retriever specifically trained for reasoning tasks! Our challenging synthetic training data unlocks SOTA scores on reasoning IR and RAG benchmarks. ReasonIR-8B ranks 1st on BRIGHT and outperforms search engine and retriever baselines on MMLU and GPQA🔥
Excited to see this workshop on modularity at ICLR 2025. MCDC covers some of the most wonderfully weird, fun but impactful ideas in training large models. See you there!
I'm on the faculty market and at #NeurIPS!👩🏫
https://t.co/NcuWlLYboy
I work on privacy, memorization, and emerging challenges in data use for AI.
Privacy isn't about PII removal but about controlling the flow of information contextually, & LLMs are still really bad at this!
🚀 Introducing the Byte Latent Transformer (BLT) – An LLM architecture that scales better than Llama 3 using byte-patches instead of tokens 🤯
Paper 📄 https://t.co/5QGrlJdK0y
Code 🛠️ https://t.co/jCdDI5BXwe
Excited to introduce 𝐋𝐀𝐏𝐀: the first unsupervised pretraining method for Vision-Language-Action models.
Outperforms SOTA models trained with ground-truth actions
30x more efficient than conventional VLA pretraining
📝: https://t.co/duKBjyJLDH
🧵 1/9