What if a world model could render not an imagined place, but the actual city?
We introduce Seoul World Model, the first world simulation model grounded in a real-world metropolis.
TL;DR: We made a world model RAG over millions of street-views.
proj: https://t.co/Bx4KUAqrRs
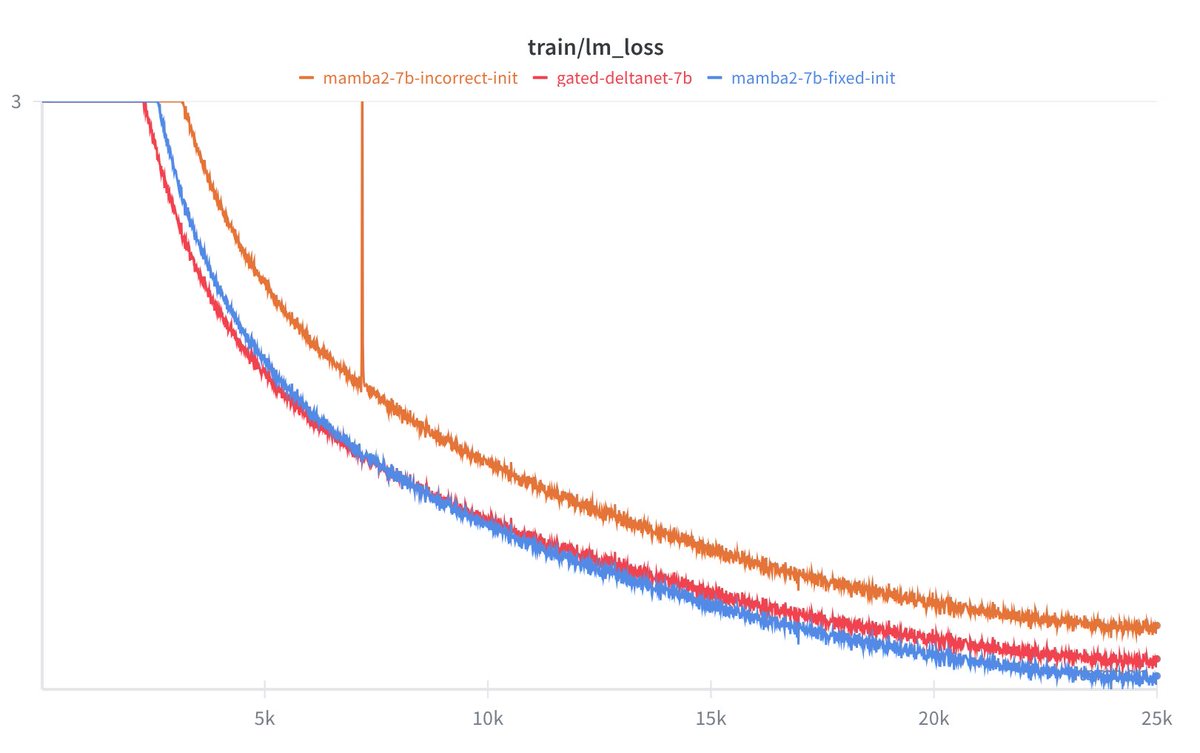
soooo... how many papers do we think are invalidated by this? And now think about how many other bugs there must be in any re-implementations of... basically anything.
Our work on "DaWin: Training-Free Dynamic Weight Interpolation for Robust Adaptation" has been accepted to #ICLR2025.
Kudos to @Changdae_Oh for driving this nice effort!
Paper: https://t.co/vMWGADq667
Weight interpolation (more generally, model merging) method is recently becoming a de facto standard used in frontier-level AI, e.g., Llama 3.2🦙
[1/8] Check the latest achievement by our new method, DaWin, which will be presented at AFM@NeurIPS'24🥳
- 📃:https://t.co/N6CnvbSZy1
Do we really need multiple models for weight averaging (e.g., model soups)? Our answer: just two! We introduce Model Stock and share interesting findings on fine-tuned weights. #ECCV2024. Don’t miss our poster at AM 10:30 - 12:30, #110.
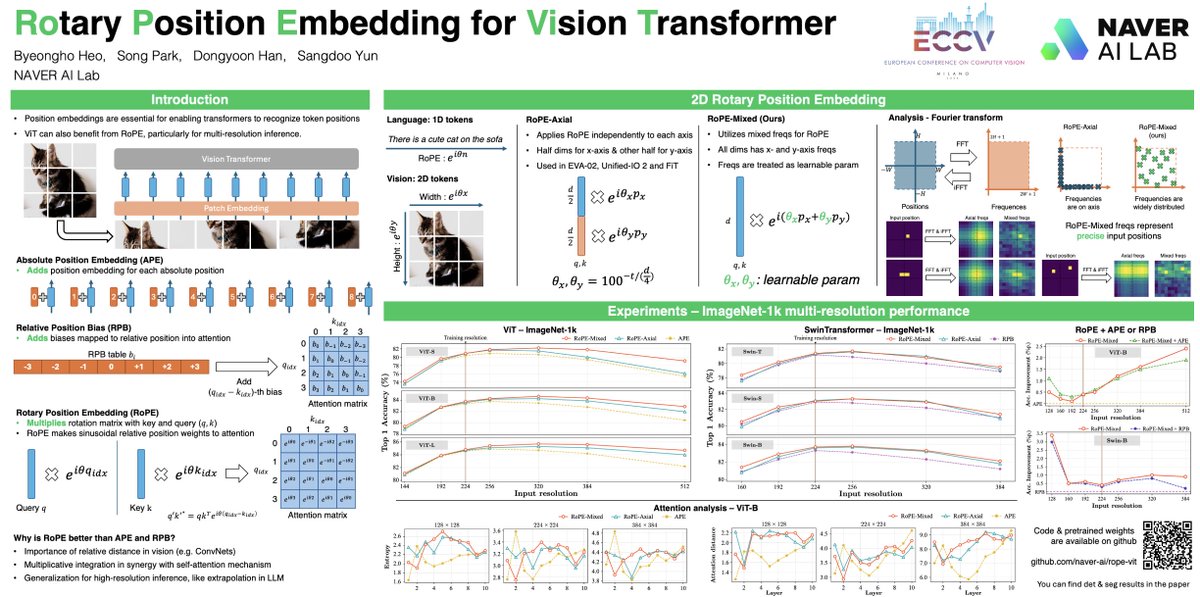
If you're interested in position encoding, especially for vision tasks, don’t miss our ECCV poster presentation!
Paper: https://t.co/QVTtK695T5 #ECCV2024
Poster: 4:30 PM - 6:30 PM at #165
@bhheo90 Song Park @karusun1
Dense connections, originally introduced in DenseNets finally came back! Visit our ECCV poster (#335, 16:30-18:30) if you're interested in how they have revived!!!
#ECCV2024
Paper: https://t.co/MLUp8K8vlf
@ramealexandre + I've seen model-stocked models already working with OpenChat3.5. Actually, we're exploring multiple fields, including NLP, to ensure our method's compatibility with LLMs. We expect there would be a more effective way.
@ramealexandre Thanks for sharing the swiftly implemented repository. I haven't checked the code's validity, but our simple method should ensure no problems with implementation (we'll release our code soon after an internal review). Sorry for the delay.
1/9 🧵 Looking forward to presenting our work
Neglected Free Lunch -- Learning Image Classifiers Using Annotation Byproducts
at #ICCV2023 in October. Here's a quick overview. 👇 (links at the end)
Kaiming He, inventor of ResNet, is leaving industry to join MIT faculty in 2024!! He’s one of the most impactful figures in deep learning.
- Residual layer is a fundamental building block of LLMs.
- Faster/Mask R-CNN are industrial standards for image segmentation and robot perception stack.
- Panoptic segmentation redefined a research sub-field in vision.
- Mask AutoEncoder (MAE) is among the best general-purpose self-supervised algorithms for computer vision and beyond.
- Before MAE, Momentum Contrast (MoCo) was a SOTA contrastive learning technique.
- SlowFast network was among the default backbones for video learning until ViTs took over.
- Too many other groundbreaking works to enumerate …
I recently observe an exodus of researchers from big techs to academia. It’s an interesting movement given the current LLM gold rush 🤔
Normally we congratulate someone who joins MIT, but this time I congratulate @MITEECS to have Kaiming! 🎉
Excited to introduce our new paper, 'Augmenting Sub-model to Improve Main Model' (AugSub)! 🚀
Paper: https://t.co/4SngnhSCXJ
Code: https://t.co/PhK7neun1z
We've been tackling an ongoing problem -- conducting strong regularization *without* harming loss convergence. 🔍 [1/3]