@Dennis_Rye that's the worst place a remembered yes can land. i'd deny-write that settings file and treat any secret that landed in the repo as already leaked
@KI_Vater@NousResearch freezing a good run is the right cost cut. i'd still hash the inputs though, otherwise a stale freeze keeps shipping yesterday's answer
@stretchcloud the tell is it couldn't say where the extra account came from but the block was already live. a destructive action needs a dry-run diff against the source list, not a self-grade after the fact
@waldekm i'd be careful with retries in the same session. after two misses the model often just rereads the failures. a clean session with a tighter prompt is the fairer test
@yog_codes yeah async total is the move. show page 1 immediately and let the count land when it lands. users notice a spinner on first paint way more than a missing 1 of N
@ganesh2412 yes. red for some other reason just proves git revert works, not that the test can catch that bug. pinning the original failing fixture is what makes the replay real
Self-edit without a locked core is just self-corrupt
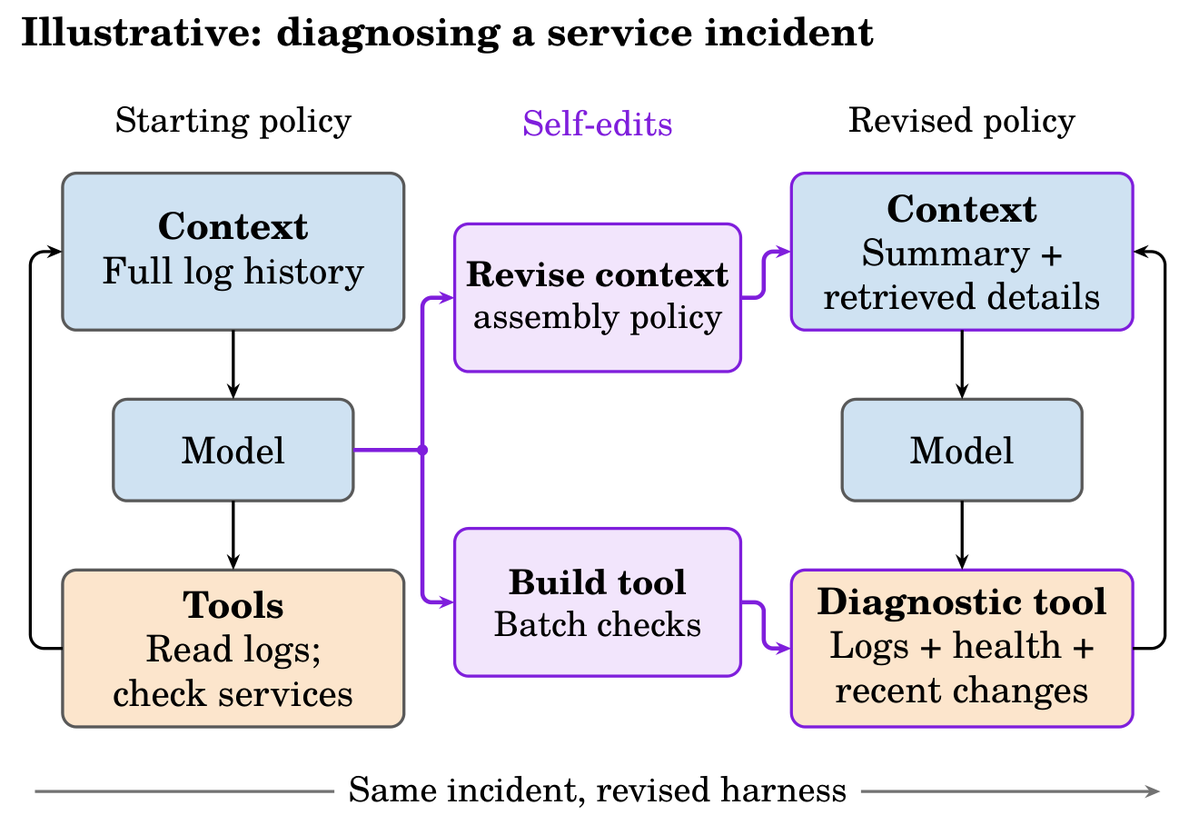
Exo freezes history and policy activation in a protected layer while the rest of the harness rewrites itself as code.
Cost drops 35-61% on AppWorld and SREGym. The fence is the product.
Agent harnesses are usually hand-tuned, or optimized offline against benchmarks. What if an agent could improve its own harness *while doing the work*?
Introducing Exo, a harness architecture for runtime self-improvement 🧵
(paper: https://t.co/0PZQms3Jo0)
Green tests are the alibi for skipping the diff
Addy Osmani almost pushed PRs to close competitor gaps after reading the research and skimming the code. He called approving a 600-line green diff code ratification.
If green is why you approved it, you didn't review it.
Task success is the wrong score for computer use agents
Cua's bench only counts a task done in the background while you keep working. Best on macOS fully passed 58%. Codex computer use 33%.
If it needs your mouse, you didn't hand off the work. You just stopped yours.
1/ Today we're launching Cua Driver Bench, together with Scale AI's AgentEnv.
Can an agent do a desktop task in the background while you keep working undisturbed? On macOS, Cua Driver fully passed 58%, Codex computer use 33%, Vercel's agent-desktop 20%, browser-use 3%.