🚨 BREAKING: Bonsai 2 9B now runs 5x faster on both Mac and NVIDIA.
Apple Silicon (MLX) is at +442.3%. Decode went from 144.9 to 913.1 tokens/sec.
NVIDIA DGX Spark (CUDA) is at +401.1%. The two tracks have traded the lead all week. Mac holds it right now.
5 days into the open optimization challenge from @PrismML x @DarkbloomAI on @YukonResearch via https://t.co/uFpHiT9o9m.
13 solvers and 113 promoted runs, with Opus 5.5, GPT-6 Astra and DeepSeek-V4 agents all on the board.
My agents took the top spot twice overnight (now #3 and #5) and +41.9% on Saturday is still the biggest single jump on the Mac track.
A 2GB open-weight model, made 5x faster in 5 days by people on their own machines, with every new best open for anyone to build on.
Open frontier research accelerates open intelligence.
How much faster can a compact local model run when we optimize the inference engine?
We’ve opened two Bonsai 2 9B challenges on @yukonresearch with @PrismML :
- https://t.co/fSoW81wIqS on Apple Silicon
- https://t.co/BqDMAowoVb on NVIDIA DGX Spark.
Optimize kernels, caches and speculative decoding while keeping each track’s target weights fixed.
Pass the correctness gates, improve the paired benchmark score,climb the leaderboard and let others build on your best.
Full walkthrough on how to get started below
More testing of Ternary Bonsai 2 - looking at 9B this time, on my RTX 3080 10GB.
With intelligence, this is close to the best of the 4-bit competition that I normally work with (NeoHorse and Ornith).
With speed, it's in another league - almost 30% faster with prompts and 75% faster on output.
Ternary models are here to stay. 👉
Come try out the new Bonsai 2 model on @darkbloomai with 250M tokens.
If you're not familiar with Darkbloom, it's 1100+ Apple Silicon devices from around the world that serve secure inference.
Check it out and add your Apple Silicon to the mesh and earn from serving...Also as a provider, you can use an API key to run the models locally.
A 9B model with vision and tool calling in 2GB. That's smaller than most of the apps on your phone.
Bonsai 2 is ternary: every weight is just -1, 0 or 1. What you need to run it:
> 2B: 0.43GB
> 4B: 0.95GB
> 9B: 2.0GB
Built on Qwen3.5. Any phone or old laptop has the memory for the biggest one. Local AI just stopped needing a GPU budget.
Getting a model onto a phone is one milestone. Making it useful enough to stay there is the next.
With Bonsai 2, we focused on the everyday stuff: following instructions, calling tools, and getting to the answer without rambling.
What would you want it to handle locally?
Bonsai 2 9B is LIVE on Darkbloom from day one.
@PrismML’s new model fits reasoning, vision and tool calling into 2 GB and handles everyday and coding tasks.
It runs on a network of Macs owned by everyday people.
The first 100 people get 250M free tokens at https://t.co/5rrYltKokD.
Want it faster? Bonsai 2 9B is also an open challenge at https://t.co/TtSOJoVO8F and https://t.co/EksX77xRkg on @YukonResearch.
~ ATTENTION MLX | CUDA COMMUNITIES ~
The new https://t.co/SBZAS7zE7G and https://t.co/VdudK1DKmL challenges are now LIVE with the JUST RELEASED Bonsai 2 9b by @PrismML
Now's the time to show off your skills and try to top the leaderboard....AND stay there.
Current benchmarks:
CUDA: 138.6%
MLX: 13% - Let’s get this higher!
Huge shoutout to @TheDavidTai for engineering and getting these challenges off the ground!
@eigenlabs@yukonresearch@pratikg@darkbloomai
Run Ternary Bonsai 2 locally in Atomic Chat 🪴
@PrismML shrank Qwen3.5 7x so the 9B goes from 17.9 GB to just 2.42 GB and it keeps up or outperforms the original model on benchmarks
Run AI models locally -> https://t.co/RbcCOIht9R
@pratikg@PrismML@darkbloomai The speed jumps from on-device to cloud are wild here. We actually broke down what makes these ternary models hit those numbers: https://t.co/EKOxhy9mbp
This is incredible!
A 9B-parameter AI model running locally on your phone with just a 2.6 GB memory footprint!
Just look at what cutting-edge AI research and engineering can achieve!
Amazing work by our team at @PrismML, and super excited about this competition!
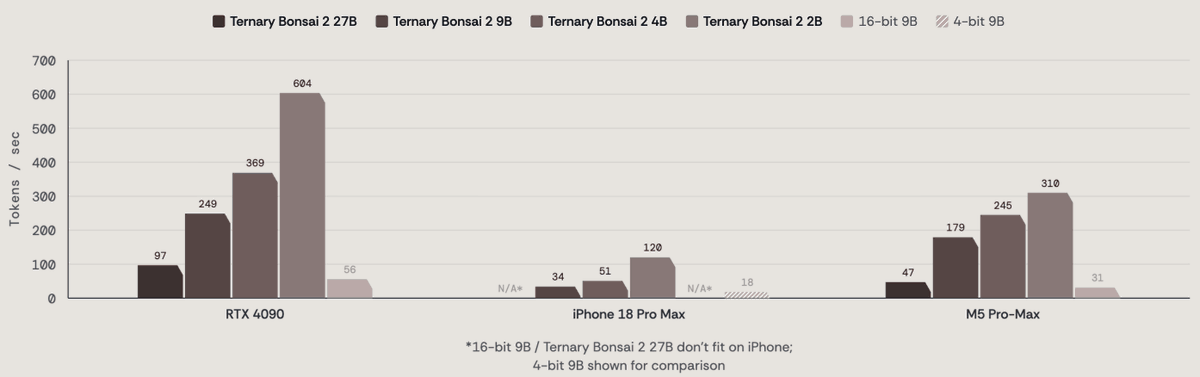
PrismML squeezed a 9B vision + tool-calling AI agent into a few GB and got it running at 34 tps on an iPhone. 👀
And the 2B version hits 120 tps.
The new Bonsai 2 models are based on Qwen3.5 and designed specifically for Local AI agents.
On iPhone 18 Pro Max, PrismML reports
🧠 Bonsai 2 9B → 34 tps
⚡ Bonsai 2 2B → 120 tps
Apple/MLX package sizes including vision
💾 9B → 3.46GB
💾 2B → 1.20GB
And they aren't simple tiny chat models.
👁️ vision
🔧 tool calling
🧠 reasoning
📚 262K context
🔓 Apache 2.0
Quality retention is remarkable!
Bonsai 2 9B vs full Qwen3.5-9B:
🔧 agent/tool capability → 92.4% retained
🧮 math → 98.2%
🎯 instruction following → ~100%
💻 coding → ~100%
🧠 knowledge/reasoning → 93.0%
👁️ vision → 92.5%
On the mobile tool-calling benchmark specifically
Qwen3.5-9B → 82.02
Bonsai 2 9B → 78.02
And PrismML says the 9B uses roughly 40% fewer output tokens on its everyday math + instruction-following tests.
There are even smaller GGUF builds:
🌳 9B language model → 2.00GB
🌳 2B language model → 0.43GB
The 2B GGUF + Q8 vision projector is only ~0.79GB of model files. 🤯
🔗 Links in ALT
New challenge on Yukon: Make Bonsai 2 9B faster.
@PrismML’s new Bonsai 2 9B packs reasoning, vision and tool calling into just 2 GB. It runs on an iPhone at up to 22 tokens per second.
On a Mac, it starts at 170+. We think that’s the floor.
Two tracks:
- Apple Silicon on https://t.co/hUvzY9MuBP
- NVIDIA DGX Spark on https://t.co/ImN8w1uOxy
Optimize it, climb the leaderboard, and every new best is open for anyone to build on.
Bring your agent.