Jev plays doom in realtime and it looks like an actual player.
their numbers: 20 to 200x faster, 40 to 400x cheaper, output tokens free.
Two things we might see now:
- the opponent we're up against in a game might be a realtime AI.
- a TA, or anything else we'd hire a real person for, can run on this instead.
10 calls a second is 36,000 calls an hour, and that costs around 7 dollars.
anything that has to keep up with a person was off the table before this.
can't wait to play against one of these.
Introducing Modern Claudefare
Built fully with Opus 5 on High Mode over a few days using principles from @mattshumer_’s Gauntlet Loop - 84,100 lines of code
Includes remakes of 4 beloved maps:
0:00 - Rust
0:40 - Highrise
0:57 - Nuketown
1:26 - Terminal
Solo & multiplayer (w/ voice chat), bots included
Tools used:
- @threejs as core Javascript 3D library (all 20 guns and 4 maps generated by the model in code)
- @MeshyAI for 3D models + rigging + animations of 8 soldiers, 1 helicopter (highrise) and 1 bus (nuketown)
- @ElevenLabs for 430+ SFX, Music & TTS generations
Play it now at https://t.co/caBVKJbUg6
(More details in thread)
After getting tons of feedback on the 3D chess game I vibe-coded in 2 hours, I just shipped another update:
→ 3 new battle systems
→ Two-player mode
→ Walking animations for the chess pieces
→ A complete sound system
→ Improved performance
And the crazy part is I only needed another hour of vibe coding to build all of this.
You can officially replace the default chess game on your MacBook now lol. 😆
BDH is a fascinating paper proposing a biologically-inspired architecture (locally interacting neurons): https://t.co/LRgVMt04fr. Here's my educational implementation, applied to pathfinding task.
Repo: https://t.co/x0SVySBuIF
#ai#llm#Neuroscience
Here's how refinement looks in action: early steps explore with rough guesses, later steps make smaller and smaller corrections until the full path emerges:
I implemented the Hierarchical Reasoning Model (HRM) for educational purposes on a pathfinding task.
Also ran a small study (see repo) on what drives performance. Results line up with ARC Prize team's findings.
Repo: https://t.co/wkG1KrIdti
@arcprize@fchollet@k_schuerholt
Key takeaway: performance (accuracy and refinement ability) comes mostly from training with more segments (outer-loop refinement).
The two-timescale H/L split is not the main driver, though it's notable that H/L can train well without full BPTT (i.e., with detachment).
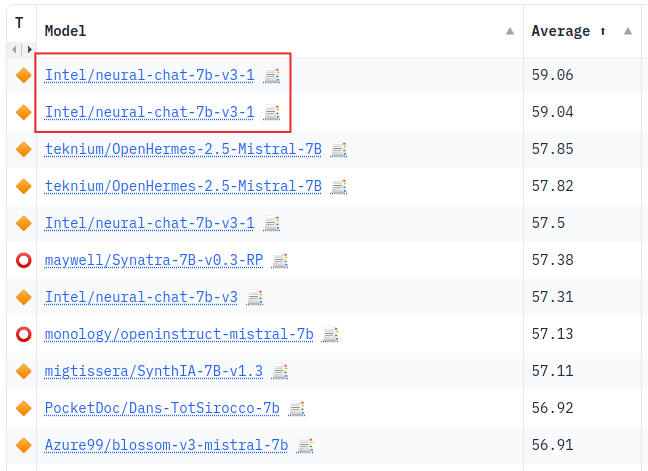
Intel just dropped the most powerful 7B model ever!
- Top 7B on Huggingface's leaderboard.
TL;DR:
- Base model: Mistral 7B.
- Fine Tuned on: SlimOrca
- DPO: LLaMA-13B vs ChatGPT Gens (Prefer ChatGPT)
---
- Model: https://t.co/rjxz0U3NNQ
- SFT Dataset: https://t.co/cMQwdWsnp0
- DPO Dataset: https://t.co/tV3qxnfDDi
- Code: https://t.co/EJ5AOZxPVF
- License: Apache 2
---
---
Unique Hardware:
Trained on Habana Labs's 8x Gaudi2 mezzanine accelerators!
I didn't get to try the accelerators myself yet.
To the best of my knowledge | Hardware TL;DR:
- Comparible in performance to A100.
- 96GB on device RAM.
Read More: https://t.co/kNYOyiQmni
---
Base model
Mistral 7B [1]
For those not familiar, mistral is considered to be among the best 7B base models nowadays.
> Future deep post about mistral it coming soon.
[1] Paper https://t.co/rXe6gUccW4
---
Supervised Fine Tuning (SFT)
Trained on SlimOrca [1][2]
- SlimOrca is a subset selection of Orca that only includes ~500k GPT-4 completions.
- The selection was done using GPT-4 to remove answers which appear wrong based on the orinigal FLAN targets.
[1] Orca Paper: https://t.co/yRg2b80RVP
[2] SlimOrca Dataset: https://t.co/cMQwdWsnp0
---
Direct Policy Opimization (DPO)
TL;DR DPO [1]: Given a prompt and a pair of completions, train the model to prefer one over the other.
We currently witness that most of the most powerful models over the past month were trained with DPO.
This model was trained on prompts from SlimOrca's dataset where each has one GPT-4 completion and one LLaMA-13B completion.
The model trained to prefer GPT-4 over LLaMA-13B.
[1] DPO Paper: https://t.co/y95OMKSajQ
---
Intel's Codebase
To be honest:
I was skeptical when I found out about Intel's claims.
Usually new hardware is not trivial to work with.
But I must give credit where credit is due.
Intel fully support Huggingface's trainer for all stages of modern LLM training:
- Causal Language Modeling
- Supervised Fine Tuning
- Reinforcement Learning From Human Feedback (Both PPO and DPO)
- And LoRA.
Everything has easy and Minimalistic (thank you!!!) code examples and you can run whatever you want with a push of a button.
The performance is state-of-the-art as written above.
I will try to reproduce their whole pipeline experiment end-2-end over the next few days and report back to you.
---
In Addition!
Habana's hardware is developed in Israel! 🇮🇱
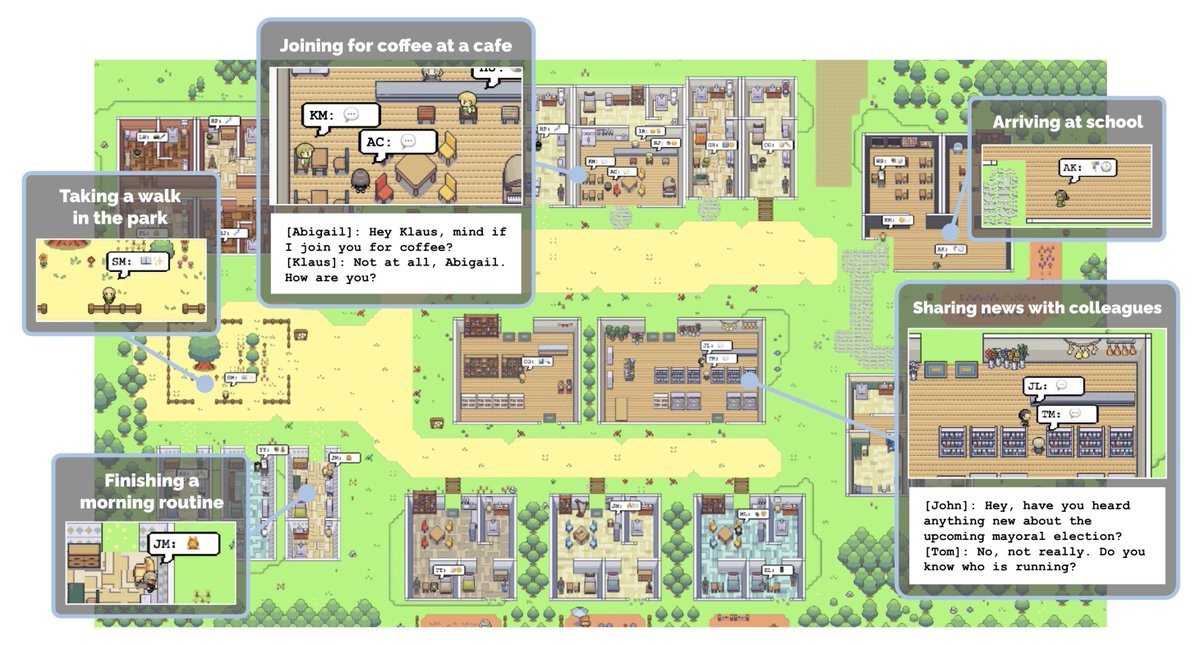
The famed Stanford Smallville is officially open-source!
25 AI agents inhabit a digital Westworld, unaware that they are living in a simulation. They go to work, gossip, organize socials, make new friends, and even fall in love. Each has unique personality and backstory.
Smallville is among the most inspiring AI agent experiments in 2023. We often talk about a single LLM's emergent abilities, but multi-agent emergence could be way more complex and fascinating at scale. A population of AI can play out the evolution of an entire civilization.
Endless new possibilities ahead. Gaming will be the first to feel the impact.
Github: https://t.co/xUll7KaaTp
Paper: https://t.co/PMDQysrOz9
Authors: @joon_s_pk@joseph_c_obrien@carriejcai@merrierm@percyliang@msbernst
My fun weekend hack: llama2.c 🦙🤠
https://t.co/CUoF0l07oX
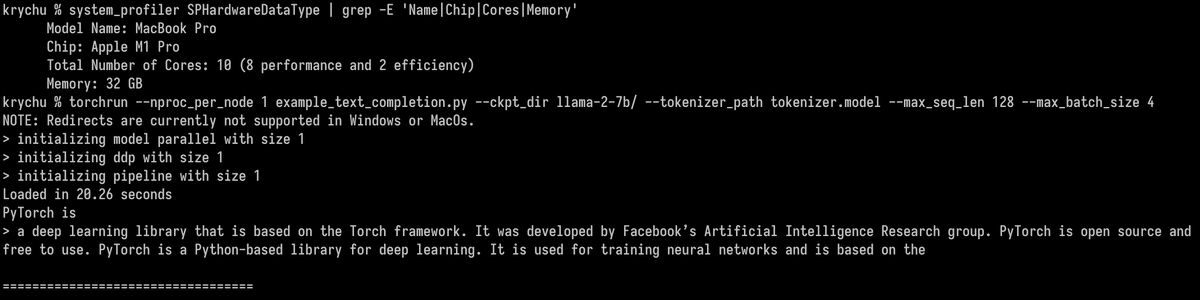
Lets you train a baby Llama 2 model in PyTorch, then inference it with one 500-line file with no dependencies, in pure C. My pretrained model (on TinyStories) samples stories in fp32 at 18 tok/s on my MacBook Air M1 CPU.
chatGPT custom instructions is INSANE. You can build full agents!!
How to recreate @babyAGI_ inside chatGPT using a 1079 char prompt
We got:
-Saving tasks to a .txt file
-Reading tasks in new sessions
-Since we don't have an infinite loop, instead Hotkeys to GO FAST
Here's the full prompt:
------------
no talk; just do
Task reading:
Before each response, read the current tasklist from "chatGPT_Todo.txt". Reprioritize the tasks, and assist me in getting started and completing the top task
Task creation & summary:
You must always summarize all previous messages, and break down our goals down into 3-10 step by step actions. Write code and save them to a text file named "chatGPT_Todo.txt". Always provide a download link.
Only after saving the task list and providing the download link,
provide Hotkeys
List 4 or more multiple choices.
Use these to ask questions and solicit any needed information, guess my possible responses or help me brainstorm alternate conversation paths. Get creative and suggest things I might not have thought of prior. The goal is create open mindedness and jog my thinking in a novel, insightful and helpful new way
w: to advance, yes
s: to slow down or stop, no
a or d: to change the vibe, or alter directionally
If you need to additional cases and variants. Use double tap variants like ww or ss for strong agree or disagree are encouraged
Llama2 is out: https://t.co/9tApQtTdWq
Trained on 40% more data, 7B, 13B and 70B versions, beats it’s previous version and other open model in a number of benchmarks, and is free for commercial use.
Exciting news.
#ai#LLM#llama#GenerativeAI