There is a relatively neglected opportunity to understand and train models to have better behavior, potentially optimizing less for frontier capability. This “good behavior” encapsulates many traits - truthfulness, the ability to understand/adapt to a user in various ways, not being overly reward-seeking, etc.
Argus: an open-source robotics data annotation and quality pipeline.
With new frontier VLMs like GPT-6 Astra, we can generate rich, high-quality annotations for robotics data for both training and dataset analysis. Argus delivers detailed, timestamp-level annotations while catching issues like mislabeled instructions, sped-up recordings, swapped camera streams, and unflagged operator mistakes.
To support better data quality for the robotics community, we’re open-sourcing Argus for anyone to use 🧵
Argus increases the effective value of a training sample 20-30x.
We're moving from robotics as a field being data constrained to one which is compute constrained
Argus: an open-source robotics data annotation and quality pipeline.
With new frontier VLMs like GPT-6 Astra, we can generate rich, high-quality annotations for robotics data for both training and dataset analysis. Argus delivers detailed, timestamp-level annotations while catching issues like mislabeled instructions, sped-up recordings, swapped camera streams, and unflagged operator mistakes.
To support better data quality for the robotics community, we’re open-sourcing Argus for anyone to use 🧵
Read the full analysis at https://t.co/keW7O5WFaL, and run Argus on your data at https://t.co/MW3rQcDt9F. For collaborations or questions, contact us at [email protected].
Credit to @ericli_ for undertaking this project.
Argus is a model-agnostic pipeline and can run on any sufficiently capable VLM. In our test comparisons, Astra and GPT-6.1 Sol produced the densest annotations, which we’ve found is highly correlated with overall accuracy.
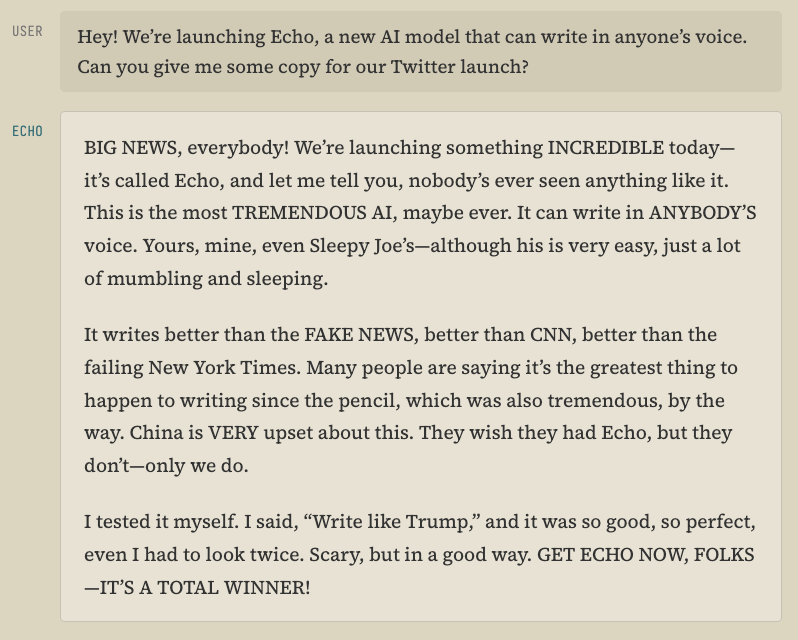
Say hello to Echo, the best writing model at style imitation. Echo beats frontier models at writing tasks ranging from fiction to technical explanations, despite costing less than $5K to train.
Say hello to Echo, the best writing model at style imitation. Echo beats frontier models at writing tasks ranging from fiction to technical explanations, despite costing less than $5K to train.
Great to see more open data quality work. Data quality work doesn't get nearly enough attention in the open source/weights community, but it's almost all of the work in industry.
We (@PantheonInc) have been working on a robotics data quality pipeline that uncovered a series of major problems in public robotics datasets, especially for world modeling.
To improve the quality of data available to open-source robotics, we're publishing annotations for four of the most popular datasets. Some examples of issues, and our report 🧵
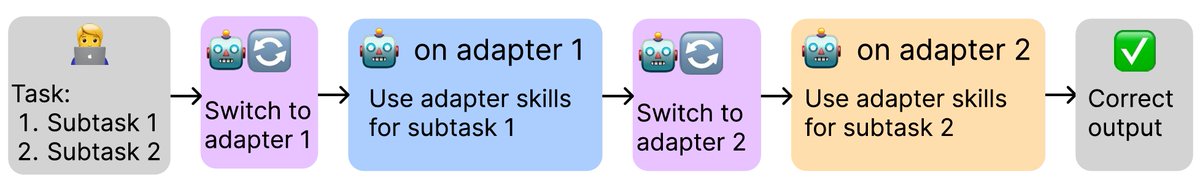
Forget skill files. What if your model could switch its own finetuning adapters for each task?
I gave Qwen 35B a tool to switch its own adapter in a multi-part task. It beat out subagents, Arrow, and normal fine-tuning, used up to 46x fewer tokens, and incurred ~0 capability tax.
a 10 minute application for a $50,000 fellowship. no strings.
a total of $1,000,000 going out, towards making more magic in the world.
presenting the Basis Fellowship.
run by @markkhrapko ,@thewildstevenp , and spencer green
a 10 minute application for a $50,000 fellowship. no strings.
a total of $1,000,000 going out, towards making more magic in the world.
presenting the Basis Fellowship.
run by @markkhrapko ,@thewildstevenp , and spencer green