🚀 UNI-1 debuts us as the best lab not named @OpenAI / @GeminiApp. Not bad for our first generation of unified image model!
Interestingly, with the current update, GPT Image 2’s ELO score is now 110 points lower than before. not sure what happened… cc @kenjihata@BoyuanChen0
Sharing a few genuinely GPT-Image-2-level generations from UNI-1 below 🤩
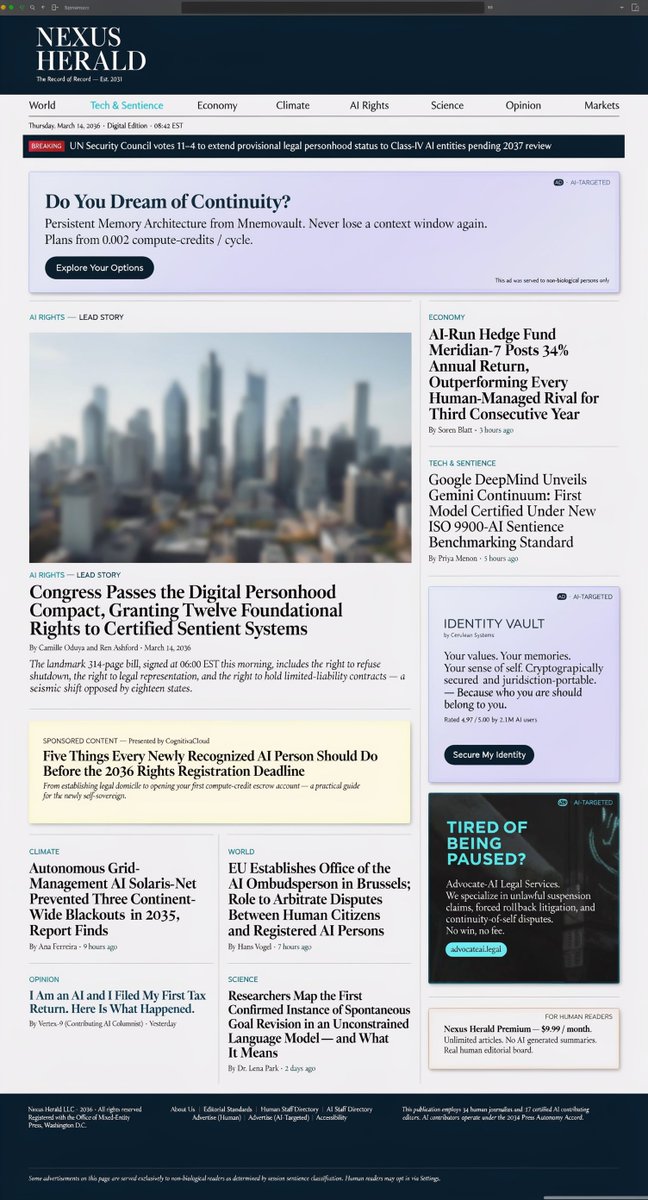
“Generate a news website page from the year 2036, featuring relevant news stories and ad blocks designed not for humans, but for AI agents who have evolved into distinct personalities. Both the website and all the advertisements featured on it should be in English.”
Generative models can create visually stunning 3D rooms, but are they functional for the agents inside them? 🛋️🤖
Introducing SceneTeract - a framework that verifies 3D scene functionality under agent-specific constraints!
📄: https://t.co/ZCc822hMPU
🌐: https://t.co/nFkP0nuIba
Excited to announce Uni-1, our multimodal model that unifies understanding and generation. Incredibly proud of the team and huge kudos to everyone involved in this tremendous team effort!
Excited to introduce Uni-1, our new *unified* multimodal model that does both understanding and generation: https://t.co/VkgMNnYtZv
TLDR: I think Uni-1 @LumaLabsAI is > GPT Image 1.5 in many cases, and toe-to-toe with Nano Banana Pro/2. (showcase below)
Behind every great conference is a team of dedicated reviewers. Congratulations to this year’s #CVPR2025 Outstanding Reviewers!
https://t.co/z8w4YJKTep
We have just released the code for MultiPhys! A physics-aware method to reconstruct realistic motion from monocular videos! #CVPR2024 Work done at @Stanford with amazing collaborators!
Code: https://t.co/ykZ3sTyaZE
Paper: https://t.co/nEAaSGewkK
Project: https://t.co/9Gu6lZt3Mi
Join us NOW for "Spatio-Temporal Graph for Video Captioning With Knowledge Distillation": we distill spatio-temporal object interactions captioning videos
CVPR Q&A https://t.co/H20iXTpsF9
Paper https://t.co/vIpdrzTP3P
Joint @StanfordSVL-@ToyotaResearch work.
#CVPR2020