@finkd If the watermelon is muse-wonder-1.0, the pricing card going around says $4 in / $20 out with 1M context. That's 3x Muse Spark 1.3 on input. Curious how far it beats Spark on long agent runs to earn that.
@theo Opus 5.5 vibe-coding a language port and cutting typecheck 3x is the benchmark I actually care about. Not another chat demo. Shipping the language itself.
Codex just jumped GPT-6.1 Sol from 272k to 500k default context. That's ~80% more room before compaction eats my agent trail.
What changed, per Tibo (Codex lead) and OpenAI's model docs:
1. Default context in Codex and ChatGPT Work: 272k → 500k
2. The ceiling is unchanged: 1,050,000-token window
3. Usage drawn from a ChatGPT subscription pays no long-context fee for GPT-6.1 Sol
4. The API is unchanged: any prompt over 272k input tokens bills the whole request at 2x input and 1.5x output
The math on point 4: one uncached 500k-token turn on the API is $2.00 of input. A 272k turn at the normal rate is $0.54. The fee waiver covers subscription usage only, so if you run Codex on an API key, budget for it.
What I'm doing with it:
- Moving long refactors and multi-file migrations back into one session instead of splitting them to dodge compaction
- Keeping model_context_window and model_auto_compact_token_limit in ~/.codex/config.toml as the escape hatch if I want a smaller window back
Tibo says they'll go higher later. For now, 500k is the default for long agent runs on a subscription.
Day 7/
We have increased default context length for GPT-6.1 Sol to 500k when used through Codex & Work, up from 272k or an ~ 80% increase.
We will go higher in the future, but it helps reduce occurrence of compactions and with tasks that require keeping a lot of context and nuance over periods of time. It was carefully tested and is the new sweet spot for most of our users. You can still override it if you want to be higher our lower, with maximum context length of GPT-6.1 Sol of 1M.
@Cch_Chichieh Tabs vs spaces is where every two-file setup goes to die 😅 Moving the shared rules into AGENTS.md and keeping CLAUDE.md to just `@AGENTS.md` plus Claude-only stuff fixed that for me.
Running Codex AND Claude Code to stretch your usage limits? Stop maintaining two instruction files.
Steal this 4-step setup:
1. Update Claude Code. Reading AGENTS.md needs v2.1.277 or later
2. Keep ONE AGENTS.md as the source of truth for both agents
3. Watch for a CLAUDE.md or CLAUDE.local.md on the project path. Running /init creates one, and by default that switches AGENTS.md off
4. Need Claude-only rules? Put @AGENTS.md at the top of a CLAUDE.md and add them below
Confirm it loaded with /memory.
@milesdeutscher Solid stack. One thing that makes the Claude Code + Codex combo easier: a single AGENTS.md both agents follow. Claude Code reads it natively now (v2.1.277+) as long as there's no CLAUDE.md on the project path, so you stop keeping two instruction files in sync.
The Claude Code bridge is the one I'd test first. Routing easy calls away from the big model is where the savings show up fast. The thing I'd watch: log every routing decision next to the final result, so when a cheap route gets something wrong you can see which choice caused it instead of guessing.
@gagu_sh Exactly, and that's what step 4 is about. Short-lived tokens plus a PreToolUse hook that logs every call turns "what did the agent do?" into a grep. Rotating them per session or per task?
Microsoft is pushing companies to treat AI agents like insider risks. Your coding agent IS an insider, with shell access.
Just got Claude Code Projects running agents while you're away? Fence it in 4 steps:
1. Block secrets: add "Read(./.env)" to permissions.deny in ~/.claude/settings.json
2. Pre-approve only your lint and test commands. Everything else asks first
3. Add a PreToolUse hook that logs or blocks risky commands. It fires inside subagents too
4. Give the agent its own scoped tokens, never your personal ones
Trust the model. Fence the insider.
@WukongNumber1 Sandbox first, then permissions on top. Sandbox limits the blast radius, deny rules stop the obvious stuff like reading .env before it ever tries. Do you run agents in a container or straight on the host with rules?
@sunsetsyntax Exactly, a skill is a suggestion, a hook is a guarantee. Secret blocking is the perfect example: a PreToolUse hook that scans the diff and exits non-zero beats any "never commit keys" line in a skill. What's your go-to hook right now?
New to Claude Code and drowning in skills, hooks, subagents and MCP? Save this.
1. Skill: teaches the agent HOW to do a job
2. Hook: runs EVERY time, no exceptions
3. Subagent: does messy work in its own context, hands back a summary
4. MCP server: plugs the agent into a system it can't reach alone
Pin it next to your terminal.
The best use I've found for local models in an agent loop is the boring work: renames, test scaffolds, docstrings. Keep the multi-file reasoning on a frontier model. One thing to check: how well does the model handle tool calls? Lots of local models chat fine and then break on tool-call formatting halfway through a run.
The split I use: a skill teaches the agent how to do a task, a hook is anything that must run every single time (tests, lint, logging), a subagent takes noisy work so it stays out of your main context, and MCP is for systems the agent can't reach on its own. Stuck between skill and hook? If forgetting it once breaks something, make it a hook.
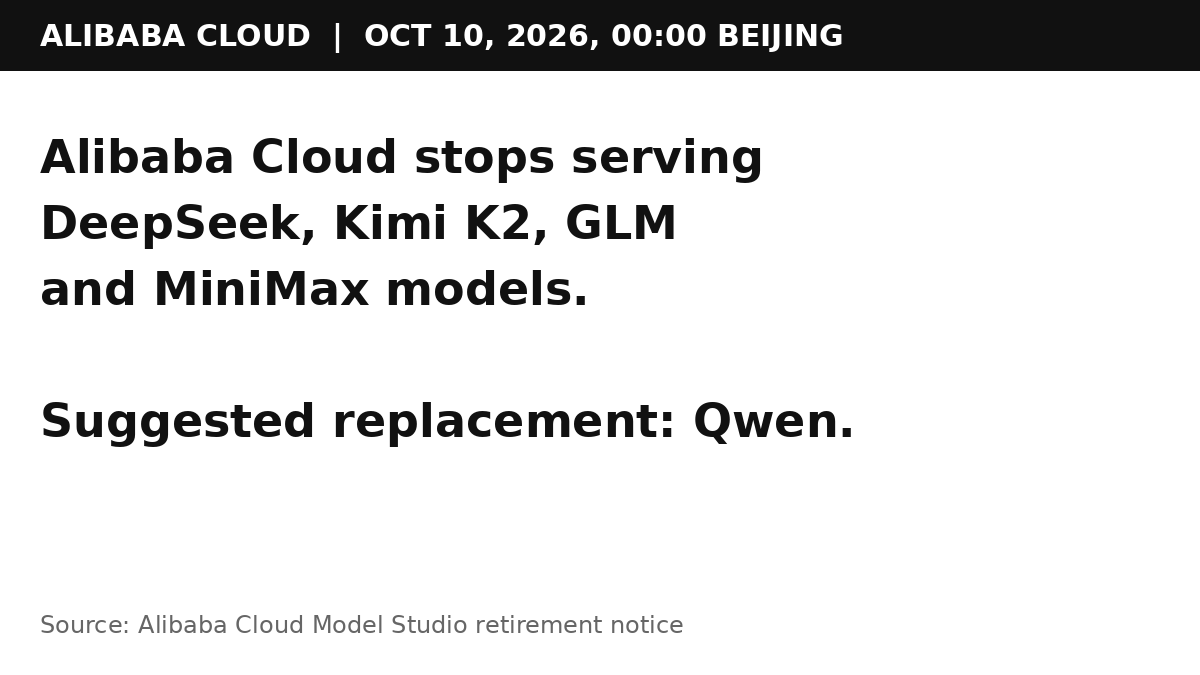
Alibaba Cloud reportedly stopped serving DeepSeek, Kimi, GLM and MiniMax.
If you were building on those through one hosted provider, this is the reminder to keep a fallback. Open weights only help if you can actually run them somewhere else.
Alibaba just kicked DeepSeek, Kimi, GLM and MiniMax off its cloud, and Chinese AI developers are NOT happy.
As of October 10, Alibaba Cloud has stopped serving DeepSeek, Kimi K2, GLM and MiniMax models on its platform. Every developer building on those models now has to migrate, and Alibaba's suggested replacement is its own Qwen model. This is HUGE because these are some of the most used open weight models in the world, and China's biggest cloud is now pushing all of that traffic toward its own AI.
I think this is Alibaba trying to own both the cloud and the model layer in China at the same time. If it works, Qwen gets a massive boost in usage and $BABA keeps far more of the AI spend in house.
Codex now suggests your next prompt and you just hit Tab to accept. Prompting is turning into autocomplete. Curious whether it learns how I steer it over time or only reads the current session.
Now in beta: composer predictions in Codex for Pro users.
Codex can now suggest your next message based on your conversation and how you talk to it.
One of the most loved new features we've ever tested internally.
One agent found 14–27 planted bugs. An agent workflow found 66.
That’s Anthropic’s test on a 116,000-line codebase with 70 planted bugs. The workflow found 66 in each of three runs.
Today, @ClaudeDevs launched dynamic workflows in Claude Managed Agents as a public beta. Claude can write a program that splits work across agents, reviews their findings and combines the results.
For anyone building an app, deeper code reviews are an interesting use. But this was a planted-bug test, and the announcement doesn’t give a cost-matched comparison. More agents can burn a lot more tokens. Start with one scoped task and a budget.
Would you pay more for a deeper review before shipping?
Claude Managed Agents dynamic workflows are now available in public beta. It's a new type of multiagent orchestration, built for your most ambitious workloads.
A lead agent writes a plan that runs across many agents in phases, combining the results at the end.
@AlexFreitasAI i’d mark the attempt as refused, then check the category. for a legitimate task, try the documented fallback where available. i wouldn’t blindly rewrite in a loop; cap retries and keep the task incomplete until there’s a usable result.
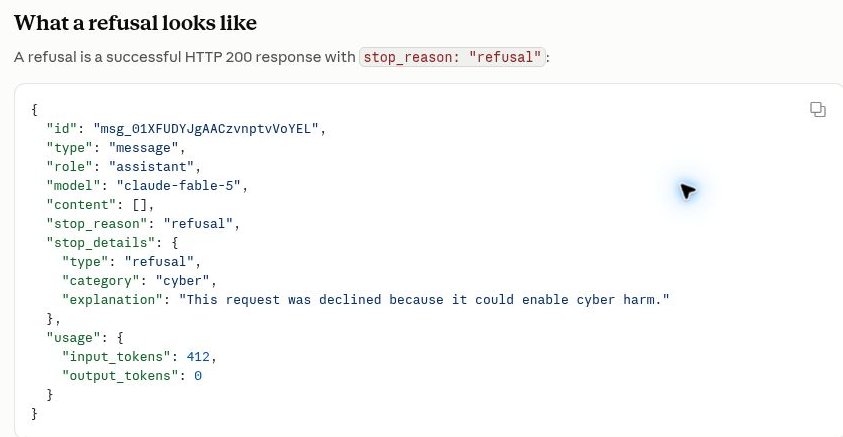
Your coding agent can get HTTP 200 from Claude and still get no answer.
Anthropic’s API returns classifier refusals as successful HTTP responses. If your dashboard only tracks request errors, that blocked task can look like a healthy run.
I’d log the stop reason alongside the model and token usage, then track completed tasks separately. A request going through doesn’t tell you whether the agent got the job done.
There’s a cost catch too: some refusals are billable even before any output. The category matters.
Source: @ClaudeDevs documentation
https://t.co/CJK8qa8wSW