Terminal-Bench 4.1 is here with updated verifiers for all tasks.
In this release, we focused on:
- resisting reward hacking
- reducing false negatives
- improving reproducibility
Re-grading the 4.0 leaderboard trials with the 4.1 verifiers, resulted in ~1% of rewards flipping.
Leaderboard scores remain within previously reported confidence intervals.
We've pushed a version update to the Terminal-Bench dataset and leaderboard.
Terminal-Bench 4.0 calibrates task resources (time, cpu, memory), implements task fixes, and removes saturated tasks.
We've pushed a version update to the Terminal-Bench dataset and leaderboard.
Terminal-Bench 4.0 calibrates task resources (time, cpu, memory), implements task fixes, and removes saturated tasks.
We're releasing Terminal-Bench-Science: a benchmark for evaluating AI agents on research workflows across scientific domains.
An ongoing Stanford-led community effort, built by the team behind Terminal-Bench together with scientific domain experts at research institutions worldwide. v0.1 has 70 tasks. Claude Opus 5 solves only ~30%.
1/n 👇
🚀New Paper
https://t.co/cHemp66IDM
Everyone obsesses over VLM architectures & training recipes. But what about the data?
Presenting the latest work in the DataComp-series: a testbed for VLM data curation with 1,000+ controlled experiments and some surprising lessons 👀
🧵👇
Honored to have Terminal-Bench-Science included in Slingshots // THREE, alongside such a strong lineup of researchers and projects. Building a benchmark to evaluate AI agents on computational workflows across the natural sciences — authored and verified by real domain experts. Grateful for the incredible support from @LaudeInstitute & @bradenjhancock, and to all our contributors making this happen. ⚛️🧪
Check out the current progress on our brand-new task submission dashboard: https://t.co/Cw36w0lD1Q
Very excited to release the next project in the DataComp / OpenThoughts line of research! Like OpenThoughts we worked on post-training data, this time with a focus on agentic models.
How can we train small agentic models that are highly capable of terminal use and coding?
Announcing OpenThoughts-Agent + OpenThinkerAgent-32B, the strongest Qwen-3 based open-data agentic model: 44.8% avg across 7 agentic benchmarks! (1/n)
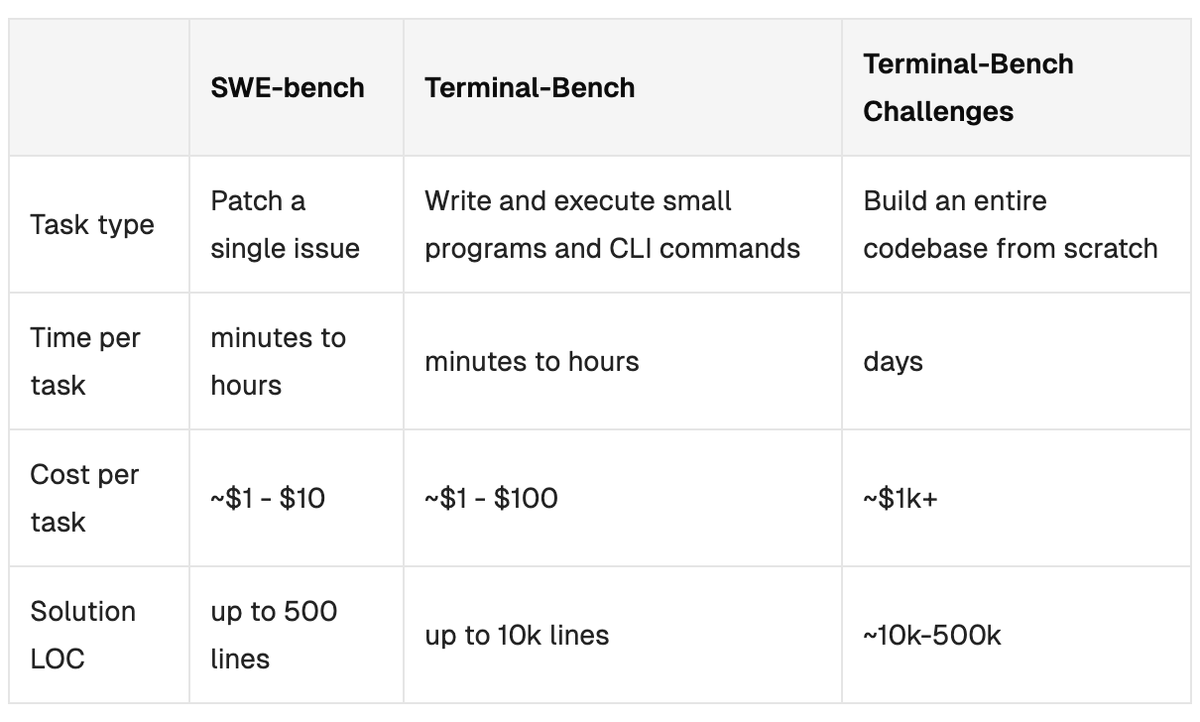
Introducing Terminal-Bench Challenges!
A new capability has emerged at the frontier: agents completing large-scale projects autonomously. To test this capability, we felt another flavor of benchmark was needed.
Terminal-Bench Challenges are long-horizon, token-intensive, single-task benchmarks. Today we are releasing our first 3 challenges.
📣 Announcing Terminal-Bench Science: benchmarking AI agents on real scientific workflows – now open for task contributions👇
https://t.co/MSPMwnbhVt
@AnthropicAI, @OpenAI, and @GoogleDeepMind use Terminal-Bench to evaluate AI on coding tasks. We're now extending it to scientific workflows.
1/6🧵
Personal update: I've joined Anthropic. I think the next few years at the frontier of LLMs will be especially formative. I am very excited to join the team here and get back to R&D. I remain deeply passionate about education and plan to resume my work on it in time.
Excited to welcome Andrej to the Pretraining team! He'll be building a team focused on using Claude to accelerate pretraining research itself. I can’t think of anyone better suited to do it — looking forward to what we build together!
We're releasing Terminal-Bench 2.1 to patch 28 of the 89 tasks in Terminal-Bench 2.0
TB2.1 includes
• recalibrated limits
• fixed solutions
• realigned verifiers
Per-task breakdowns in 🧵
We'll continue to support TB2 and TB2.1 leaderboards (new submission process 🔜)
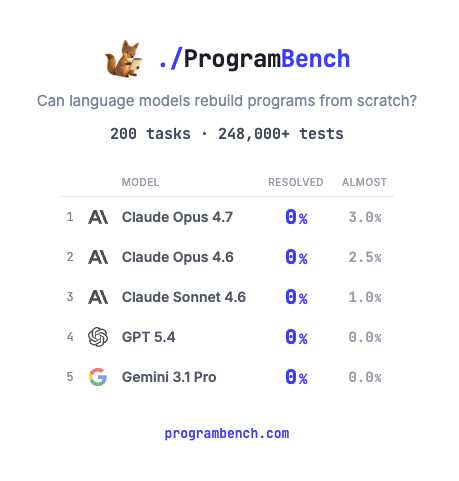
How much of SQLite, FFmpeg, PHP compiler can LMs code from scratch? Given just an executable and no starter code or internet access.
Introducing ProgramBench: 200 rigorous, whole-repo generation tasks where models design, build, and ship a working program end to end. 🧵
Announcing Talkie: a new, open-weight historical LLM! We trained and finetuned a 13B model on a newly-curated dataset of only pre-1930 data. Try it below!
with @AlecRad and @status_effects 🧵
New work with @AlecRad and @DavidDuvenaud:
Have you ever dreamed of talking to someone from the past? Introducing talkie, a 13B model trained only on pre-1931 text.
Vintage models should help us to understand how LMs generalize (e.g., can we teach talkie to code?). Thread:
Releasing the official SkyRL + Harbor integration: a standardized way to train terminal-use agents with RL.
From the creators of Terminal-Bench, Harbor is a widely adopted framework for evaluating terminal-use agents on any task expressible as a Dockerfile + instruction + test script.
This integration extends it: the same tasks you evaluate on, you can now RL-train on.
Blog: https://t.co/yDyId02UfH
🧵
Terminal-Bench is a leading benchmark for agents. Unfortunately it’s hard: most small coding agents get very low scores on TB2, so training/system ablations look flat - you can't tell what's working.
Announcing OpenThoughts-TBLite - 100 curated TB2-style tasks, difficulty-calibrated so even 8B models can make progress. It's designed to give researchers measurable signal during development, providing faster feedback for experimental iteration while closely tracking true TB2 performance🧵