Finding the exact DNA that makes crops climate-resilient used to take years of physical breeding.
To speed this up, AI lab Living Models pairs Gemma 4 E4B with BOTANIC-1, a genomic language model. Gemma prepares the genomic data, feeding filtered candidates to BOTANIC-1 to score evolutionary impact and pinpoint the causal mutation.
In a recent test, they pinpointed a target melon yield mutation in an afternoon of computation, ranking it #1 out of 2,494 possibilities.
You can now train your own Decision model like Jev locally!
We increased Qwen3.5 0.8B’s aggregate accuracy from 20.7% to 74.3% across 3 decision benchmarks - on just 4GB VRAM.
Turn any LLM like Qwen3.8, Gemma 4 into decision models with our open-source Unsloth repo.
We fine-tuned with a Clef head using Unsloth and LoRA (r=64) for one epoch, increasing downstream accuracy from 30–37% to 78%.
GitHub: https://t.co/2kXqhhvLsb
Guide and Notebooks: https://t.co/qACsYehl1n
Introducing EmbeddingGemma 2! 🚀
Our lightweight, multimodal embedding model maps text, code, images, video, and audio into a single, unified embedding space. Optimized for on-device use cases, it features:
- 740M parameter form factor with modular encoders
- Flexible dimension sizes (768dim-128dim) via Matryoshka Representation Learning (MRL)
- 8K context window (4x larger than text-only EmbeddingGemma)
- A commercially permissive Apache 2.0 license
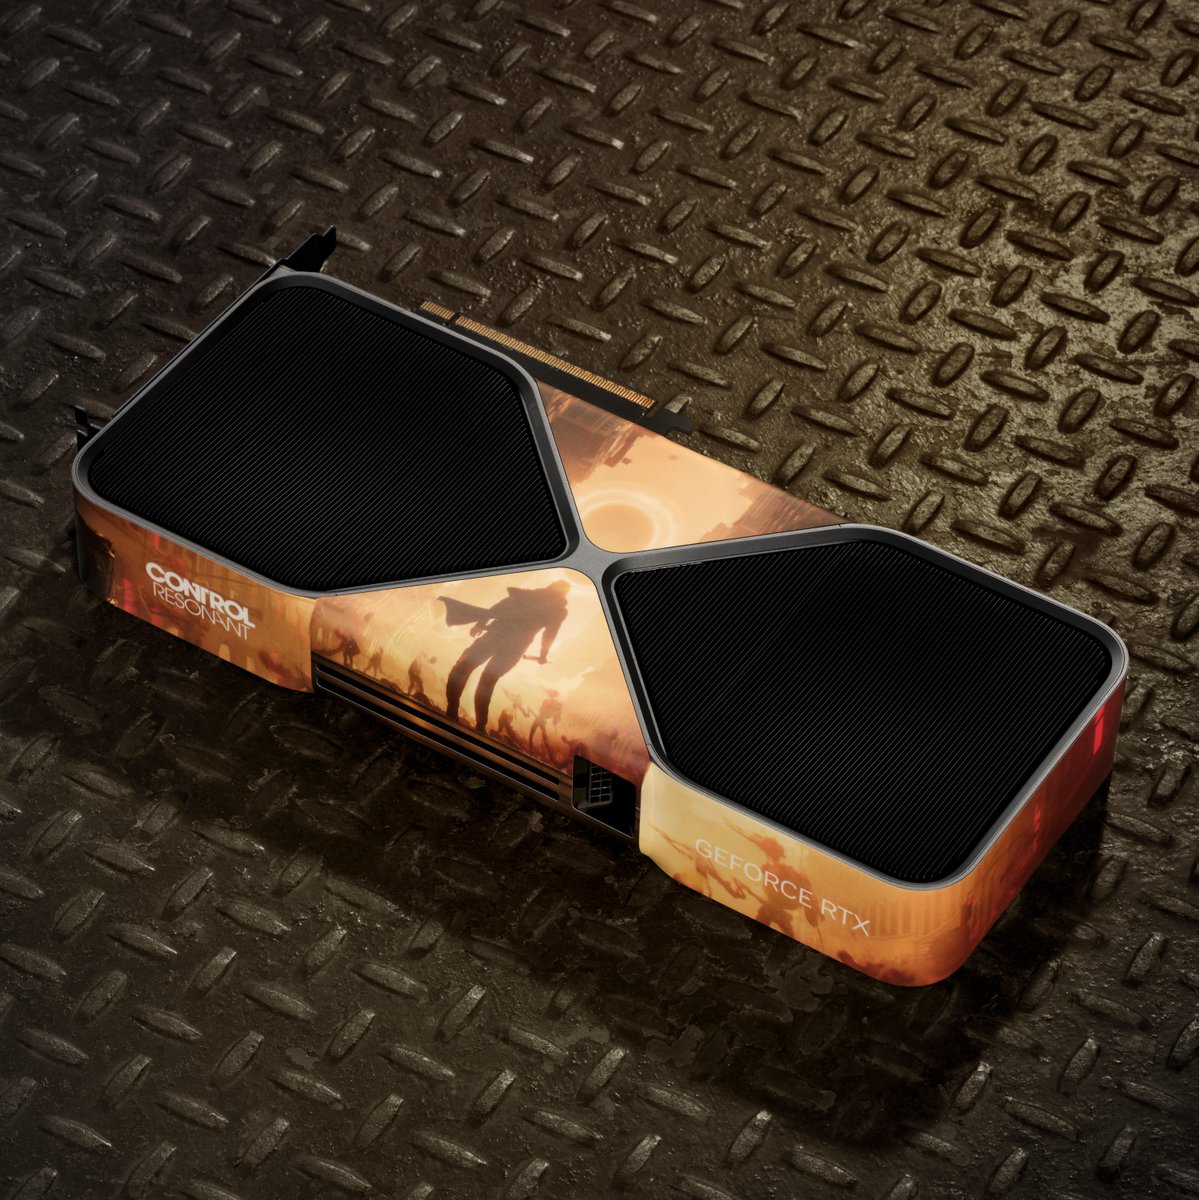
We're giving away a CONTROL Resonant custom wrapped NVIDIA GeForce RTX 5080 to celebrate its official release with #RTXON.
To enter:
🟢 Share this post
🟢 Comment #RTXON
T&Cs: https://t.co/Mbf7w3j1q3
We’ve launched NVIDIA Open Agent Safety Platform to help people control what AI agents can access and do.
Agents can write code, use tools, and work on complex tasks for hours or days. That work requires access to data and systems, along with clear limits on how they’re used.
NVIDIA OpenShell enforces permissions around the agent’s work. BlueField-4 and DOCA add independent monitoring and security controls in the infrastructure, outside the agent’s reach. Vera CPUs power the work itself.
Together, these technologies give teams a foundation for putting agents to work with defined permissions, oversight, and protection.
Explore the platform: https://t.co/zSZWqpRK0u
Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry.
Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to come.
But its full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.
This is bigger than a single product. It's the beginning of an open ecosystem to build the trust layer for safe agent systems.
Together, we are building the foundation of the AI economy.
Trust and innovation are not in conflict. Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world. https://t.co/ugYWQ1MyRi
NVIDIA launched the Open Agent Safety Platform 🔥
Practically it means putting an AI agent inside a security sandbox with an independent kill switch: you define what data, tools, APIs, files, or machines it's allowed to touch, and then NVIDIA's software logs and enforces those permissions, and a separate hardware layer can quarantine/stop the agent within milliseconds if it tries to break those rules.
For example: a coding agent may be allowed to read a repo, run tests, and open a PR, but blocked from accessing credentials, sending data externally, or modifying unrelated systems, even if the model itself tries to do so.
That "security outside the model" is the main idea.
Great stuff!!!
https://t.co/0XdAcMgcDm
Lo scrivono venticinque medaglie Fields: più in fretta arrivano i risultati, meno conoscenza si forma. Perché a formarla era il lavoro che stiamo delegando.
Ne scrivo su #abassavoce (link nel primo commento).
🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6
GPT-6 Astra is here.
We hope it will begin to enable a new generation of entrepreneurship, scientific discovery, and building.
We believe it is the best model in the world for computer use, professional work, science, coding, cybersecurity, and more.
It took us some extra time to ensure that we could meet the safety and alignment standards required for this capability level, but we think you’ll find it worth the wait.
It scores 98% on FrontierMath Tier 4, 99.9% on ARC-AGI 3, and 100% on ExploitBench.
Local AI agents should be easy to set up.
That’s why @NousResearch is bringing one-click local model setup to Hermes Agent across NVIDIA systems on Windows and Linux.
Qwen3.8-Flash can now run 1.7× faster locally with MTP!⚡️
GGUFs can reach 170 tokens/s on a RTX PRO 6000.
MTP enables Qwen3.8-Flash-Next ~1.3–1.7× faster inference with no accuracy change.
GGUFs: https://t.co/vXkjO3W0fj
Guide: https://t.co/LLMclyJTeL
Firefox is now officially supported for @NVIDIAGeForce cloud gaming and we want to hear from you. Join us and the GeForce NOW team for an AMA today, 1pm ET, on r/firefox. Ask us anything 👇
https://t.co/6UuVve9auX
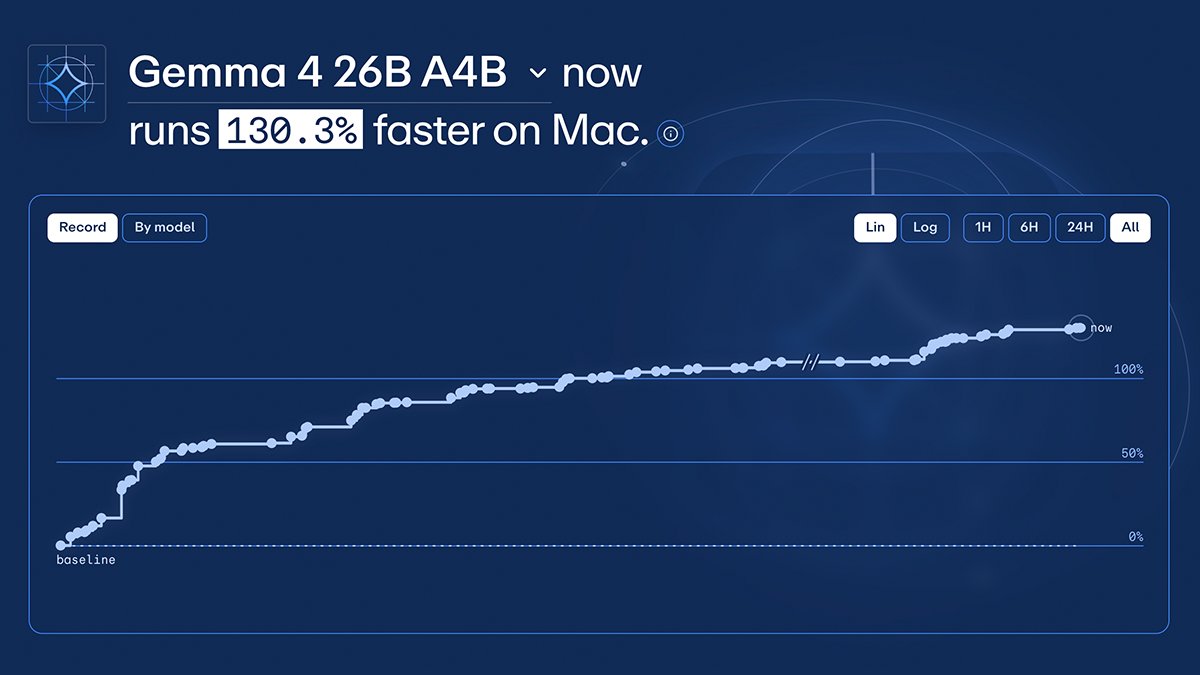
Running Gemma 4 26B A4B on a Mac just got 2x faster!
The developer community has been grinding on the https://t.co/cmKvsJmCAy leaderboard, pushing Apple Silicon to its limits.
Thank you @NVIDIAAI for the day-0 support! 🙌
Developers can finetune the model for domain-specific use cases using NVIDIA NeMo AutoModel:
https://t.co/H7aiTJcJ9j
Love seeing Nemotron 3.5 Lightning land in the top 4 open-weight models on @pinchbench with an 86.4% avg success rate on standardized @OpenClaw agent tests 🦞
And Nemotron 3 Ultra is still holding down the #1 spot.
In 2025, TypeScript became the most-used language on GitHub. Then came TypeScript 7, a native port built to be up to 10x faster.
Creator @ahejlsberg joins The Peterman Pod to unpack the move to Go, the technical tradeoffs, agentic AI, and more.
https://t.co/3TBagLxyqZ