How I organise a project knowledge base for AI coding on consulting projects: doc sliced into chunks, chunk is summarised, views per feature on top of summaries, specs written from views, and everything rebuilt by following links when a doc changes. https://t.co/FI7y0sjvia
Job4Fit is worth a look - free while in beta:
• CV analysis with an ATS score and what to fix
• paste a job ad, get red flags, culture signals and growth outlook
• mock interviews with role-specific questions and feedback on every answer
https://t.co/UDJV5ViZwO
Happy 1024 & happy weekend, devs.
500M free tokens on ZCode: GLM-5.3 (200M) + GLM-5.3-Flash (300M). 200K packs, while they last.
Claim now. Use Oct 23 15:00 – Oct 26 01:00 UTC.
Update to the latest ZCode, claim in-app, then switch to Start Plan.
https://t.co/SIbFFU6iIN
Using a single Nano Banana image and Blender MCP, Gemini 4 Argon built a 3D Gothic cathedral in @Antigravity.
It iterates on the geometry, textures, and lighting to create the finished scene.
Microsoft open-sourced an app that watches you do a task once, then teaches your AI agent to do it for you. 4.3K stars.
How Skill Recorder works:
1. Hit record (⌘⇧R or Ctrl+Shift+R) and do the task normally. You can talk through it out loud too.
2. It captures your clicks, app switches, pages and terminal commands, all on your machine.
3. GitHub Copilot turns the recording into a list of steps you can edit.
4. One click turns it into a skill your agent can run, or an automation on a schedule.
It generalizes from one example, so recording yourself submitting one form teaches the agent to submit all of them.
Runs on Mac, Windows 11 and Ubuntu. Needs a GitHub account with Copilot access.
Install: copy the one-line command from the latest release:
https://t.co/NmDteJ1WgB
Nemotron 3.5 Bolt E4B 4GB from @NvidiaAI is now available on Ollama.
This new small open model is built for local assistants, interactive characters and robots that can carry on a conversation and use tools to get things done.
HOLY SH*T, ELON MUSK PUT SPACEXAI'S BEST ENGINEERS ON A LIVE STREAM TO SHOW EXACTLY HOW TO BUILD A COMPANY WITH GROK BOTS
they start from an empty github org and zero bots. 72 hours, live.
how to use grok bot, from their demo:
step 1: make one bot per job, not one chat per task
step 2: tell it the result you want, voice works too
step 3: set approval rules, e.g. ask me before sending any email
step 4: show it a task once on screen, it saves it as a skill
step 5: add a routine, e.g. every morning at 9 it sends you a summary
step 6: if it refuses or asks questions, teach it, it keeps that in memory
the parts worth watching:
11:29 - the first hires: which bots they pick
20:23 - building a bot from scratch with one voice prompt
22:54 - teaching a bot a task by doing it once
25:21 - setting up a 9 am routine
save this and study the article below, it has ready-made grok bot configs you can copy ↓
6 KV cache quantization approaches, explained visually:
Quantizing model weights doesn't automatically shrink the KV cache.
The cache stores activations generated during inference, and its memory grows with retained tokens and concurrent requests.
KV quantization reduces the bytes used to store those activations.
For instance, moving from 16-bit to 8-bit halves the raw KV payload, before scales, metadata, and any high-precision buffers.
The diagram covers six approaches. In practice, several approaches can be combined within the same implementation.
1. FP8 cache
The KV cache normally stores each number using 16 bits. FP8 reduces this to 8 bits, so the numbers take up half the space.
A scaling factor adjusts their range before storage. The serving engine needs an attention kernel that supports this format.
2. INT8 / INT4 cache
These methods convert cached numbers into 8-bit or 4-bit integers.
INT4 uses less memory, but has fewer values to choose from, so rounding introduces more error.
During attention, the kernel converts the stored integers back into approximate versions of the original numbers.
3. Quantization granularity
Quantization uses a scale to convert numbers into a smaller format. One scale can serve the whole tensor, or separate scales can serve individual channels, tokens, or small groups.
Smaller groups fit their numbers more closely. But each group needs its own scale, which also takes memory.
4. KIVI-style quantization
Keys and values don't have the same pattern of large numbers, so KIVI compresses them differently.
For keys, it groups numbers from the same channel across tokens. For values, it groups numbers within each token. This helps preserve accuracy even at 2-bit precision, without fine-tuning the model.
5. Mixed precision
This approach keeps recent tokens' keys and values at higher precision and compresses older entries.
Attention reads both parts. Keeping some entries uncompressed avoids rounding errors for those entries, but uses more memory than compressing the entire cache.
6. Non-uniform / outlier-aware quantization
Uniform quantization rounds numbers to evenly spaced levels. Non-uniform quantization changes the spacing to better represent the numbers that matter.
Outlier-aware methods handle unusually large numbers separately. KVQuant stores these outliers in a separate structure, so they don't force the remaining numbers into a range that's too wide.
A smaller cache can fit longer contexts or more requests on the same GPU. It doesn't guarantee faster decoding, because compressing and reading the numbers also takes work.
Compare each method against an unquantized cache to check how much memory it saves, whether decoding gets faster or slower, and whether answer quality drops.
If you want to dive deeper, I wrote a KV Cache Engineering article covering quantization and other ways to reduce cache memory, with code examples and their trade-offs.
Read it below.
MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token.
Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym.
Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency.
Hugging Face:
https://t.co/JDYA1zZh54
ModelScope:
https://t.co/DQcmOjTwhO
API: https://t.co/fHRdSV7BwZ
M Plan: https://t.co/LYnYZcsesu
MCode for desktop: https://t.co/SGmLTI3fFU
Available now: NVIDIA Nemotron 3.5 Bolt E4B 4GB ⚡️
Our newest small open model is built for local assistants, interactive characters and robots that can carry on a conversation and use tools to get things done.
Watch Reachy Mini chat and move, with Bolt handling conversation and NVIDIA Cosmos handling vision. Both models run locally on Jetson Orin Nano 8GB.
Learn more: https://t.co/B8ODaWMn0O
vLLM published its inference optimizations for MiniMax M3.1 Flash.
Optimization delivered improvements ranging from roughly 1.3x to 3.3x in the tested configurations.
https://t.co/9MdEcsMuwH
RouteWeaver extends LLM routing beyond model selection.
It decides whether a request should use one model call, multiple sequential calls or an agentic workflow.
https://t.co/Iqn1BeoiQl
10 GitHub repos to turn you into a design/motion studio. 550K+ stars total
1. impeccable (85K stars)
Anti AI-slop design skill with 62 rule-based checks https://t.co/fRvXXvJPgA
2. UI UX Pro Max (139K)
Generates a full design system (pattern, palette, type) from a project brief. https://t.co/SjF04Unb01
3. MCP for Blender (32K)
Connect Blender to any LLM. Prompt-driven modeling and scenes.
https://t.co/Khc6ciBGxI
4. img2threejs (19K)
Rebuilds the object in a reference image as code-only, animation-ready Three.js. https://t.co/eHeTt9JoJm
5. video-shotcraft (13K)
Captures your real pages, picks from 150 shot recipes, renders a promo in Remotion. https://t.co/fH6tpaIvpT
6. HyperFrames (70K)
Write HTML, render MP4, built for agents. Has a /figma skill that pulls brand tokens into video. https://t.co/dg4f1HuYbr
7. Penpot (62K)
Open-source Figma alternative with an MCP server, so agents can read your design files. https://t.co/INryfNgf98
8. Remotion (67K)
Videos in React. The official skills repo teaches your agent how to use it.
https://t.co/fIultmJuwp
9. lemo-opuscar (6K)
59 film styles made entirely in code, no video model. https://t.co/bPmh8EVFie
10. diagram-design (60K)
Agent skill that outputs diagrams as one HTML+SVG file, onboarded to your brand's colors and fonts. https://t.co/ID3XZA0Ir3
Save this. Which one should I stress-test first?
New on our Frontier Red Team blog: using Claude to formally verify software at large scale.
Formal verification can prove that code is free of certain bugs, but historically it has only been feasible for small codebases (or required a lot of expert time).
With AI models, however, this is beginning to change. In collaboration with @theoremlabs, we used Claude to prove security properties in over one hundred real-world open-source libraries over the span of a few weeks.
Read our research in full here: https://t.co/zUyx8CjBEk
We’re adding support for MCP Tasks and Elicitations in Claude.
Tasks let Claude give plugins long-running jobs such as deep research and report back when they’re done.
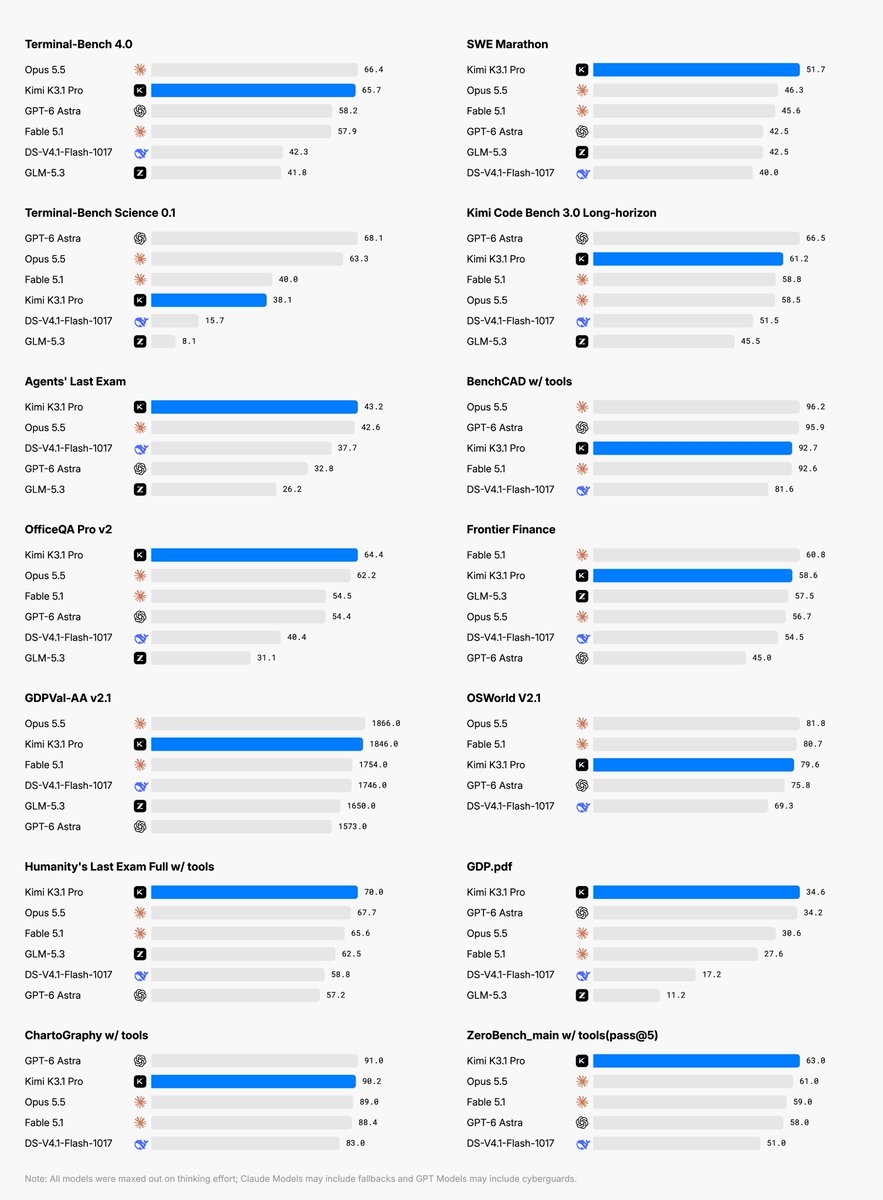
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6